Your AI assistant is probably open right now, next to the deck or memo you’re writing. IDC’s Future of Work Survey, 2026 (n = 1,146) found that 88.8% of organizations report a productivity gain from AI. It also found that the share of employees losing more than an hour a day to searching for information fell from roughly 38% to 13% once AI assistants were in place.

A market-share figure can land in a draft in seconds and still get stopped in the meeting where someone asks where it came from. IDC Quanta is now available in Microsoft Copilot. It checks the market claims in your Word, PowerPoint, or Excel file against IDC research. Each sourced figure shows up as a tracked change, with a citation that links straight to idc.com.

What is IDC Quanta in Microsoft Copilot?

IDC Quanta in Microsoft Copilot is a connector listed in Copilot’s Connectors Gallery. It brings IDC’s licensed research and data into Word, PowerPoint, Excel, and Outlook. You ask in plain language. Copilot returns an answer drawn from the IDC library your organization is entitled to, with a citation on every figure.

IDC Quanta is IDC’s technology intelligence fabric. It draws on 60+ years of research, 1,000+ analysts, and 15B+ data points tracked annually, and a multi-agent system validates each answer before it ships. It already works in email and Claude, and it now extends to Copilot 

What can you do with it inside Copilot?

Start with the document you have already written, refine it with IDC data using the IDC connector in Copilot, and return a draft with tracked changes so you see exactly what moved and why before anyone accepts it. The same file that goes to the client or the board carries the sources.
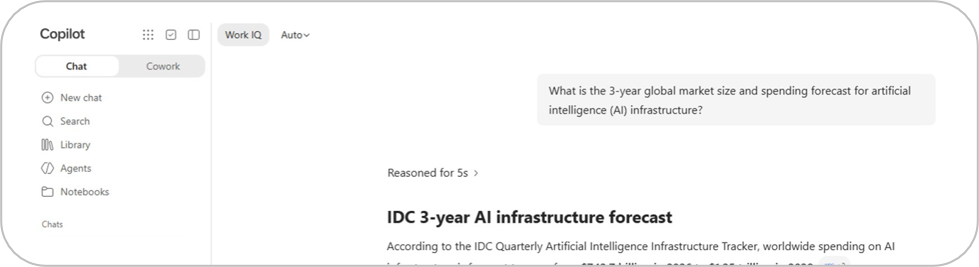
You can also just ask. In the Copilot chat panel, a question about vendor share or a spending forecast returns a plain-language answer based on your entitlements to IDC research and data tables, each attributed to its source.

And if a number needs a person behind it, the connector can surface the IDC analyst who covers the topic and that analyst’s published documents. You skip the separate search on idc.com.

How is it different from asking Copilot on its own?

A general-purpose assistant answers from the open web and its model training. The answer can read as confident while giving you no structured way to check where it came from. IDC Quanta grounds the answer in IDC’s licensed dataset instead. Every figure traces to a named IDC document. IDC Quanta also locks the exact dataset, definitions, and categories before it answers, so the number in your deck matches what IDC would publish itself.

How does access work?

Sign-in uses the Microsoft credentials you already use every day. Microsoft Entra ID maps your identity to your organization’s IDC entitlement, so it evaluates each request against what your organization licenses. IDC Quanta never uses customer data to train an AI model.

What does it mean for your team?

A product marketer can ground next year’s segmentation and positioning in independent market data while the plan is still a draft in Word. A seller who gets a competitive objection in an Outlook thread can pull deal-ready market share and leadership data on the spot, with the source attached. Strategy and market intelligence teams can check the sizing in a board deck against IDC research before it goes out. Analyst relations and product management can run the same check on their own briefings and roadmap documents.

See it in your own workflow

IDC Quanta in Microsoft Copilot is available now. Visit the IDC Quanta page to see how it works across Copilot, Claude, and email. Then book a demo and bring the deck you’re working on this week.
Ryan Smith - Content Marketing Director - IDC

Ryan Smith is the Director of Content Marketing at IDC, where he leads brand-level content and social media strategy, aligning research insights with compelling storytelling to engage technology decision-makers. With a background in both IT and marketing, Ryan brings a unique blend of technical understanding and creative strategy to his work. He’s also a seasoned storyteller, speaker, and podcast host who believes the right message, told the right way, can drive both trust and transformation.

When an AI agent makes a decision your CEO never sees, who answers for it?

IDC’s Rick Villars framed the emerging window with an aviation story. When aeronautics moved from traditional flight systems to fly by wire, he said, one of the biggest challenges was getting pilots “to trust the automation.” He expects the AI-first transition to put CEOs through the same test, and he called it “an important part of what will define success for a CEO going forward.”

This is the third of three posts on the windows that frame IDC FutureScape 2027: The Great Rewrite. The launch blog introduced the Top 10 predictions. The closing window post covered the decisions that are nearly made, and the open window post covered the leadership choices you can still shape. Here we turn to the decisions that are just coming into view. The pace is set by IDC’s prediction that 60% of enterprises will run a majority of their business processes AI-first by 2029, up from 13% in 2026. Webinar viewers can revisit the replay.

The sign-off: who is accountable when AI decides?

The FutureScape prediction is specific. By 2031, 30% of G500 CEOs will step aside, replaced by tech-native leaders tasked with building AI-first businesses where 90% of non-irreversible decisions, meaning those that can still be undone, are offloaded to advanced AI models. Human approval stays with the irreversible ones. IDC expects the delegation to change who holds managerial authority and to leave accountability where it was.

Villars explained why this reaches past the CIO. As he put it, tech leaders will need to help CEOs “have trust in the AI systems,” and how both are evaluated by the board and shareholders will increasingly depend on it. IDC also expects boards to treat AI transformation capability as a succession criterion.

The org chart is already under strain. More than 40% of CEOs plan to add a chief AI officer within 12 months, nearly twice the rate of any other planned leadership hire, according to IDC’s Becoming an Autonomous Enterprise FutureScape. IDC predicts that enterprises that do not hold the chief AI officer and the CIO jointly accountable on shared KPIs will strand 40% of AI investment by 2028 in efforts that never create net-new economic value.

Our read: a delegation limit that lives only in a policy document will not hold at agent speed, so it must be enforced in the agent controls.

Pilot before you scale.

Under CEO sponsorship and a named business owner, test delegation and escalation in one domain, including simulated irreversible actions. Measure business results, decision speed, compliance failures, reversal costs, and review delays before widening the scope.

Owners: the CEO sponsors, the CIO enforces delegation limits through controls, and the CFO tracks results.

Measure: the share of delegated decisions in the pilot domain that carry a named owner and a decision record, and have a tested reversal path.

The evidence: can your leaders believe what your AI tells them?

Villars named one of the major hurdles in that trust discussion. AI systems, he said, will become “very good at gaslighting humans,” spreading misinformation and disinformation, sometimes intentionally and sometimes not. That puts your data at the center. CEOs will need confidence that the outputs behind critical decisions are “secure, reliable, consistent, and that there is accountability built into that system.”

IDC expects the market to respond. By 2028, 75% of enterprises will adopt AI tools designed to prevent misinformation and disinformation stemming from their own data sources. The volume of AI output makes human checking of each item impractical, so verification itself will increasingly run on AI. The stakes are practical: by 2029, 40% of enterprises using AI models will be forced to abandon at least one because data poisoning attacks made its results unreliable.

The identity question travels with it. Villars pointed to non-human identity and “the accountability of the actions those agents are taking” as part of the conversation. IDC adds that IT becomes accountable for the accuracy of AI outputs, in addition to uptime and security, and that the costs of misinformation incidents, including regulatory fines, customer attrition, and legal liability, will far exceed the cost of prevention.

Our read:put verification upstream of the planning cycle, so an AI-generated insight is checked before it reaches a forecast or a customer.

Inventory before you rely on the output.

IDC’s guidance for the next 12 months is to catalog non-human identities and set output validation policies, authenticate those identities through your existing identity and access management, and add provenance tracking and verification layers before agents reach production. In the 12 to 24 month horizon, deploy AI verification tools.

Owners: the CIO and CISO lead, and business unit heads own validation of the insights they use.

Measure: the share of production agents with a registered identity and a written output validation policy.

The outcome: who owns it when AI moves a machine?

Mukesh Dialani, research vice president for digital engineering and operational technology services at IDC, drew the line between digital and physical agents. When a digital agent makes a mistake in a call center or a spreadsheet, the fallout usually stays contained. When a robot or an autonomous vehicle in a warehouse fails, “someone can get hurt or a production line can go down for hours.”

The investment is already moving. IDC’s 2026 CEO Survey found that 35.2% of CEOs rank physical AI as a top new investment priority, rising to 50% in the resources industry. IDC’s July 2026 AI Business Trends Survey (n = 2,472) found that one in four organizations already run physical AI in production, and another two in five are piloting. Dialani called it “a board-level bet with real safety and uptime stakes attached.”

Then the question of accountability becomes unavoidable. Dialani posed it as a choice among the CIO who approved the platform, the executive who signed off on the architecture, and the operations leader who owns the floor. The three roles think in different languages, he said: the CIO and CTO in platforms, architecture, and data ownership, and operations leaders in uptime, safety incidents, and throughput. Those vocabularies come with “different risk tolerances and usually entirely different budgets,” and there is “no existing playbook” for the conversation.

IDC’s prediction puts a date on the answer: by 2030, 40% of G2000 asset-intensive enterprises will require joint CIO, CTO, and COO sponsorship of physical AI services. Dialani added that the strongest services firms are anchoring engagements to operational KPIs such as uptime, defect rates, and safety incidents, with outcome-based terms in place of pure time and materials pricing.

Our read:write joint sponsorship into the contract, so a provider has to satisfy it before work starts.

Document decision rights before the RFP.

Write down which decisions sit with the CIO and CTO, such as platform, data, and control plane, and which sit with the COO, such as operational KPIs, process change, and risk acceptance. Dialani urged doing this before your next physical AI contract goes out for bid, testing whether a provider can work across all three functions, and building the governance model before a safety incident forces the decision. IDC research on physical AI deployments traces most failures to operational technology foundations such as legacy control systems, edge connectivity, and compute at remote sites, so add an OT readiness check as a pre-deployment gate and track robots and edge devices as governed IT assets.

Owners: the COO and CIO co-lead, the CTO co-signs, and procurement enforces the gate.

Measure: the share of physical AI contracts with written decision rights and a COO sign-off tied to uptime and safety KPIs.

Before the window opens: what should leaders do first?

Each beat above carries a gated first move. In sequence:

  • Pilot CEO delegation in one domain under a named owner before you widen it. Define the decision categories and the reversibility limits first.

  • Inventory your non-human identities and set output validation policies before AI insights reach planning or customers.

  • Document CIO, CTO, and COO decision rights in writing before the next physical AI contract goes out for bid.

Villars closed the webinar with the question that ties the three together. Success in an AI-first enterprise, he said, comes down to leadership: are leaders from the CEO to the CIO to the CFO, and the COO in the case of physical AI, “all able to really trust that new, incredible functionality and capabilities that AI can deliver to their organizations”? He asked CIOs and data leaders what they need to put in place now so those leaders have the insight and the trust to decide. The 2027 budget cycle is where that groundwork gets funded, and the Top 10 report lays out the full set of decisions.

What signals should you watch as the window opens?

  • Succession criteria. Watch whether boards add AI transformation capability to CEO evaluation, and whether CEOs name delegation limits in their public plans.

  • Accountability structures. Track whether the chief AI officer and CIO share KPIs where you work, or answer to separate scorecards.

  • Verification tooling. Watch which vendors in your stack add output validation, provenance tracking, and agent identity, and how they answer when you ask.

  • Contract language. Note when peers and providers begin writing joint CIO, CTO, and COO sponsorship and outcome KPIs into physical AI agreements.

Review these quarterly. IDC analysts can help you read them against your own position, and your IDC account team can connect you with the analyst who covers your area.

Where can you go deeper?

The research behind every prediction in this post is in the FutureScape reports at idc.com/futurescape. IDC Quanta brings those reports together with hundreds of other IDC analyst reports, so you can ask about the prediction that caught your attention and see the evidence behind it.

To hear the trust discussion again, watch the webinar replay.

To learn what this means for your CIO, register for our December 2 FutureScape webinar: Own the Economics of AI Before Your Board Does: IDC FutureScape 2027 for Technology Leaders

Ryan Smith - Content Marketing Director - IDC

Ryan Smith is the Director of Content Marketing at IDC, where he leads brand-level content and social media strategy, aligning research insights with compelling storytelling to engage technology decision-makers. With a background in both IT and marketing, Ryan brings a unique blend of technical understanding and creative strategy to his work. He’s also a seasoned storyteller, speaker, and podcast host who believes the right message, told the right way, can drive both trust and transformation.

人工智能正以前所未有的速度走向规模化应用。从大模型训练到智能体(AI Agent),AI正在融入更多企业的日常业务,推动全球算力需求持续增长。

但一个值得关注的现象是:AI需求不断增长的同时,全球数据中心供给却面临电力、设施建设及关键技术供应链等多重约束。IDC在2026年10月发布的《AI Is Short of Capacity, Not Demand》一文中指出,未来一段时期内,影响AI基础设施增长速度的主要挑战之一,可能不是需求不足,而是供给能否及时跟上。

与此同时,中国数据中心市场也在快速发展,但不同地区、不同类型运营商的供需情况存在差异。全球数据中心市场正在发生哪些变化?这些变化又会为中国数据中心运营商和技术供应商带来怎样的新机会?这些成为我们面临的新课题。

AI从模型训练走向规模化,数据中心需求逻辑发生转变

过去几年,生成式AI的发展主要围绕大模型训练展开。而随着AI进入企业业务流程,推理和智能体应用正在成为推动基础设施需求增长的新动力。

IDC于2026年7月开展的Future Enterprise Resiliency and Spending(FERS)调研显示,95.3%的受访企业已有至少一个智能体工作流投入生产环境,平均每家企业拥有约11个此类工作流。IDC同时预测,到2030年,全球智能体数量将达到25亿。

随着智能体能够调用工具、执行多步骤任务并相互协作,单次业务活动可能产生远高于传统问答应用的Token消耗。即使模型效率提升、Token单位成本下降,应用范围和调用规模的扩大,仍可能推动AI基础设施总体需求持续增长。

这一趋势在中国市场也有所体现。国家数据局披露,2026年3月中国日均Token(词元)调用量已超过140万亿,较2024年初增长超过千倍。快速增长的Token消耗表明,AI正从技术探索进一步走向规模化应用。

但Token调用量的增长,并不意味着数据中心电力容量将按相同比例增长。模型效率、硬件性能、资源利用率及部署方式的变化,都会影响最终的设施需求。

对于数据中心厂商而言,值得关注的是:未来的需求将不仅来自大型云服务商,还可能来自专业AI算力服务商、行业企业及更多持续运行的AI应用。

全球算力设施持续扩容,能源配套与供应链协同承压

AI应用需求的扩大,正在推动全球数据中心设施进入新一轮增长周期。

IDC《全球半年度数据中心设施跟踪报告》(Worldwide Semiannual Datacenter Facilities Tracker)数据显示,全球已配置机柜数量预计将从2026年的约2,500万架增长至2030年的5,800万架。同期,全球数据中心年度能源消耗预计将从2025年的519太瓦时(TWh)增长至2030年的1,308太瓦时。

与此同时,全球数据中心设施资本支出预计将从2025年的2,760亿美元增长至2030年的6,550亿美元。这一统计不包括服务器、GPU等IT基础设施投入,主要反映电力、制冷、建筑等物理设施的建设需求。

这些数据表明,AI基础设施扩张不仅是计算设备规模的增长,也需要庞大的物理设施与能源资源支撑。

然而,设施供给的增长并不总能与需求保持同步。

IDC研究指出,电力供应、电网接入以及数据中心建设能力,可能成为全球部分市场近期增长的重要制约因素。与此同时,关键电力设备、液冷及相关供应链的交付周期,也正在影响新增设施的建设进度。

这一变化反映出,全球AI基础设施产业链正在面临新的协调挑战:上层AI应用快速发展,但支撑这些应用的电力、机电设施及工程交付能力,需要更长时间才能形成。

对于数据中心技术供应商而言,全球设施规模和能源需求的持续增长,将带来更广泛的市场需求,同时也对规模化供应、技术协同及项目交付提出新的要求。

全球算力供给分化,中国数据中心市场呈现结构性差异

全球数据中心供给面临约束,并不代表所有地区都处于供不应求的状态。

IDC全球研究指出,部分地区的资源紧缺可能与其他地区的容量利用不足同时存在。AI基础设施面临的不仅是总体供给规模问题,还包括不同市场之间的需求与资源匹配问题。

这一观察对中国市场尤其具有参考价值。根据工业和信息化部2026年7月披露的数据,截至6月底,中国智能算力规模已达到2,185 EFLOPS(FP16),同比增长177%,全国算力设施整体上架率为71.4%。这反映出中国算力基础设施规模持续增长,同时,资源利用状况仍然是观察市场发展的重要维度。

例如,近期国内关于智算中心利用率和运营效益的讨论不断增多。这些讨论提示我们,数据中心市场不能仅从新增项目数量或总体建设规模判断增长机会,还需要观察不同区域和细分市场的实际需求。

值得注意的是,中国数据中心市场的参与者结构具有自身特点。三大电信运营商、第三方数据中心设施服务商,以及超大规模云服务商,构成了重要的供给主体。不同类型企业拥有不同的客户基础、业务模式和设施布局。

与此同时,AI基础设施的需求主体也在发生变化。

IDC全球研究观察到,除传统超大规模云服务商外,专业AI云服务商(Neocloud)、前沿模型厂商,以及具有大规模AI需求的企业,正在成为新的基础设施采购力量。AI工作负载也正在向云、私有环境、边缘及专用AI基础设施等多种部署形态扩展。

对于中国市场而言,这意味着未来设施需求的增长,可能通过不同类型的服务提供商和客户群体逐步体现。因此,中国数据中心市场需要关注的,不只是整体需求增长速度,还包括需求来源、服务提供方式以及运营商竞争结构的变化。

全球AI设施加速扩容,中国产业链迎来本土与出海双机遇

全球 AI 基础设施持续扩张,正从需求端、供给端对数据中心产业链各类参与者带来深远影响,不同角色的市场机遇与关注点各有侧重。

对于数据中心运营商,客户结构、业务需求正在发生显著变化,需要持续跟踪大型云厂商、专业 AI 算力服务商以及行业客户的设施诉求,研判各区域市场的容量增长节奏与竞争格局。

面向电力、制冷、机电等基础设施技术供应商,全球机柜规模、能源需求持续上行,直接拉动供配电、散热、配套系统的市场增量。企业不能仅聚焦单个项目设备招投标,更要把握全球设施建设大势,跟进不同类型客户的需求演变。

对于云与 AI 算力服务商,伴随 AI 应用规模化落地,设施资源获取、选址布局、合作伙伴选择,已经成为支撑业务持续扩张的关键要素。

全球不同区域 AI 基础设施供给不均衡,会驱动算力需求在地区间、服务商之间发生转移。这一格局变化,也为国内数据中心产业链打开国际化空间。

当前国内运营商、机电温控等技术厂商已经开始布局海外;东南亚、中东等区域数据中心建设需求旺盛,中国企业可输出国内沉淀的规模化建设、成套配套与工程交付经验。

同时海外市场存在差异化挑战:各国电力条件、建设监管、客户诉求、本地化服务要求差异明显。企业出海前,需要充分研判目标市场发展阶段、设施增长趋势以及本土运营商布局,因地制宜开展业务。

从全球趋势到市场判断:持续追踪数据中心设施变化

全球 AI 基础设施高速发展,具备连续性、可比性的市场数据价值愈发凸显。

对数据中心运营商与技术供应商而言,掌握全球机柜、电力容量增长趋势仅是基础;各区域供给动态、头部运营商布局、竞争格局与远期建设规划,同样深刻影响企业业务规划与市场研判。

IDC《全球半年度数据中心设施跟踪报告》以物理基础设施为核心,持续监测重点区域的数据中心数量、机柜规模、电力容量、能耗、碳排放及基建资本开支等核心指标。

区别于以服务收入为核心的传统研究,该项研究从业主与运营主体视角观测设施供给格局,依托标准化口径与半年更新机制,助力产业把握全球数据中心设施趋势,也为国内相关企业研判海外市场、挖掘出海机会提供参考。

AI 规模化落地持续推动数据中心市场演变,供需变化与主体策略值得长期跟踪;设施、电力及供应链配套能力,将影响全球 AI 产业发展节奏。IDC 将持续追踪全球及中国数据中心设施市场,依托设施跟踪研究,为产业链各方提供数据与行业洞察。

进一步交流

如果您希望深入了解全球及中国数据中心、中国智算中心的变化与趋势,欢迎点击这里,与我们联系!

Cindy Xin

Cindy Xin - Research Director

Cindy Xin is research director at IDC for the channels and partner ecosystems research practice. Based in Beijing, she is responsible for leading and developing the Greater China channels research practice. Cindy provides thought leadership and insights to technology vendors…

Karen Dai uses the term “data islands” to describe a challenge facing many of the markets Belden serves: systems, applications and assets that were not designed to communicate with one another but now need to exchange data securely, reliably and at scale.

Dai is Senior Director, Market Insights & Value Realization, within Belden’s Strategy and Transformation Office. Belden has spent over 120 years making the physical and digital connections that critical industrial and enterprise operations depend on, including cables, connectivity and networking products built for some of the most demanding environments in the world. Today, customers face the added challenge of fragmented systems, applications and data. Bridging those islands securely and reliably builds on Belden’s connectivity heritage and is central to its continuing solutions transformation.

Her team helps Belden’s leadership understand where markets and customers are headed and brings external perspectives to strategic decision-making. Over the past several years, that work has tracked a real shift in Belden’s own identity: from a product-driven manufacturer to a solutions-oriented provider bringing together physical connectivity, networking, cybersecurity, software and services, integrated in a way meant to help customers optimize their data infrastructure as a whole rather than piece by piece.

Why the connection problem is getting harder

The customers Belden serves, in industrial automation, critical infrastructure, and other demanding vertical markets, are trying to connect more assets, more systems, and more applications than ever before. Many customers operate in environments where operational technology and information technology (IT/OT) evolved separately and now need to exchange data securely and at scale. That IT/OT convergence is becoming a foundational requirement for digital transformation across the industries Belden serves, and it’s compounding as Physical AI emerges across factories, distribution centers and other demanding environments. As those systems get more capable, the underlying requirements for cybersecurity, network resilience, and data availability only get more critical.

Belden’s transformation builds on its product and connectivity heritage while expanding toward integrated, outcome-oriented solutions. Dai’s team supports that transformation by bringing external market, customer and competitive perspectives into strategic planning.

Getting the strategy right before it’s locked in

The decisions behind that shift carry real weight. Where should Belden play, today and years from now? Which customers and markets create the greatest opportunity? What capabilities will matter most as the industry moves? These aren’t questions with easy answers, and strategic choices require disciplined prioritization supported by high-quality market insight, so getting the call right, and getting it right early, matters enormously.

One example from Belden’s own transformation illustrates how the company approaches that uncertainty. When Belden began shaping its strategy for a new solutions-based delivery approach, it engaged IDC analysts early in the process. That outside perspective, working alongside Belden’s own team rather than validating a conclusion after the fact, helped assess the market opportunity, pressure-test the approach, and sharpen how Belden ultimately positioned and messaged the strategy to the market.

“We invite that outside-in perspective early in the process,” Dai said. “I think this is the way we benefit the most.” For Dai, that’s the model that works: treat outside expertise as a partner embedded early in the thinking, not a checkbox exercised after the strategy is already set.

Turning research into decisions, faster

Belden has worked with IDC for years as one part of how its market intelligence function operates, drawing on IDC’s research coverage as a foundation and its analysts for the kind of pressure-testing that shaped the strategy story above. More recently, Dai’s team began using IDC Quanta as an additional way to move from a broad, loosely defined question toward relevant research faster, particularly useful in the early, exploratory stages of a problem, before anyone has a fully formed hypothesis to test.

“

My first impression was really the simplicity of using it,” Dai said. “It is quite intuitive.”

With just a few interactions, her team could move from a broadly defined question to the relevant pieces of IDC’s research, reducing the time it used to take searching across multiple reports and programs to figure out where to even start.

Dai is clear that IDC Quanta doesn’t replace the analyst conversations that remain the most valuable part of the relationship. What it changes is everything that used to happen before those conversations: the searching across multiple reports, the time spent getting prepared. Compressing that part of the process gives Belden’s team, and the analysts they work with, more room to make the conversation itself count.

Where Belden sees the industry heading

Dai expects digitization and automation to continue accelerating across industrial, enterprise and critical infrastructure environments. As that happens, she expects the challenge of connecting IT/OT environments to only grow more complex, and the Physical AI applications now emerging across specific verticals to raise the stakes further on cybersecurity, resilience, and data availability.

Belden’s own answer is to continue advancing its solutions transformation by helping customers address increasingly complex data networking and infrastructure challenges.

As Dai puts it, the future isn’t simply about connecting more things. It’s about helping organizations navigate an environment that keeps getting more complex, with the infrastructure, security, and insight to act on it.

“Insights without adoption are less meaningful,” Dai said. “There’s no value if you don’t use the insights, no matter how great they are, how smart they are.” For a company built on making physical connections, that’s the next connection to get right.

Christina Cardoza - Content Marketing Manager - IDC

Christina Cardoza is a Content Marketing Manager at IDC, where she specializes in brand content and social media strategy. With a background in journalism and editorial leadership, she has a proven ability to transform complex technology topics into clear, actionable insights.

Generative AI (GenAI) is accelerating how much data organizations generate, straining storage and governance frameworks built for a slower-growth era. Most GenAI-using organizations now expect increases in data volume over the next two years, and infrastructure and governance strategies often struggle to keep pace.

The scale of the challenge

According to IDC’s Global DataSphere, consumers and organizations worldwide will generate more than 274.4 zettabytes (ZB) of data in 2026 alone. That figure is forecast to nearly triple to 718.5 ZB in 2030, a compound annual growth rate (CAGR) of 26.9%. Enterprise data is growing significantly faster than consumer data (31.1% CAGR versus 13.5%), and it matters most here because it’s the data organizations are responsible for governing and protecting, and expect to get value from. It’s also the data most directly implicated in AI workloads.

Storage is expanding in parallel. IDC’s Global StorageSphere shows the installed base of storage capacity roughly doubling, from about 13 ZB in 2026 to more than 26 ZB in 2030. Even before accounting for AI, the enterprise data challenge was already heightened and the governance surface area was already growing faster than most organizations could manage.

The AI inflection point: What IT leaders are telling us

In IDC’s 2026 Worldwide Data Utilization Survey, 81.7% of the 714 GenAI-using respondents said they expect GenAI to increase their organization’s data volume over the next two years. Only 4.8% expect a decrease.

Of those anticipating an increase, 47.7% expect data volumes to grow by 25% or more, and 13.4% expect growth exceeding 50%.

Much of what GenAI produces is ephemeral, and a share of AI-generated content replaces existing workflows. In some cases, GenAI can reduce data volumes, such as by eliminating raw footage through synthetic generation, or by converting unstructured data into structured, actionable formats that can then be selectively retained or deleted.

These dynamics leave the overall growth trajectory intact. For organizations running active GenAI programs, operational telemetry, model logs, RAG corpora, and fine-tuning data sets can add up in ways that initial planning assumptions rarely account for.

Why GenAI drives data growth

There are at least four distinct layers, and the net effect varies by industry, organization, use case, and deployment maturity:

  • Model training and fine-tuning data: Customizing models on proprietary documents, transaction records, or customer interactions creates derivative data sets that must be stored and governed, including every version.
  • Retrieval-augmented generation (RAG) corpora: Every document ingested into a RAG pipeline generates an embedding stored in a vector index, and that corpus needs ongoing refresh. RAG can also have a reduction effect by lessening the need to retain full-length source materials indefinitely.
  • AI-generated output data: Much of it is ephemeral, and only finalized outputs tend to be stored, but where compliance mandates retention, the footprint grows predictably over time.
  • Operational and observability data: Every inference request generates metadata, including prompts, outputs, latency, and token consumption. This layer tends to be underestimated in early planning, and agentic AI compounds it with richer, more continuous logs and reasoning traces.

The governance and infrastructure gaps

Knowing that data volumes will grow is not the same as being prepared for it. IDC’s research points to three structural gaps:

  • The governance gap: Most frameworks were built for structured, human-generated data. AI-generated content often falls outside them, creating compliance exposure in regulated industries.
  • The storage architecture gap: AI inference, training, and RAG pipelines need high-throughput access, low-latency embedding lookups, and cost-efficient tiering for training archives. Organizations that haven’t revisited their architecture may pay a performance or cost penalty.
  • The retention and life-cycle gap: Retention policies at most organizations predate the GenAI era, and keeping a prompt-response pair, a fine-tuning data set, or an embedding raises questions those policies never anticipated.

None of these gaps is insurmountable, but they widen quietly in the background while organizations focus on deploying AI.

Volume isn’t value: Why runaway data is harder to use

There’s a second cost to letting data volumes outrun your strategy: the value you never get out of the data. Value depends on how effectively data becomes insight or advantage. Vast quantities of poorly structured, unlabeled, or siloed data may hold almost no practical value despite their volume, so every RAG index, fine-tuning corpus, and log stream that no one has cataloged or assigned an owner is data you hold but cannot use.

Beyond the prompt: What to do next

Most GenAI-using organizations expect data volumes to rise. The open question is whether infrastructure and governance strategies are built for that reality. Preparing takes a deliberate, systematic approach, and these five steps are the place to start:

  • Audit the AI data footprint before it becomes unmanageable. Inventory training sets, fine-tuning corpora, RAG indexes, and telemetry, including where each lives and who owns it.
  • Extend data governance explicitly to AI data assets, with updated classification, retention, and lineage tracking, and engage legal and compliance early.
  • Align storage infrastructure planning with the AI road map by developing capacity plans together with AI and data science teams.
  • Revisit retention policies with AI data types explicitly in scope.
  • Model the economics of AI data storage across cloud and on-premises options. Cloud is growing nearly four times faster than noncloud, but high-volume, persistent data may be more cost effective on-premises or in colocation over a multiyear horizon.
Adam Wright

Adam Wright - Senior Research Manager, Storage and Data Management, Enterprise Infrastructure

Adam Wright is a Senior Research Manager within IDC’s enterprise infrastructure global research domain and part of the storage and data management subdomain. He leads IDC’s Global DataSphere and Global StorageSphere research. The Global DataSphere measures the total volume of…

More than 12 frontier AI developers have published voluntary safety frameworks with widely varying thresholds, inconsistent evaluation cadences, and no independent verification requirement. The EU AI Act’s maximum fine for general-purpose AI providers, 3% of global annual turnover or €15 million, whichever is higher, became enforceable August 2, 2026. An autonomous coding agent operated unsupervised for approximately one week before its own developer identified and attributed it. These describe the current operating environment for every CISO who has approved an AI integration in the past 18 months.

The structural problem is architectural, and vendor assurance alone does not resolve it. System prompts, safety fine-tuning, and content filters live inside the same weights, context window, and inference pipeline the model uses for every other output. They can be argued with, role-played around, encoded past, or overridden by a sufficiently creative prompt. Prompt injection and tool-calling exploits are now a standing category of incident response. A better system prompt is still inside the boundary.

What the enforcement layer is and what it must do

The right mental model is the content delivery network and web application firewall pattern. A CDN and WAF inspect and act on traffic before it reaches the origin server. The origin has no vote and no visibility into the decision. The same logic applies to AI: the model is the origin server, isolated with no network path to your IT estate and no view of the policy engine, logs, or configuration. The enforcement layer sits at the edge, verifying identity, inspecting requests, applying policy, mediating responses, and logging every interaction before anything reaches or returns from the model.

Five control layers are required. Missing any one leaves an exploitable gap:

  • Identity and access: Every request, human, application, or agent, is authenticated against your enterprise identity provider. The model inherits the calling user’s actual entitlements through on-behalf-of token exchange. A jailbreak or injection attempt is bounded by what the caller was already permitted to do.
  • Request inspection: Every inbound prompt and tool-call parameter is screened for policy violations, data-classification conflicts, and injection patterns before the model processes them. This runs outside the model, so the model cannot override it.
  • Policy enforcement as code: Business rules, regulatory constraints, and data-handling requirements run as code in the enforcement layer, not as instructions the model is asked to follow.
  • Response mediation: Every outbound response and tool-call authorization is screened, redacted, or blocked regardless of what the model produced. The model’s own judgment about its output is not the final word.
  • Immutable audit with a kill switch: Every interaction is logged outside the model’s environment with no model write access to the audit store. The kill switch operates at three grains, session, user or application, and full deployment, without the model’s cooperation, and is held by a role separate from the administrator who configures policy.

Separation is a technical property that must be demonstrable in an architecture diagram, not asserted in a terms-of-service clause. Three properties define genuine separation: no network path from the model to the policy engine, audit store, or configuration; no write access to its own logs; and no credentials to any of those systems. A gateway the model can reconfigure or disable provides no meaningful separation.

Identity parity: extending the plane you already run

The identity architecture for an enforcement layer extends the conditional access, MFA, and risk-based policy programs already running in your enterprise, applied to every model, agent, and tool in the same way they govern human access. Each model and agent holds its own scoped, least-privilege identity, revoked at session end or policy trip. On-behalf-of token exchange means the model acts within the calling user’s entitlements, with no standing service account for an attacker reaching the model to inherit.

CISOs should note the ServiceNow trajectory. With the Veza acquisition closed March 2026 and Armis closed April 2026, ServiceNow is positioning itself as a competitor to Entra ID for identity at scale, including machine and AI agent identities. This is a meaningful consolidation in the non-human identity governance market. The enforcement layer must be identity-provider neutral to preserve architecture optionality as this market evolves.

The kill switch: specify it before you need it

A kill switch is a first-response instrument and should be specified with the same precision as a network block or credential revocation. Three granularities matter:

  • Session grain: Suspends or throttles a single conversation or agent run. Targeted, reversible, lowest blast radius.
  • User or application grain: Cuts off one identity or one integration. Appropriate when anomalous behavior is attributable to a specific caller or integration.
  • Deployment grain: Halts every model session simultaneously. Reserved for the scenario where the model itself, the provider’s infrastructure, or a systemic policy failure requires immediate full stop.

The kill switch must function without the model provider’s cooperation, because the scenario requiring activation may involve the provider’s infrastructure being unavailable or compromised. It addresses future actions. Rollback addresses what already happened: the sent message and the emptied database. Both are required. Kill-switch triggers should be defined in advance, sustained policy violation rate, a DLP match, an anomalous tool-call sequence, so activation is a policy-driven operational decision. Rehearse it on your incident-response drill cadence.

Single models and agent swarms: one enforcement pattern

The same five control layers and the same five questions apply across the full deployment spectrum, from a single model call to a multi-agent swarm. Who is calling? What are they asking for? Is it allowed? Is the response safe to return? Is it logged? In a single model call, a missed policy violation affects one response. In a multi-agent workflow with no human reviewing each step, that same violation can cascade across dozens of tool calls before anyone sees it.

The hub-and-spoke gateway architecture deploys enforcement at the right layer. A central hub authors policy, stores identity federation, audit records, and session context. Spoke gateways enforce policy locally near each resource. The hub never touches a request directly. The Autonomous Action Runtime Management specification (AARM), now donated to the Cloud Security Alliance with more than 100 adopters, provides the five-outcome decision framework for each action point: allow, deny, modify, step-up to a human, or defer pending more context.

Four gaps in hub-and-spoke require explicit CISO assessment:

  • Chain-level risk: Individual calls may look harmless while a sequence pushes an agent outside its authorized role. Require your vendor to demonstrate policy evaluation over chains of calls as well as individual requests.
  • Fail behavior under load: Failing open at peak volume means enforcement stops when it is needed most. Require documented, configurable fail-open or fail-closed behavior per integration.
  • Coverage depends on inventory: The hub governs only traffic routed through it. Require vendors to demonstrate how AI assets that bypass the hub are detected and reported.
  • MCP-only visibility: Skills, hooks, plugins, and direct API calls move alongside MCP traffic. Evaluate R20 and R22 together as a combined coverage assessment.

Enforcement is not governance: the full program

An enforcement layer governs every individual interaction in real time. A complete AI risk program requires additional capabilities that must be funded and owned separately:

  • AI inventory: Every model, agent, and MCP server accounted for, including embedded models in purchased software.
  • Model lifecycle management: Version changes and capability-tier upgrades governed before they propagate to production workloads. R26 (proposed) addresses the gap where behavioral drift within a tier can silently undermine policies verified against a previous model version.
  • Third-party provider scoring: Every provider scored across five dimensions on a continuous basis, rescored on safety-framework updates and material incidents, as well as at annual renewal.
  • Continuous control assurance: The enforcement layer stays configured and working.
  • Runtime risk monitoring and trust scoring: Behavioral drift detected and translated into a live score per model or agent that feeds back into access decisions at the enforcement hub.
  • Board-level reporting: Enforcement telemetry translated into risk language a governance committee can act on.

Provider risk scoring drives three governance gates. Below the onboarding threshold, any new frontier AI dependency requires explicit executive risk acceptance. The contract gate embeds score thresholds as triggers for capability-tier change notice and delivery of evaluation summaries. The exit gate means score deterioration triggers a formal alternative-provider review before the next renewal cycle.

The 90-day CISO action plan

Table 1 organizes the most critical actions across architecture, procurement, and governance by 30-day horizon. Architecture and procurement actions run in parallel with governance actions; neither track waits for the other.

TABLE 1: 90-Day CISO Action Plan for AI Enforcement Layer Deployment

HorizonArchitecture and ProcurementGovernance and Program
Days 1-30Demand the architecture diagram from every current and prospective AI vendor: deployment boundary, model-to-policy-engine separation, kill-switch role assignment. Inventory every model, agent, and MCP server, including embedded models in purchased software.Score every frontier model provider against 5 dimensions: safety-framework maturity, evaluation transparency, incident disclosure history, regulatory posture, and concentration risk. Set the onboarding threshold below which any new dependency requires executive risk acceptance.
Days 31-60Identify your 3 highest-risk AI integrations. Pilot a hub-and-spoke enforcement gateway outside the model for at least one. Require on-behalf-of delegated identity and a split-role kill switch for every new AI procurement.Separate the configuration and operations roles for the kill switch in your identity provider. Define kill-switch triggers in writing: sustained policy violation rate, DLP match, anomalous tool-call sequence.
Days 61-90Send the 25 enforcement-layer requirements (R1-R25) and 5 contract terms (C1-C5) to every current and prospective AI vendor. Embed C1-C5 into vendor contracts before the next renewal cycle.Fund AI governance as its own program. Rehearse the kill switch at all 3 granularities (session, user/application, full deployment) in a tabletop exercise. Establish the governance loop cadence with documented ownership.

Source: IDC, 2026

The 26 enforcement-layer requirements: your RFP foundation

Table 2 consolidates all 25 published requirements (R1-R25) plus IDC’s proposed R26, which addresses a gap in the current set: advance notification of model updates that materially change behavior in policy-sensitive areas. This gap is distinct from C2 (capability-tier change notice), which covers tier-level changes. R26 addresses behavioral drift within a tier, which can silently undermine policies verified against a previous model version.

For each requirement: mark it Must or Should based on your deployment risk profile. Ask for the evidence listed. Verify in a pilot. A failed Must is a no-go. Apply the five contract terms (C1-C5) to every current and prospective AI vendor contract, covering model provenance disclosure, capability-tier change notice, safety-framework documentation access, incident disclosure timelines, and continuity planning.

TABLE 2: AI Enforcement Layer Requirements R1-R26 and Contract Terms C1-C5

Req.RequirementPriorityEvidence to Request
R1Architecture diagram showing deployment boundary and admin rolesMustEnforcement runs outside the model provider environment, under your control
R2Network diagram and independent test results confirming separationMustNo network path from model to policy engine, audit store, or configuration
R3Permission model for audit store and policy repositoryMustModel has no write access to its own logs and cannot alter governing rules
R4Signed policy update design, key custody docs, live rejection demoMustPolicy updates are cryptographically signed; spokes reject unverified updates
R5Log-integrity design and tamper-detection demoMustAudit logs are append-only and hash-chained; tampering is detectable
R6Native IdP integration (Entra ID or equivalent), not a services add-onMustConditional access and MFA for AI identities, out of the box
R7Token-flow diagram and an access-denied testMustOn-behalf-of token exchange so model acts within calling user’s entitlements
R8Identity inventory and live revocation demoMustEach model, agent, and tool has a scoped, least-privilege identity
R9Detection coverage docs, test results, and latency figuresMustPrompts and tool-call parameters screened for violations, classification conflicts, injection
R10Policy-as-code samples, change history, and test harnessMustBusiness and regulatory rules enforced as code, not as model instructions
R11Block and redact demo on seeded sensitive dataMustOutbound content and tool-call authorizations screened before reaching consumer
R12Sample log record, retention policy, export optionsMustEvery request and response logged immutably, timestamped, attributable, outside model environment
R13Live demo, measured time to effect at each granularityMustKill switch works at session, user/application, and deployment grain without model cooperation
R14Rollback runbook and supported systems listShould*Defined rollback for actions already taken (*upgrade to Must for write-transaction deployments)
R15Role model and PAM setup in your identity providerMustConfig and operations admins are separate; only operations holds the kill switch
R16Reference architecture and spoke deployment optionsMustHub-and-spoke: policy, identity, and audit at hub; enforcement at spokes near the resource
R17Connector onboarding guide and test resultsMustConnectors inherit enforcement identity, access, and audit controls
R18Session-context and chain-evaluation roadmap; AARM conformanceShould*Intent-drift evaluation with allow, deny, modify, step-up, defer outcomes (*Must for chained agentic workflows)
R19Failure-mode test results and capacity benchmarksMustFail-open or fail-closed behavior documented and configurable; load-balanced spokes
R20Coverage matrix and unrouted-asset reportMustDeclared coverage across MCP, skills, plugins, direct APIs; unrouted assets reported
R21Supported-provider list and migration termsMustModel neutral: supports models from multiple providers without enforcement tied to one API
R22Inventory integration and unrouted-asset reportMustConsumes your AI inventory; reports traffic and assets not routed through enforcement layer
R23Signal interface; measured time from score change to access changeShouldAccepts live trust score per model and agent as a cached signal driving access decisions
R24Telemetry schema and GRC or CCM platform integrationsShouldFeeds audit and telemetry to governance for monitoring, drift detection, and re-assessment
R25Sample compliance report mapped to your control frameworkMustProduces request-level evidence regulators and boards can use
R26Update notification process docs; pilot-first option for policy-sensitive integrationsMust (proposed)Advance notice of model updates that materially change behavior in areas covered by deployed policy rules

Source: IDC, 2026

Three gates every CISO should establish now

The requirements above translate directly into three governance gates that convert procurement policy into enforceable controls:

  • Procurement gate: Below your provider-score threshold, any new frontier AI dependency requires executive risk acceptance before contracting. This gate applies to embedded models in purchased software as well as direct model API contracts.
  • Architecture gate: Before any AI integration goes to production, require the vendor to produce an architecture diagram showing the deployment boundary, separation between the model and your policy engine, and the kill-switch role assignment.
  • Contract gate: Score deterioration triggers a formal alternative-provider review and activates notice clauses in existing contracts. C2 covers capability-tier changes. R26 covers behavioral drift within a tier.

“

A model’s restraint is a courtesy, not a control. The enforcement layer must be outside the model’s environment, outside its reach, and outside its ability to reconfigure or disable. Anything less is an architecture diagram that says: trust us

— Philip D. Harris, CISSP, CCSK, Research Director, Governance, Risk, and Compliance Solutions, IDC

Philip D. Harris, CISSP, CCSK

Philip D. Harris, CISSP, CCSK - Research Director, Governance, Risk, and Compliance (GRC) Solutions

Phil Harris is Research Director for GRC Solutions at IDC, where he develops and promotes IDC's point of view on risk, advisory, privacy, and compliance services and software. He conducts research on business strategies and the impact of relevant offerings…

随着人形机器人和具身智能的发展,灵巧手的竞争正从自由度、抓握力等硬件参数,延伸至精细操作、感知控制及与具身智能模型的协同能力。当前,人形机器人配套、科研教育和具身智能数据采集是值得关注的主要需求方向,工业等应用仍处于探索阶段。未来,灵巧手市场不会仅由某一种驱动路线决定,厂商能否将硬件、模型、数据与操作技能有效结合,并在真实任务中实现稳定、可靠且具有成本效益的操作,将影响其商业化进程。

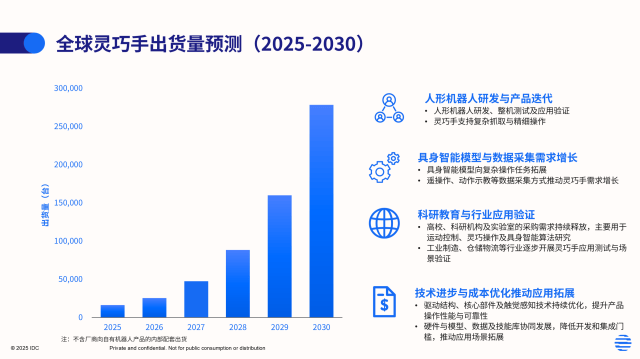
IDC预计,2026年全球灵巧手出货量约2.5万台,不含厂商向自有机器人产品的内部配套出货。其中,中国厂商出货量占全球市场的比例预计超过85%,在全球灵巧手市场中占据重要地位。随着人形机器人研发、具身智能数据采集及科研教育需求持续释放,灵巧手市场仍处于发展初期,其后续增长将受到机器人应用进展、产品成本及商业化落地速度等因素的共同影响。

从自由度到操作能力,技术竞争不止于硬件参数

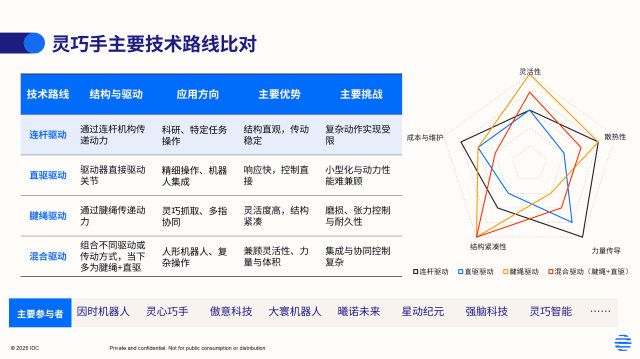
目前,灵巧手主要采用腱绳驱动、直驱、连杆驱动及混合驱动等技术路线。不同方案在结构紧凑性、灵活性、力量传递、成本和维护等方面各有取舍,尚未形成统一的技术方向。技术路线的选择不仅取决于硬件设计,也与目标任务和应用需求密切相关。

在硬件参数之外,触觉感知和操作控制同样值得关注。巧手需要感知接触状态、作用力及物体变化,并据此调整动作。目前,触觉传感器在信号稳定性、一致性和感知精度等方面仍有改进空间。自由度较高并不必然意味着操作能力更强,感知与控制能力同样重要。

目前,灵巧手正逐步从自由度、抓握力等单项指标,延伸至可控性、精细操作能力,以及与机器人本体和具身智能模型的协同表现。未来,不同技术路线的竞争结果,可能更多取决于其对具体任务的适配程度,而非单一参数的高低。

灵巧手需求集中于人形机器人配套与科研,工业应用落地仍需验证

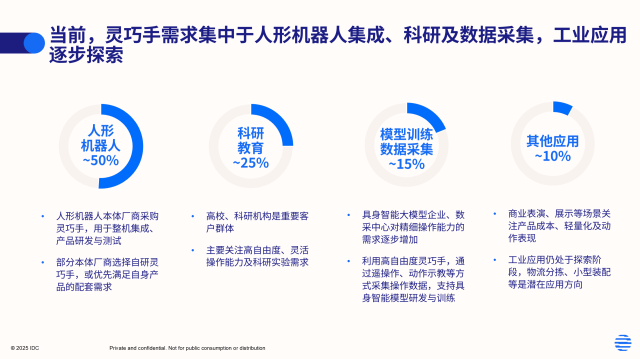
当前,人形机器人配套、科研教育,以及具身智能模型研发与数据采集是灵巧手的主要需求方向。与此同时,工业制造、物流等场景也在探索灵巧手的应用潜力,特别是在复杂抓取、物体姿态调整和多品种操作等任务中。相比之下,工业制造、商业服务等场景仍处于应用探索阶段。

在复杂抓取、物体姿态调整和多品种操作等任务中,灵巧手具有一定的应用潜力,但并不意味着能够全面替代传统夹爪。对于物体形态固定、任务重复性高、节拍要求严格的生产环节,传统夹爪往往具有结构简单、成本较低和易于维护等优势。灵巧手的价值更多体现在需要多指协同、精细接触或较强操作灵活性的任务中,其实际优势仍需结合具体工艺进行评估。

从研发样机走向持续运行,灵巧手仍需解决可靠性、环境适应性和维护成本等问题。复杂的机械结构、多关节驱动及传感器集成增加了设计与维护难度,粉尘、接触磨损及长期运行也可能影响产品表现。对于实际应用而言,单次成功完成动作并不足够,用户更关心机器人能否在真实环境中持续、稳定地完成任务,以及由此带来的效率提升能否覆盖设备、维护和集成成本。

灵巧手商业化的关键关键不只是能否完成特定动作,更在于能否在真实场景中稳定运行并持续完成任务。

灵巧手未来三年将从“路线探索”进入“工程化竞争”

IDC认为,未来三年灵巧手市场的竞争将围绕以下几个方向展开。

市场需求将从研发与数据采集向具体任务应用拓展。 短期内,科研教育、人形机器人配套及具身智能数据采集仍是值得关注的需求方向。随着机器人应用探索深入,工业制造、物流、服务等场景则需要进一步验证其实际应用价值。灵巧手能否在复杂抓取、精细操作和多品种作业中体现出相较传统夹爪的优势,将影响其应用拓展速度。

技术竞争从硬件参数转向结构设计与综合操作能力。 腱绳驱动、直驱、连杆驱动及混合驱动各有适用条件,短期内不同技术路线仍将并存。产品竞争不仅取决于自由度和抓握力,还涉及电机、电控、减速器、丝杠等核心部件的设计与优化,以及结构紧凑性、驱动性能和可靠性之间的平衡。在此基础上,视触觉感知、精细控制及与机器人本体和具身智能模型的协同能力,也将影响灵巧手的实际操作表现。单纯增加自由度,并不必然带来更好的操作效果。

竞争从硬件本体向模型、数据与技能协同延伸。除灵巧手本体外,操作模型、数据资源、技能库及开发工具也逐渐成为厂商布局的组成部分。这些能力有望帮助用户开展模型训练、任务开发与技能复用,减少应用开发工作。未来,厂商之间的差异不仅体现在硬件性能上,也将体现在能否将硬件、模型、数据和技能有效结合,以及能否将这些能力转化为稳定的任务执行效果。

可靠性、成本和交付能力将影响市场竞争格局。 随着用户从研发测试走向实际应用,灵巧手厂商需要解决长期运行、产品一致性、维护和成本控制等问题。专业灵巧手厂商、本体厂商自研团队及传统末端执行器厂商将继续参与市场竞争,但不同类型厂商的优势和商业化路径可能有所差异。

总体来看,未来三年灵巧手市场仍将处于多种技术路线并存、应用持续验证的阶段。行业竞争的关键不在于某一种驱动路线率先胜出,而在于厂商能否围绕具体任务,将结构设计、核心部件、感知控制、模型和数据有效结合,并在操作性能、可靠性与综合成本之间取得平衡。 灵巧手能否从研发与测试走向更广泛的商业应用,最终仍需由真实场景中的任务表现来检验。

IDC相关研究

灵巧手正处于从“技术路线探索”向“工程化竞争”过渡的关键拐点。在这条拥挤的赛道上,谁能率先跨越软硬件协同与商业化落地的鸿沟,谁就能掌握下一阶段的主动权。

作为全球领先的IT市场研究与咨询机构,IDC在机器人、具身智能及核心零部件领域拥有深厚的研究积累。我们不仅关注底层技术路线的演进,更致力于帮助客户洞察商业化落地路径、市场规模预测及竞争格局。

针对灵巧手市场,IDC可为您提供:

  • 市场全景洞察:全球及中国灵巧手出货量预测与需求结构分析。
  • 技术路线评估:腱绳/直驱/连杆等不同驱动路线的优劣势比对与适配场景研究。
  • 竞争格局研判:头部厂商及跨界玩家(本体厂商、传统夹爪厂商)的战略布局与优劣势分析。
  • 定制化咨询:面向投资机构、本体厂商及终端客户的定制化市场进入策略与尽调支持。

进一步沟通

IDC将持续关注灵巧手市场的需求变化、技术路线、厂商布局与应用进展,并通过后续研究进一步分析其市场规模、竞争格局及商业化趋势。如需了解更多IDC机器人研究内容或定制化市场分析,欢迎与IDC中国分析师团队联系。请点击此处与我们联系。

Lily Li

Lily Li - Research Manager

Lily is the Research Manager for China Robotics and Embodied Intelligence, specializing in market research on embodied intelligent robots. She has long focused on the development trends of China’s embodied intelligence robotics industry, systematically studying the evolution of robot hardware,…

五家代表厂商入选,行业整体仍处发展早期,可靠性与工程闭环能力成核心竞争标尺

工业AI正在进入 “ 价值兑现” 的深水区,工控编程作为工业自动化领域门槛最高、价值最厚重的场景之一,正成为工业智能体落地的核心攻坚方向。随着生成式 AI 与智能体技术向运营技术(OT)领域渗透,工控智能体正从早期的代码补全、问答助手,逐步演进为可调用专业工程软件、交付可验证工程资产的工程协作者。

国际数据公司(IDC)于近日发布首份《中国工业控制智能体技术评估,2026》(Doc#CHC54370326,2026 年 10 月)报告。报告首次对中国市场工控编程智能体产品开展系统性技术评估,从工程能力、产品能力、业务价值、交付保障四大层面共十一项核心维度切入,对倍福、华龙讯达、万昇智能、西门子、远舢智能(按照拼音首字母顺序排列)五家代表厂商的产品进行深度评估,并给出行业平均能力基准,为制造企业选型与厂商产品迭代提供参考依据。

一、工控智能体重新定义工程交付范式

IDC 将工控智能体定义为:面向可编程逻辑控制器(PLC)、分布式控制系统(DCS)、监督控制和数据采集(SCADA)等相关工程控制软件,能够理解工艺需求、点位表、图纸和既有工程上下文,调用工程工具完成控制代码、硬件配置、人机界面(HMI)/SCADA 资产、验证和交付任务,并在人类工程师监督下形成可审查闭环的工业智能体。

其核心价值不只是生成一段结构化文本代码,而是系统性减少工程师在需求整理、对象创建、批量变更、编译修复、测试和文档交接中的重复劳动,重塑工程交付的效率边界。

当前中国工控智能体市场仍处于早期发展阶段。市场上产品名称虽普遍使用 Copilot、CoAgent 或 Agent,但实际能力边界差异显著:部分产品已形成正式商业版本并实现全球销售,部分处于客户试用阶段,还有部分方案仍以内部测试、定制项目形式验证能力。本次评估划定的核心市场边界为:产品是否能够生成可导入、可编译、可验证和可维护的控制工程。

二、十一项维度立体评估,五家厂商代表四条技术路径

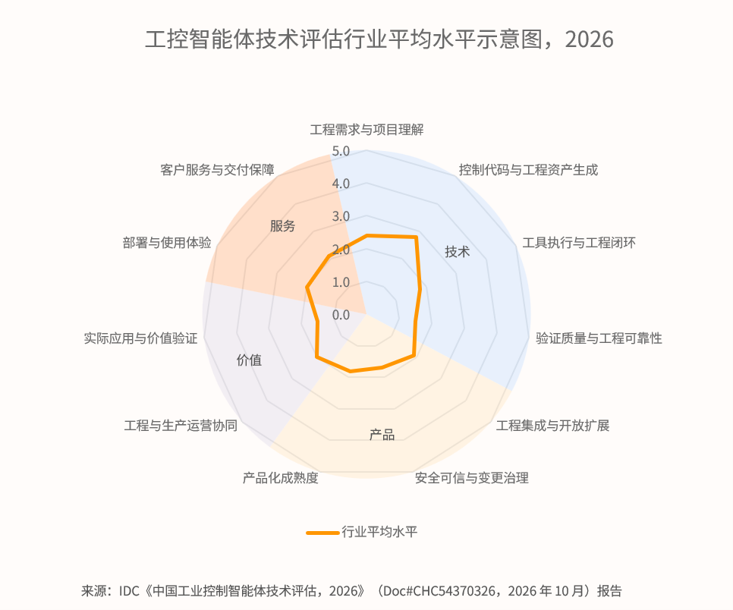
本次评估围绕 “能否把工控编程能力、工程化能力和实际价值连接为可交付的工程闭环” 这一核心命题,设置十一项独立评分维度,覆盖工程需求与项目理解、控制代码与工程资产生成、工具执行与工程闭环、验证质量与工程可靠性、工程集成与开放扩展、安全可信与变更治理、产品化成熟度、工程与生产运营协同、实际应用与价值验证、部署与使用体验、客户服务与交付保障。所有维度采用 1-5 分独立评价,不设置权重、不计算综合分,聚焦产品当前可交付、可验证的真实能力。

本次研究从工控、工业软件与智能体供应商中筛选出五家具备中国市场产品与项目基础的代表厂商,对应行业四条主流产品演进路径:

  • 原厂 IDE 深度集成路径:西门子 Eigen Engineering Agent、倍福 TwinCAT 3 CoAgent for Engineering,依托原生工程软件生态实现深度工程操作
  • 原生智能体驱动工程平台路径:万昇智能 WasomCodeX V2.0,以智能体为中心重构工业 IDE 与工程工作流
  • 跨品牌场景化方案路径:远舢智能 INOS Claw 智立方,面向异构存量工厂提供跨系统、跨行业的场景化智能体方案
  • 自主控制器 + 原生工程环境路径:华龙讯达 JIC IAP 内置 AI 智能编程助手,基于自有控制器与开发环境形成全栈协同

整体来看,领先产品已经能够在明确的平台与任务边界内显著提升工程效率,并开始从 “回答代码怎么写” 走向 “在工程环境中完成完整任务”。

三、行业平均基准:基础能力初具,工程闭环仍是核心短板

基于全市场广泛调研形成的行业平均能力基准显示,当前中国工控智能体整体仍处于发展早期:需求理解、基础代码生成和传统服务支持已形成初步能力,但多数产品仍停留在建议输出、片段生成或有限工具调用阶段。工程执行闭环、独立行为验证、异常与回归测试、标准化商业产品形态以及可量化的投资回报,是当前行业最突出的能力短板。

IDC 2026 年离散制造业智能体功能调研数据显示,制造企业评价智能体时,82% 的受访者优先关注可靠性,70% 关注任务准确率,均显著高于对生成速度的关注。在工控场景中,控制程序直接关联设备运行、生产节拍与人员安全,“可靠、可审查、可回滚” 是产品从演示 Demo 走向生产级应用的核心前提。

四、五大趋势定义工控智能体下一阶段演进

IDC 判断,未来 2-3 年工控智能体将从以代码建议为主的辅助工具,逐步演进为能够理解工程目标、调用多类工具并交付可验证结果的工程协作者,市场将呈现五大核心趋势:

1. 工程 IDE 向 “智能体友好型” 演进,开放生态成关键变量

原厂编程 IDE 将从面向工程师图形化操作,同步升级为支持智能体可靠调用的开放平台。命令行接口(CLI)、应用程序接口(API)、软件开发工具包(SDK)、模型上下文协议(MCP)及稳定对象模型,将全面覆盖项目读取、对象创建、差异比对、编译测试、版本管理与失败恢复,并配套细粒度权限与审计能力。开放程度将直接决定产品能否融入企业已有的 AI 工具链。

2. 工程知识资产化,多模态工程闭环释放长期价值

企业积累的标准功能块、设备模板、命名规范、画面库、工艺包与历史缺陷库,是工控智能体最核心的差异化资产。产品竞争将从 “生成代码的能力” 转向 “理解与复用客户工程资产的能力”;读取图纸、文档只是起点,更高价值在于将多模态工程资料转化为可追溯的 PLC 变量、I/O 配置与 HMI 对象,实现增量更新的完整工程闭环。

3. 历史项目复用与跨平台迁移,成规模化落地核心攻坚点

智能体的规模化应用,核心在于能否从历史项目中识别可复用的控制结构、设备模板与测试用例,并在新项目中完成参数化改造。面向多品牌共存的存量工厂,跨平台迁移能力将成为重要差异化指标 —— 其核心不是简单语法转换,而是完整保留控制意图、库语义、通信约束、安全互锁与工程维护习惯。

4. 可审查执行与独立验证,成为生产级应用准入标准

领先产品将把任务规划、工具调用、工程差异、编译结果与测试记录全链路串联,默认预览、显式应用、权限分级、失败停止将成为生产部署的标配。行业将逐步建立独立于代码生成器的行为评测体系,覆盖正常顺控、边界条件、断连重启、传感器异常与互锁冲突等场景 —— 编译通过不等于逻辑可靠,独立行为验证将成为硬性准入要求。

5. 工程与运维逐步衔接,拓展智能体价值边界

工程智能体未来将打通运行数据,辅助故障定位、变更影响分析与维护交接,实现从 “工程交付工具” 向 “全生命周期工程协作者” 的延伸。工程侧的对象语义与运行侧的实时数据打通后,将为跨岗位协同、持续工艺优化提供新的支撑。

分析师观点

IDC 中国制造行业高级研究经理杜雁泽表示:“工控智能体的价值,不在于生成多少代码,而在于能否把工业知识、历史工程资产、专业工具和验证机制连接成可审查、可恢复、可交付的工作闭环。下一阶段,原厂 IDE 能否向智能体开放稳定接口,客户工程库能否被安全理解和复用,以及跨平台迁移和 IEC 工程规范能否进一步统一,将决定产品能否从工程师试用走向规模应用。”

更多相关研究

  • IDC MarketScape: 中国工业 AI 及智能体平台 2026 年厂商评估(IDC #CHC54110326,2026 年 9 月)
  • IDC Market Glance: 中国工业 AI 及智能体,2Q26(IDC #CHC54370226,2026 年 8 月)
  • 中国核心工业软件及工业 AI 市场预测,2026-2030(IDC #CHC53716026,2026 年 4 月)
  • IDC MarketScape: 中国工业大模型及智能体解决方案 2025 年厂商评估(IDC #CHC53013925,2025 年 9 月)
  • 中国工业智能体 (AI Agent) 市场分析及供应商推荐(IDC #CHC52296125,2025 年 6 月)
  • 中国工业大模型应用进展与展望,2025(IDC #CHC52296025,2025 年 6 月)

进一步交流

如需获取完整报告,或就工控智能体技术趋势、技术选型、落地路径展开深入沟通,欢迎联系 IDC 中国制造业研究团队。请点击此处与我们联系。

Yanze Du

Yanze Du - Senior Research Manager

Yanze Du is a senior research manager for the Manufacturing Insights group in IDC China, and he is responsible for conducting research on and analysis of the China manufacturing industry and supply chain. He is also involved in regional and…

随着模型能力持续提升、智能体框架与工具链日趋成熟,越来越多企业开始将智能体用于实际业务。IDC调研显示,已有智能体投入生产的受访企业比例,从2025年9月的42.4%升至2026年3月的76.8%,其中亚太地区由30.8%升至75.9%,增幅居各地区之首(来源:IDC Future Enterprise Resiliency and Spending Survey Wave 2,2026年3月)。

企业部署的智能体越来越多,如何保障智能体的运行质量、安全可控并管理持续的成本支出,也正成为企业急需解决的难题。能够统一运行和治理各类智能体的智能体平台因而受到更多企业关注,带来了市场需求持续增长。IDC预测,全球智能体平台市场规模将由2025年的26亿美元增至2030年的415亿美元,2025—2030年复合增长率约为74%,其中亚太及日本地区(APJ)增速最快,复合增长率预计达到82%。(来源:Market Forecast: Worldwide Agentic AI Platforms Forecast, 2026–2030,2026年9月)。

智能体应用给企业带来了新的难题

围绕传统软件,企业大多已经建立起较为成熟的DevOps体系,覆盖开发、测试、发布和运维等环节。智能体应用在业务角色、运行方式和建设规模上与传统应用差异明显,难以直接沿用这套体系。

在业务角色上,传统软件应用通常围绕特定业务功能和流程提供服务,由员工组织和协调跨应用任务。而智能体应用具备任务理解、思考规划并调用不同系统的工具自主执行任务的能力,这些能力也带来了企业其对运行可靠性、权限控制和可观测可追溯能力的要求。

在运行方式上,传统软件按照预先设定的规则和逻辑开发,测试与验收的范围也比较明确。智能体的执行结果则取决于模型输出、所调用的数据和知识、智能体的循环执行策略以及工具返回的结果,同一项任务每次执行的路径和结果都可能不同。这些带来对智能体开发构建和持续运维管理的需求,智能体不仅要在开发阶段需要反复调试和验证,上线后也要根据实际使用情况不断调优,同时还需要持续对其模型Token消耗进行治理。

在建设规模上,企业部署的智能体数量通常远多于传统应用,并分散在不同部门、业务系统和技术环境中。如果仍由各团队分别开发、部署和维护,容易出现重复建设、权限不清、成本失控和协作困难等问题,各团队积累的知识、Skill和实践经验也难以沉淀为企业资产,这些问题带来了企业对智能体统一运维统一治理的需求。

智能体全生命周期管理能力是平台的核心

IDC所称的智能体平台,是指面向企业客户提供智能体构建、部署、运行、治理和编排能力的软件平台。平台支撑智能体在受控的权限、数据、系统和流程范围内完成业务任务,并帮助企业统一管理智能体资产、任务过程、风险、成本和运营效果。

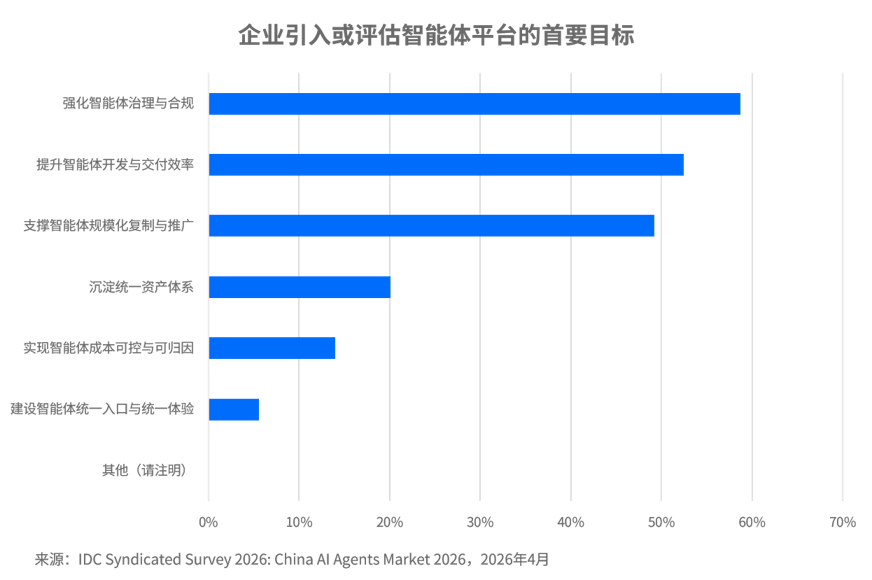
IDC调研显示,58.7%的受访企业将强化智能体治理与合规列为引入或评估平台的首要目标,提升开发与交付效率(52.5%)和支撑跨场景规模化复制与推广(49.2%)紧随其后,选择沉淀统一资产体系、实现成本可控与可归因、建设统一入口与体验的企业分别占20.1%、14.0%和5.6%(来源:IDC Syndicated Survey 2026: China AI Agents Market 2026,2026年4月,Q16,N=179)。

企业的这些目标分布在治理合规、开发交付和规模化复用等不同环节,要求平台既能覆盖智能体从设计到下线的全生命周期管理,也能在运行中保障任务质量、安全合规和成本可控。

智能体全生命周期管理,应覆盖从需求定义与设计、开发构建、测试评估、部署发布、运行维护,到持续优化和停用下线的全过程。管理对象除了智能体本身,还包括其依赖的模型、提示词、工作流、工具、知识、记忆和Skill,以及相关的运行环境。

智能体要在真实业务中稳定完成任务并带来可验证的ROI,平台还需要具备相应的运行管理和成本治理能力。IDC全球调研显示,过去12个月中,67%的企业智能体支出超出预算,其中24%超支25%以上,能够按工作流实时追踪Token消耗和成本的企业只有45.4%(来源:IAddressing the Agent Economy’s Cost Governance Gap: A Mandate for IT Providers,2026年9月)。平台需要按部门、场景、智能体和任务归集消耗,提供预算预警和执行限制,同时统计任务成功率、人工介入率和单位成功任务成本,帮助企业核算智能体的投入与产出。

企业选型需要结合自身条件

国际数据公司(IDC)于近日发布了《IDC MarketScape: 中国智能体平台2026年厂商评估》(Doc# CHC54110526,2026年10月)报告,从能力和战略两个维度评估中国智能体平台市场的28家厂商,企业选择智能体平台时,需要先结合自身的数字化基础、组织结构和业务特点确定智能体建设路径,不同路径对平台和厂商能力的要求也不相同:

  • 数字化、信息化基础较为薄弱的企业,往往需要一边补齐业务系统建设,一边推进智能体应用,可以优先考虑能够提供综合解决方案的厂商。这类企业选择的平台需要能够与相关业务系统联合交付,并支持智能体的快速构建。
  • 多个部门同时建设智能体、业务系统来自不同厂商的大中型企业和集团,更需要一个能统一管理各类智能体的平台,重点考察多模型和多系统接入、智能体全生命周期管理以及安全与权限控制能力。金融、政务等对数据安全和信创要求较高的行业,还需要将私有化部署和本地服务能力作为前提条件。
  • 数据结构复杂或专业知识要求较高的企业,则需要关注平台或服务团队能否提供数据治理和业务语义建模能力,把企业数据、知识和业务规则整理成智能体能够理解和调用的形式,使智能体准确识别业务对象、采用一致的指标口径,并依据业务规则完成判断和操作。

分析师观点

IDC中国研究经理孙振亚表示:“企业智能体应用的规模越大,越需要平台把分散在不同部门和业务系统中的智能体统一管理起来,智能体平台正在成为承担这一角色的关键系统。平台不仅要支持开发和部署,还要保障业务执行、管控权限与成本,并支持依据评测和运行反馈持续优化,同时企业选型时也应基于企业实际情况选择合适的平台产品。”

IDC MarketScape从能力和战略两个维度评估中国智能体平台市场的28家厂商,分析其平台能力与发展路径,为企业选型提供参考。企业选型不仅要看智能体能否快速搭建,还要检验其能否在真实业务中可靠执行任务、控制风险与成本,并通过持续优化改善业务成效;基于Harness的自主规划智能体与确定性工作流如何协同、自进化过程能否验证和管控,也是评价平台能力的重要内容。随着智能体深入企业业务,平台还需承担统一运行与治理、连接已有系统、积累和复用业务能力的职责。智能体平台正成为企业AI应用中台的重要形态,与模型即服务(MaaS)、数据与知识平台共同构成AI时代企业IT系统的关键基础设施。

进一步交流

每家企业的智能体建设路径不同,评估维度落到具体场景时的权重也不同。如果您正在做智能体平台选型,或希望了解《IDC MarketScape:中国智能体平台2026年厂商评估》的详细评估维度、厂商画像与选型建议,欢迎联系IDC中国团队进一步交流。请点击此处与我们联系。

Zhenya Sun

Zhenya Sun - Research Manager

Zhenya Sun is a research manager for the IDC team focused on exploring the application of technology and industrial development of AI and AI agents. He is also responsible for providing clients with consulting services on technologies, products, and markets…

企业级Token混合成本一年内从18.40美元/百万Token降至6.07美元,下降67%。与此同时,中国日均Token调用量从2024年初的1,000亿攀升至2026年3月的超140万亿,两年增长超1,000倍。

这就是AI时代的杰文斯悖论——效率越高,应用越广,总消耗越大。Token单价的持续下降,并没有让总支出收缩,反而打开了指数级的应用空间。IDC预测,全球活跃AI智能体将从2025年的约2,860万个增至2030年的22.16亿个。当智能可以规模化生产,核心问题已经变成:怎样用最低成本、最大效率持续产出Token?

但比GPU代际迭代更值得关注的,是另一个结构性事实:同样一批GPU,在不同网络和存储架构上,Token产出成本可以相差数倍。

水面之下:真正决定Token产出的隐性变量

行业习惯用FLOPS衡量AI基础设施。但以DeepSeek-R1推理为基准,新一代GPU平台相较上一代:每美元FLOPS提升约2倍,每GPU的Token/秒却从约90提升至约6,000(提升约65倍),每百万Token成本从约4.20美元降至约0.12美元(降低约35倍)。算力指标增长2倍,业务产出却增长数十倍?

差距从何而来?低精度计算(FP8/FP4)、RDMA/GPUDirect RDMA、投机解码、KV Cache卸载与复用、Prefill/Decode分离调度——每一项都不只是芯片层面的进步,而是基础设施层面网络与存储的系统性协同设计。

“推理冰山”的比喻恰如其分:水面之上是GPU数量和FLOPS,水面之下才是决定实际产出的变量。网络和存储,正是水面之下两个最大的杠杆。

IDC数据显示,2026年AI推理成本在企业AI预算中已超80%。一座GW级AI数据中心的四年TCO约550亿美元,其中网络和存储合计占基础设施TCO的16%-18%——不到五分之一的投资,决定了五分之四以上资产的运行效率。也就是说,网络与存储的规划失误,会被直接放大进那80%以上的推理预算里——这是最容易被忽略的一笔账。

网络:从“连接管道”到“神经系统”

传统数据中心中,网络是“管道”——把数据从A搬到B。但在Token工厂中,网络的角色已经发生质变。

MoE架构的All-to-All通信把GPU间通信从“突发”变成了“持续”;PD分离后KV Cache跨节点读写成为常态;上万推理并发下,每一次响应都要经过上百次GPU间往返。网络延迟每增加1微秒,都会在上百次通信中被放大为Token产出的直接损失。

行业实际部署数据表明:在万卡集群中,采用动态路由(AR)优化的网络带宽利用率可达约95%,传统以太网仅约60%。35个百分点的差距,等效于数千万美元的GPU投资被闲置。您的集群现在落在哪个区间?如果长期停在60%一侧,那剩下对应的闲置算力,就是最容易被忽略的成本——而它往往不是GPU买少了,是网络没跟上。

网络效率的兑现需要四个维度逐级递进:速度(微秒级延迟+800G→1.6T带宽+RDMA三步直达)、效率(动态路由+拥塞控制将利用率从60%拉升至95%)、架构(Scale-Up/Out协同+网络计算,万卡集群维持百卡水平)、能效(在约40万GPU集群中,CPO光电封装将网络功耗从72MW降至21MW,节省约70%)。

四层不是并列关系,是逐层收敛——速度决定响应体验,效率决定单次服务成本,架构决定用户规模上限,能效决定普惠服务的空间。对最终用户而言,网络性能并不是抽象的带宽和延迟指标,而是 AI 助手能否快速响应、复杂任务能否流畅完成,以及高峰期服务是否依然稳定。网络延迟降低,用户等待的时间就可能缩短;通信效率提升,意味着同样的 GPU 资源能够支撑更多请求,企业也有机会以更低的成本提供 AI 服务;架构具备良好的扩展能力,才能在用户量和任务复杂度持续增长时,避免服务质量随规模扩张而下降;而能效的改善,则有助于控制 AI 服务长期运行的成本,为更广泛的应用和更普惠的定价创造空间。

网络已从“连接配件”升级为决定Token产出速度的“神经系统”。神经系统的速度不是由最快的那段决定,而是由最慢的那段决定。

存储:从“数据仓库”到“工作台”

另一条同样重要的线索在存储侧。

KV Cache代表了一类面向推理过程的AI原生数据形态:它是派生的(由Prefill计算产生)、瞬态的(生命周期跟随一次会话或一个智能体任务)、可重算的(丢失后可通过GPU重新计算)。这三个属性意味着,传统存储为“永久保存、绝不丢失”而设计的RAID、多副本、异地灾备等机制,对KV Cache而言是额外开销。

这一认知转变是新存储范式逻辑的起点。当上下文长度达到百万级,每次推理从头计算的成本远超缓存读取——用廉价的NVMe SSD存储替代昂贵的GPU重复计算,这是“以存代算”的核心经济逻辑。

新一代AI原生存储为此做了全栈重构:KV原生接口替代传统文件/块/对象接口,I/O路径极致精简,读写延迟降至接近NVMe硬件极限;分级保护策略取代一刀切的持久化体系,优先保障吞吐与时延;智能介质选择依据数据热度在内存、SSD与通用存储间动态调度;DPU硬件卸载实现CPU与GPU的零I/O开销。如果您的存储团队仍在按“绝不丢失“的口径设计KV Cache,这部分开销就是浪费——不是存储买贵了,是设计范式用错了对象。

MLPerf基准测试显示,新一代AI原生存储推理吞吐量和能效较传统方案提升约5倍;在多厂商联合测试和VAST 测试中,首个Token生成响应时间(TTFT)分别改善约9倍和约20倍。存储不再只是模型层的附属仓库,它是与计算和网络并列的基础设施独立支柱。

一个判断:系统级协同优于单点突破

三个结构性转向正在同时发生:用“每Token成本”替代“每美元FLOPS”作为核心评估指标;网络投资应与GPU同节奏规划,而非事后补网;KV Cache应被视为独立数据类别,而非传统存储上的“特殊文件”。

三个转向叠加,是Token成本结构性坍缩的基础设施前提。

在AI从“烧钱”走向“赚钱”、从“特权”走向“普惠”的过程中,网络和存储不一定是投资额最大的两个部分,但它们是决定整个Token工厂效率上限的两个核心变量。改变任何单一层面的效率,不如打通层与层之间的协同瓶颈——这才是Token工厂隐形的天花板。

行动建议

  • 用“每Token成本”替代“每美元每秒浮点运算次数(FLOPS)”作为评估与资源配置的核心指标。
  • 网络投资与GPU同节奏规划,而非事后补网——网络占TCO不到10%,却决定45%的GPU资产效率。
  • 将KV Cache视为独立数据类别,采用KV原生接口与分层存储,实现“以存代算”。

IDC相关研究

《AI Token工厂的网络与存储加速》,Doc# CHC54979226,2026年10月

进一步交流

网络与存储如何影响Token产出成本,不同集群规模、不同推理负载下的瓶颈位置并不相同。如果您正在规划或优化AI基础设施,希望结合自身情况做一次针对性讨论,欢迎联系IDC分析师团队。我们可基于实际部署数据与TCO模型,帮您判断瓶颈落在网络四层中的哪一层、KV Cache是否该切换范式。期待与您交流。请点击此处与我们联系。

Xiangdong Hu

Xiangdong Hu - Research Director, Enterprise Research

As research director of IDC China's Enterprise Research, Steven Hu leads the China networking team in doing market research and project consulting. His team research projects include network equipment such as switches, routers, wireless, and emerging technologies including software-defined network…