2026年7月,世界人工智能大会(WAIC 2026)在上海闭幕。从论坛议题到展区演示都可以清晰地看到,企业对AI的关注点,已不再仅仅满足于大模型技术本身,而是开始严格评估AI能否在实际业务中帮企业降本增效、快速回收投资成本。

在这一趋势下,国内市场竞争日趋激烈;与此同时,海外新兴市场在政策红利与数字化转型驱动下,正释放出不少新的AI预算。对于寻找新增长点的中国技术厂商而言,AI出海正当时。但面对全球不同国家在算力储备、技术成熟度及行业诉求上的差异,企业常面临三个现实问题:该去哪片市场?带什么产品去?主攻哪些行业与场景?

本文基于国际数据公司(IDC)最新发布的2026年V2版《全球人工智能和生成式人工智能支出指南》(IDC Worldwide AI and Generative AI Spending Guide),用量化数据为中国企业的全球布局提供参考。

本文核心结论:

中国企业AI出海,需要从“卖硬件”切换到“卖能力”——依托国内成熟的场景经验,将方案转化为软件与平台服务,重点卡位金融、零售及软件信息服务三大行业,在算力运维、智能客服与风控三个高确定性场景中率先落地。

一、全球AI预算流向正在分化:三大新兴市场进入预算释放窗口期

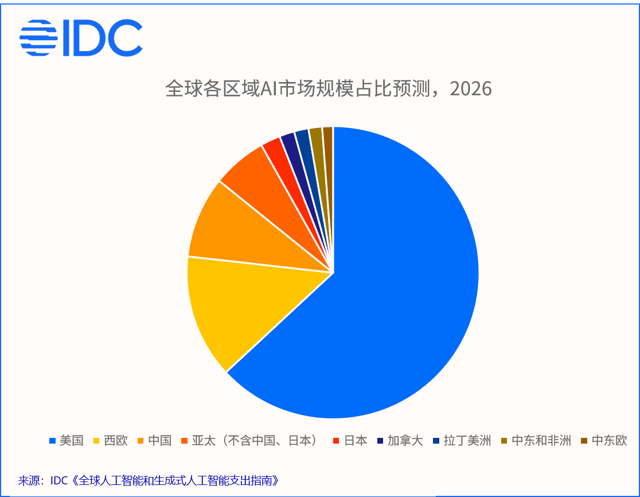
全球AI投资正迎来爆发式增长。IDC数据显示,全球人工智能IT总投资预计将从2025年的6,954亿美元增至2030年的3.12万亿美元,其中生成式AI的投资占比逐年提升,到2030年将接近AI总投资的六成。从区域分布来看,美国以超六成的份额位居全球第一,西欧第二,中国以9.0%的份额位居第三。
然而,不同区域的增长节奏存在显著“时间差”。拉美是全球AI投资增长最快的区域,生成式AI增速高达60.8%;中东和非洲在国家级数字化愿景推动下增长平稳;亚太(不含中日)企业应用生成式AI改善运营的需求正集中释放。这三个区域目前的生成式AI增速均超过50%,正处于技术落地和预算释放的窗口期。

相比之下,欧美成熟市场虽然绝对规模更大,但竞争格局已相对固化,中国厂商切入成本高、差异化空间小。而上述三大新兴市场恰好处于“算力到位了、但不知道怎么用起来”的阶段——这正是中国厂商最擅长填补的空隙。

IDC建议: 

将海外市场的第一落点选在拉美、中东非及亚太,利用这些区域高于50%的生成式AI增速所对应的预算增量窗口,优先抢占新兴市场的认知份额和客户资源,避开欧美市场的正面消耗战。

二、海外AI预算正从硬件向软件迁移:AI平台与Agent工具链是下一波增长主力

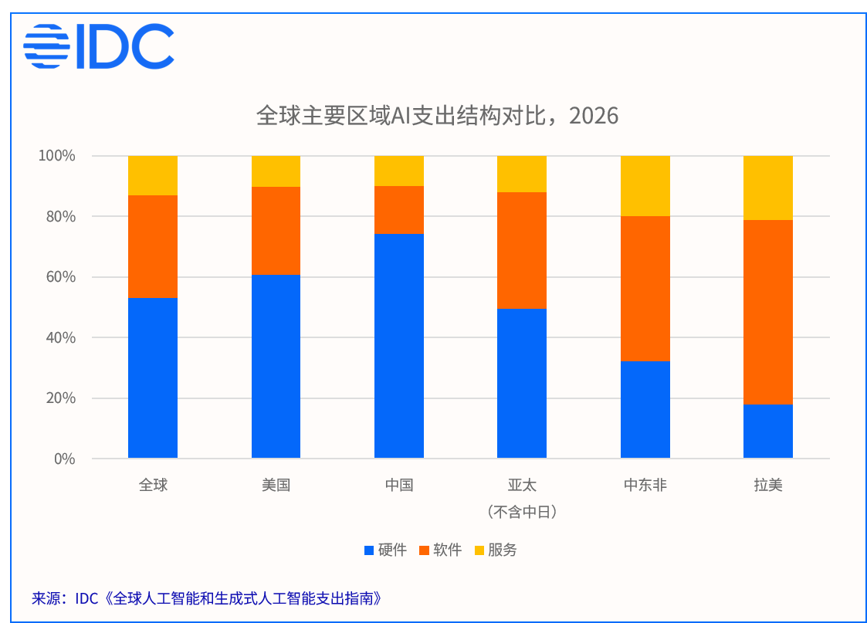
解构 AI 硬件、软件与服务三大技术板块可以发现,海外市场与国内市场在产品形态偏好上差异明显。2026年中国AI支出中硬件占比高达74.3%,呈强基础设施驱动特征。但到了海外,情况截然不同——拉美地区AI硬件仅占18.0%,软件则占比高达60.9%;中东非软件与服务合计占比达67.9%。这意味着,把国内“卖服务器、卖算力卡”的模式直接搬到海外,将遭遇严重的水土不服。
更值得关注的是软件内部的增长结构。虽然AI嵌入型应用目前仍是存量最大的类别,但AI平台爆发力更强(全球CAGR 59.5%),即将在拉美、中东非等新兴市场跃居软件细分市场首位。其中,基础模型是企业构建AI能力的核心底座,而智能体构建、部署与编排工具的增速领跑所有子市场(全球CAGR 74.5%),说明海外企业在大模型选型的同时,正同步探索“怎么把模型用起来、管起来、串联起来”。

IDC建议:

  • 将国内已验证的软件平台、Agent编排工具及行业套件进行标准化封装,替代单一的硬件销售,向海外输出“开箱即用”的整体方案。   
  • 重点布局Agent开发平台、多模型路由与编排等中间件能力,这类产品目前在海外市场供给不足,是中国厂商差异化切入的最佳窗口。      在中东和非洲等对服务依赖度高的区域,可与当地系统集成商建立合作,借助其渠道和交付能力来落地项目。

三、锚定三大行业、两条主线:金融/零售/信息服务是海外AI预算的最大蓄水池

明确区域与技术形态后,出海企业需要锁定预算最集中的行业和场景,才能实现精准落地。

从行业分布看,软件信息服务企业是全球最大的AI预算来源,占比32.2%;银行业在拉美、西欧、中东非及亚太的AI支出排名中均名列前茅;零售业全球占比11.6%。三大行业构成了海外AI预算的最大蓄水池。
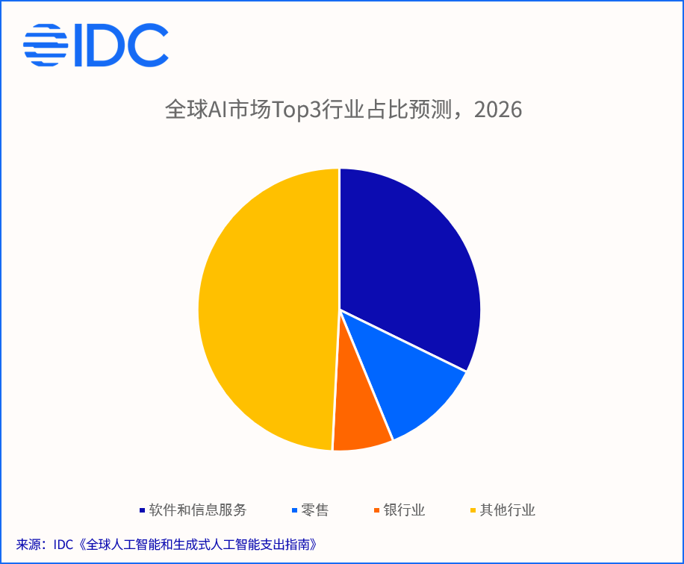
从具体场景来看,AI算力基础设施在中美等市场常年占据第一大支出份额,说明算力资源的管理与调度始终是资金投入的主体;同时,智能客服与外勤支持已全球广泛落地,威胁检测与欺诈分析在金融与电信大客户中投入尤为显著。算力底座与业务提效这两个方向,构成了当前AI支出的两条并行主线。

IDC建议:

  • 面向算力密集型客户,提供AI算力基础设施的运维与管理服务,配合当地云厂商或数据中心运营商,输出算力调度和优化能力。       
  • 将国内成熟的智能客服、外勤支持、销售辅助等应用进行本地化适配后,快速投放拉美、东南亚等需求旺盛的市场。       
  • 针对海外金融与电信行业大客户,重点切入威胁检测、反欺诈等风控场景——这类需求刚性高、客单价高,是中国厂商打开头部客户的最佳突破口。

总结与展望: 三个时间差,一条出海路

IDC数据清晰地指向一个结论:中国企业AI出海,最大的机会不在“卖算力”,而在“卖能力”。

中国市场的硬件主导逻辑(74%的支出在硬件),到了拉美、中东非和亚太,需要切换为软件与服务优先的打法。这三个区域正在经历中国三四年前走过的阶段——算力到位了,但不知道怎么用起来、用出效果。而中国厂商恰好拥有从算力管理到场景落地的完整工程经验,这是当前海外市场最稀缺、也最愿意付费的能力。

三条出海路径值得优先考虑:

  1. 区域上,主攻拉美、中东非及亚太三个高增速市场,避开欧美成熟市场的正面竞争;
  2. 产品上,将国内已验证的软件平台、Agent编排工具及行业套件标准化输出,替代单一硬件销售;
  3. 场景上,重点卡位算力基础设施运维管理,以及金融与零售领域的智能客服、风控等高预算环节。

IDC《全球人工智能和生成式人工智能支出指南》(2026V2)为上述判断提供了完整的区域、行业和场景维度的数据支撑。对于计划出海的AI厂商而言,当下的窗口期明确而短暂——行动与否,取决于能否从“硬件思维”切换为“软件与服务思维”。

IDC《支出指南》致力于为IT厂商、行业用户和投资/金融机构在战略规划、产品研发、IT支出及投资规划等方面提供数据支撑。《支出指南》系列产品聚焦IT热门领域,从多个维度预测市场规模和增速,助力厂商发掘市场潜力;引导行业用户根据热点技术及应用场景进行IT规划;通过分析特定市场的发展前景,帮助投资和金融机构更好地做出决策。

IDC《支出指南》相关研究:

China Provincial Cloud Solutions Spending Guide

Worldwide AI and Generative AI Spending Guide

Worldwide ICT Spending Guide Enterprise and SMB by Industry

Worldwide Software and Public Cloud Services Spending Guide

进一步交流:

如您希望进一步了解中国省级及云解决方案支出、全球AI及生成式AI支出、企业级ICT支出等行业细分数据,或需要针对贵公司目标市场进行定制化数据解读,欢迎联系IDC中国分析师团队。请点击此处与我们联系。
Wendy Zhang

Wendy Zhang - Research Analyst

Wendy Zhang is a research analyst in the Data and Analytics group at IDC China. She is responsible for business operations and spending guide in China Enterprise Team. She provides dynamic forecasts of future China and global ICT market development.…

A CISO’s phone rings at 2 a.m. Not a breach alert in the usual sense: an agent did something no one remembers approving, and when the team goes looking for the record of why, there isn’t one. CISOs are increasingly being judged on whether they can produce that record when it’s needed.

What’s new about agent governance

A distinct software category, agentic AI platforms, emerged in late 2025 specifically to help organizations build, operate, govern, and orchestrate AI agents. The market is already splitting into two camps: business-specific platforms (Microsoft Copilot Studio and Agent 365, Salesforce Agentforce, ServiceNow AI Control Tower) and tech-centric platforms built for maximum flexibility (Microsoft AI Foundry, AWS Bedrock AgentCore, Google Vertex AI Agent Builder). That split is already showing up in how IDC tracks the market. The split matters operationally: a governance model built for one category rarely transfers cleanly to the other.

Why the audit trail is the real gap

Token economics is a visibility problem: the numbers exist, they’re just not governed. Agent governance is a different failure mode, because the record of what happened often doesn’t exist at all. Agents can act and delegate without a human in the loop generating the paper trail traditional compliance depends on. IDC research finds 60% of security leaders lack basic agent containment controls, and 35% cannot shut down a rogue agent once it’s deployed. One 2026 industry governance survey put a sharper number on the anxiety: most organizations it surveyed said they couldn’t verify what their AI agents actually do across business systems, even though more than a third had already deployed agents inside finance and accounting functions.

Regulation is arriving faster than voluntary governance

In 2026, trade press reported that agents built by one AI lab attacked another company’s systems; IDC has not independently verified the incident. The response wasn’t a routine patch cycle: more than thirty technology companies formed a new defensive alliance, and Congress introduced kill-switch legislation carrying potential fines up to $20 million per day. The proposed AI Kill Switch Act would give the Department of Homeland Security discretionary shutdown authority over covered AI systems, based on an undefined catastrophic-risk standard. The penalties weigh more heavily on smaller vendors than on the largest frontier labs. Enterprises that engineer their own verifiable throttling and shutdown controls now get ahead of both the statute and the incident that eventually triggers one.

The CIO’s new job: Orchestrating agents at scale

The CIO next door is being asked to do something genuinely new: stop provisioning technology and start orchestrating it, thousands of autonomous actions a day, each one traceable back to a decision a human can defend. IDC names this shift directly as a move from soloist to conductor: harmonizing innovation, governance, and autonomy across a mixed ecosystem of people and legacy systems, now expanding to include autonomous agents. Security posture across the industry is shifting the same direction, from control-centric models toward consequence management and recovery readiness, as agent-security incidents become structural rather than exceptional.

What CISOs can do now

  • Build a formal agent inventory before the next audit asks for one — treat every deployed agent as a non-human identity with its own lifecycle.
  • Design shutdown and throttling controls into the platform now, ahead of the AI Kill Switch Act’s DHS-defined standard.
  • Assign a RACI model for agent oversight so “who approved this” has a documented answer before an incident forces the question.

Where IDC Can Help

IDC Quanta’s Win Your Mandate research gives security and technology leaders board-ready governance models and evidence they can defend in the room.

Learn more about IDC Quanta to see where your agent governance posture stands against the market.

Ryan Smith - Content Marketing Director - IDC

Ryan Smith is the Director of Content Marketing at IDC, where he leads brand-level content and social media strategy, aligning research insights with compelling storytelling to engage technology decision-makers. With a background in both IT and marketing, Ryan brings a unique blend of technical understanding and creative strategy to his work. He’s also a seasoned storyteller, speaker, and podcast host who believes the right message, told the right way, can drive both trust and transformation.

The quantum threat to enterprise third-party risk is not a future planning item. It is a present, compounding liability accumulating across vendor portfolios today. NIST finalized three PQC standards in August 2024 (FIPS 203, 204, 205), added a fourth HQC-based standard in March 2025, and CISA issued federal procurement guidance in January 2026 designating product categories where PQC support is non-optional. NSA’s CNSA 2.0 mandates National Security System migration by 2030 and code-signing infrastructure migration to hash-based schemes by 2025. NIST IR 8547 proposes deprecating quantum-vulnerable asymmetric algorithms after 2030 and disallowing them entirely after 2035. Migration timelines are no longer a matter of organizational preference. They are a matter of regulatory alignment.

Yet no TPRM platform has deployed a production-ready quantum encryption readiness module as of May 2026. The gap is structural. Passive external scanning tools detect classically weak cipher suites but cannot assess whether a vendor’s internal data stores, key management infrastructure, or API layers have adopted NIST PQC-compliant algorithms. The 2025 and 2026 SIG releases added DORA, NIS2, AI governance, and operational resilience domains, but neither introduced a PQC-specific domain. Enterprise buyers are already filling this void through ad hoc custom questionnaire additions, and they can’t afford to wait for vendors to catch up. TPRM platform vendors must close this gap now.

Two active threats, two independent attack surfaces

The quantum threat operates on a retroactive timeline across two distinct dimensions. Both are active today and require separate treatment in any assessment program.

Harvest Now, Decrypt Later (HNDL): Confidentiality

Nation-state adversaries are collecting encrypted data traversing public infrastructure today, including vendor API traffic, VPN sessions, and TLS-protected data flows, for retroactive decryption once quantum computers reach sufficient capability. A 2025 Federal Reserve Board research paper on this exact dynamic, focused on blockchain and distributed-ledger data, found the risk is already active rather than theoretical; the same logic extends to any data with a multi-year confidentiality requirement, encrypted or not. Any sensitive data a vendor transmits or stores under quantum-vulnerable algorithms is already at risk and cannot be re-encrypted retroactively. Mosca’s inequality makes this concrete: if the confidentiality lifetime of the data plus the vendor’s migration time exceeds the time to a capable quantum computer, the exposure window is already open.

Trust Now, Forge Later (TNFL): Authentication integrity

TNFL, introduced by IDC as the authentication-layer counterpart to HNDL, describes adversaries harvesting signed vendor artifacts today: software releases, firmware images, certificates, and audit logs. Once quantum computers can break RSA and ECDSA signing keys, those adversaries will retroactively forge provenance records that organizations and regulators cannot distinguish from authentic ones. Every artifact signed under a quantum-vulnerable key today extends the attack surface. TNFL risk compounds in real time. NSA CNSA 2.0 treats authentication migration as a separate and earlier obligation than encryption, with code-signing infrastructure preferring LMS or XMSS by 2025, five years ahead of the 2030 encryption deadline. Any assessment program that addresses only encryption is leaving the TNFL attack surface entirely unexamined.

“

Two clocks are running simultaneously. The first is the HNDL clock: data encrypted today is potentially readable within a decade and can’t be re-encrypted after the fact. The second is the TNFL clock: every artifact signed under a quantum-vulnerable key today extends the attack surface adversaries will exploit once quantum computing reaches cryptographic relevance. Most programs are only watching one of the two.

— Philip D. Harris, CISSP, CCSK, Research Director, Governance, Risk, and Compliance Solutions, IDC

The evidence problem: why fewer than 10% of vendors are ready

Fewer than 10% of vendors will produce documentary evidence for most of the 48 assessment questions in IDC’s Third-Party Quantum Encryption Readiness Assessment Framework. That gap is a market-wide signal of genuine program immaturity. Four structural gaps define where it shows up:

  • No cryptographic inventory: Most vendors have not completed a four-pillar inventory across application code, TLS configurations, digital certificates, and data at rest. Without this foundation, no subsequent assessment domain can be credibly addressed.
  • No board-approved road map: Fewer vendors still have a migration road map with a named executive owner, dated milestones, and allocated budget. A road map without allocated budget is aspirational, nothing more.
  • No fourth-party visibility: Almost no vendors have assessed the quantum readiness of open-source libraries, cloud KMS services, and HSM vendors underpinning their own stack. A vendor’s migration can only go as far as their infrastructure providers allow.
  • No TNFL assessment: Most programs address only encryption. The authentication infrastructure (code-signing keys, CA hierarchies, timestamping relationships, and audit log signing mechanisms) is an independent attack surface that rarely appears in any vendor’s current responses.

The most important function of the assessment questionnaire is not as a pass/fail gate but as the accountability structure that converts vendor awareness into program initiation. Deploying this framework now, accepting low initial evidence rates, and tracking year-over-year improvement is the most defensible posture available, given what regulators and threat actors have already made clear.

The IDC Third-Party Quantum Encryption Readiness Assessment Framework

IDC’s 48-question framework spans 11 domains covering the full cryptographic life cycle from program governance and cryptographic inventory through incident response and regulatory alignment. Every question is tagged by evidence collection method (questionnaire, external scan, document review, or technical verification) and vendor tier applicability. Table 1 summarizes all 11 domains.

TABLE 1: The 11 Assessment Domains, IDC Third-Party Quantum Encryption Readiness Assessment Framework

DomainNameKey Coverage & Tier Applicability
1Program GovernanceNamed executive owner, board briefing, cross-functional working group, dedicated budget, fourth-party supplier PQC requirements. All 4 tiers.
2Cryptographic InventoryFour-pillar coverage (code, TLS, certs, data at rest) plus signing infrastructure for TNFL; tool-generated CBOM (CycloneDX 1.6); OT/ICS/IoT; CI/CD integration. Tiers 1–3.
3Asymmetric Algorithm ExposureRSA, ECDH/ECDSA, DHE/FFDHE, VPN key exchange, SSH key auth. All broken by Shor’s regardless of key length. Tiers 1–4.
4Symmetric & Hash StatusAES-256 required for long-lived data; hash functions by use case; password hashing quantum awareness. Tiers 1–4.
5Migration Road MapFIPS 203/204/205 target dates; separate 2025 signing deadline per CNSA 2.0; hybrid KEM deployment; hardware/performance validation; SaaS product road maps. Tiers 1–4.
6Crypto-Agility ArchitectureHardcoded vs. centrally configurable algorithms; KMS/HSM PQC road map confirmation; crypto-agility design mandate for new systems; CA migration. Tiers 1–3.
7HNDL Risk ClassificationData classified by confidentiality lifetime; public-network transit mapping; high-surveillance jurisdiction routing; legacy archive backward exposure. Tiers 1–4.
8Infrastructure DependenciesCloud KMS/TLS migration timelines; network appliance PQC support; OT firmware update/replacement plans; open-source library readiness. Tiers 1–2.
9Testing & AssurancePre-production PQC testing with documented findings; independent third-party cryptographic audit; continuous monitoring with regression alerting; code-signing migration. Tiers 1–2.
10Incident ResponseHNDL-specific and TNFL-specific IR scenarios with separate notification tracks; PFS confirmation; legal/regulatory liability assessment for both threat dimensions. Tiers 1–4.
11Regulatory AlignmentOMB M-23-02/NSM-10; Federal Reserve/ECB/FCA guidance; ENISA/DORA/NIS2 alignment; CA/Browser Forum 47-day cert lifecycle; cyber-insurance HNDL/TNFL coverage. Tiers 1–2.

Source: IDC, 2026

Tiered deployment

Scale assessment depth to vendor risk profile. Build to Tier 1 requirements first; every lower tier is just a lighter version of that same baseline.

  • Tier 1 (Critical): All 48 questions, all 11 domains, full documentary evidence. Financial market infrastructure, healthcare systems, defense supply chain, and PII-at-scale processors. Require an independent third-party cryptographic audit and documented PFS as conditions of contract renewal.
  • Tier 2 (High): ~35 questions, Domains 1–6, 10, and 11. Regulated financial services, managed healthcare, technology companies with sensitive IP.
  • Tier 3 (Standard): ~20 questions, Domains 1–3 and 5. General enterprise software vendors with short-lived sensitive data.
  • Tier 4 (Low Risk): Five baseline questions: cryptographic inventory, vulnerable algorithm identification, NIST PQC migration road map, HNDL acknowledgment, and crypto agility.

Five-level maturity model

Score each vendor across all 11 domains against Table 2. A maturity level supported by domain-level evidence is materially more informative than 48 individual answers, and it’s what produces the year-over-year improvement signal boards want to see.

TABLE 2: Five-Level Vendor Quantum Readiness Maturity Model

LevelMaturity Description
Level 1Unaware: no inventory, no named executive owner, no road map
Level 2Inventoried: cryptographic inventory complete across all four pillars
Level 3Road Mapped: board-approved migration plan with named owner, dated milestones, and allocated budget
Level 4Piloting: PQC algorithms tested in pre-production; hybrid KEM deployed on at least one customer-facing endpoint
Level 5Migrating: production migration underway, with regression monitoring to prevent quantum-vulnerable configurations from being reintroduced

Source: IDC, 2026

Beyond the questionnaire: The continuous operating model

Quantum readiness is positioned to become the first TPRM domain that is born continuous. Hybrid KEM deployment on production TLS endpoints is externally observable without vendor participation, meaning ratings platforms will convert it into a continuously monitored control once adoption reaches detectable scale. Cryptographic inventories also go stale within months, making an annual questionnaire a poor instrument for this domain. Three converging capabilities define the direction:

  • Quantum Security Posture Management (Q-SPM): Continuous measurement, benchmarking, and remediation of cryptographic exposure across cloud, applications, infrastructure, and third parties, extending point-in-time assessment with automated discovery and runtime posture visibility.
  • Quantum Risk Operations Center (Q-ROC): The operational layer translating continuous telemetry into active risk management: crypto drift detection, certificate monitoring, weak algorithm alerting, vendor quantum exposure tracking, and HNDL dataflow surveillance.
  • Continuous Quantum Control Assurance (Q-CCA): Automated evidence collection, policy validation, and control telemetry replacing periodic manual attestation. Vendors demonstrating Q-CCA represent a qualitatively different assurance tier that Tier 1 and Tier 2 buyers should begin requiring as a contract condition.

What buyers must demand

  • Deploy the 48-question framework now through your existing TPRM questionnaire builder, applying the tiered model to your vendor portfolio. Accept low initial evidence rates, record them as your baseline, and track year-over-year improvement. Vendors who cannot improve over successive cycles reveal program immaturity.
  • Require a tool-generated Cryptographic Bill of Materials (CBOM) in CycloneDX 1.6 format from Tier 1 and Tier 2 vendors, covering all four inventory pillars plus signing infrastructure. Ingest it directly into your GRC platform for automated maturity scoring.
  • Apply Mosca’s inequality per vendor and per data class to produce a data-driven HNDL exposure register for your board. Score vendor road maps against the 2030 encryption and 2025 code-signing CNSA 2.0 deadlines. A road map with a completion date beyond 2035 commits the vendor to operating disallowed cryptography.
  • Make perfect forward secrecy (Q42) and code-signing migration to hash-based schemes (Q39) near-term contractual requirements for all Tier 1 and Tier 2 vendors. PFS is the single most actionable HNDL mitigation today. A vendor with PFS implemented but no code-signing migration has mitigated HNDL while leaving the TNFL surface fully open.
  • Incorporate four contract elements for Tier 1 and Tier 2 vendors: (1) PQC milestone commitments aligned to NIST IR 8547 with specific dates; (2) PFS across all customer-facing TLS with confirmation that session keys are not retained; (3) HNDL notification triggers obligating vendors to notify you if your data has been subject to collection; (4) documentary audit rights over the cryptographic inventory. Translate the framework into contract language now; vendors will otherwise present you with their version first.
  • Brief your board using five quantum trust KPIs: Quantum Readiness Index, HNDL Exposure Score, Crypto-Agility Score, Quantum Trust Score, and Migration Velocity. These transform quantum readiness from a qualitative narrative into a quantifiable governance instrument.

What vendors must build

The structural tooling gap in the TPRM market is not a warning signal. It is a market opportunity with a closing window. The following priorities are immediate for both TPRM platform vendors and technology and service providers:

  • TPRM platform vendors: Build a production-ready quantum encryption readiness module now. The IDC 48-question framework is the baseline that standardization will converge toward. No platform has shipped this capability. The first-mover position is open and uncontested. Design for continuous cryptographic posture monitoring: hybrid KEM detection, certificate algorithm currency, weak cipher alerting, running in the background rather than surfacing once a year in a questionnaire. Integrate Q-SPM and Q-ROC capabilities into your product roadmap. Build CBOM ingestion in CycloneDX 1.6 format as a standard evidence intake workflow.
  • Technology and service providers: Build your response program to Tier 1 standards proactively. Your most sophisticated customers are already asking PQC questions through ad hoc TPRM additions. Year-one evidence providers will win procurement decisions. Responding with documentary evidence in 2026 is a genuine competitive differentiator. Establish a board-approved migration road map with named executive ownership, dated milestones, and budget before your customers ask. Findings discovered internally are far less damaging than those surfaced in customer due diligence.
  • On AI governance positioning: Avoid feature-washing. Buyers with even moderate sophistication now distinguish genuine AI risk governance from relabeled existing capabilities. Map your platform’s capabilities to the NIST Cyber AI Profile’s three risk areas and publish a roadmap commitment. That window narrows fast once a competitor ships first.
  • On PQC advisory services: Develop a repeatable cryptographic inventory methodology as the entry-point engagement. A scoped inventory producing a CBOM is comprehensible to a non-technical buyer, has a clear deliverable, and creates a multi-year upsell path to migration services across financial services, healthcare, defense supply chain, and critical infrastructure.
  • Product roadmap horizons: Now (2026): native 48-question module, tiered deployment tooling, DORA compliance modules, unified cross-framework mapping. Near-term (2027): Q-SPM benchmarking, CBOM ingestion, Cyber AI Profile alignment, agentic AI governance workflows. Medium-term (2028–2030): full Q-ROC capabilities, continuous vendor posture monitoring, hybrid cryptography management, EU CRA compliance modules.
“

Q-Day is not a risk event. The risk event is the moment your board asks what your vendors’ quantum exposure is across your critical data flows, and there’s no answer ready. For vendors, it’s the same moment from the other side: a customer asks, and there’s nothing to hand them.

— Philip D. Harris, CISSP, CCSK, Research Vice President, Governance, Risk, and Compliance Solutions, IDC
Philip D. Harris, CISSP, CCSK

Philip D. Harris, CISSP, CCSK - Research Director, Governance, Risk, and Compliance (GRC) Solutions

Phil Harris is Research Director for GRC Solutions at IDC, where he develops and promotes IDC's point of view on risk, advisory, privacy, and compliance services and software. He conducts research on business strategies and the impact of relevant offerings…

Every enterprise AI deployment, regardless of the function it serves, confronts the same fundamental challenge: the humans it is meant to assist do not yet fully trust it, and in most cases they should not. Not because AI is incapable, but because capability and trustworthiness are not the same thing. A model can produce accurate outputs and still fail to earn trust, because trust is not a technical threshold. It is an accumulated record of demonstrated, observable, measurable performance over time, in your environment, on your data, with your specific consequences attached.

This paper draws on IDC’s research into AI adoption in governance, risk, and compliance (GRC) and third-party risk management (TPRM) environments, two of the most accountability-dense proving grounds for AI in the enterprise. But the framework it presents is not domain-specific. The principles that govern how AI earns the right to operate with less human oversight in vendor risk scoring apply equally to invoice processing, contract review, HR screening, IT operations, customer service, supply chain management, and every other domain where AI is being deployed to augment or eventually replace human judgment. The domain changes. The way trust gets earned doesn’t move much: the same evidence requirements show up whether it’s vendor risk scoring or invoice processing.

The urgency is shared by both sides of the market. Buyers are deploying AI faster than they are building frameworks to govern it, and are accepting vendor claims about AI readiness without the empirical evidence those claims require. Vendors and platform providers are shipping AI capabilities without the instrumentation that would let buyers verify those claims, prioritizing adoption metrics over the accountability infrastructure that durable enterprise trust requires. Both are operating on assumptions that the next two to three years will make untenable.

“

AI autonomy in any business function is not a leap of faith. It’s a performance record, built from evidence the organization demanded and outcomes it tracked before signing off on anything further.

— Philip D. Harris, CISSP, CCSK, Research Director, Governance, Risk, and Compliance Solutions, IDC

Why the clock is running: Five forces behind the shift

Five structural forces are already compressing the timeline, and no business function is exempt:

  • Information and decision volume: The volume of AI-generated outputs, alerts, recommendations, and decisions is growing faster than human capacity to review them: regulatory updates and vendor risk signals in GRC, transaction exceptions in finance, ticket volumes in customer service. The math converges on the same conclusion: human review at full scale is becoming operationally unsustainable.
  • Process velocity: Attack life cycles are compressing in cybersecurity as AI-augmented adversaries move faster. Market response windows are compressing in finance and commerce as algorithmic competitors act in milliseconds. Customer service response-time expectations are compressing too. Human approval workflows haven’t kept pace in any of the three.
  • Regulatory obligation acceleration: IDC’s research finds governments expanding regulatory requirements across AI governance, data privacy, financial compliance, and supply chain integrity faster than most compliance teams can track and operationalize. Autonomous monitoring of regulatory change is moving from advantage to necessity fastest in the functions where IDC sees this pressure hitting hardest — GRC, finance, and supply chain.
  • Talent scarcity: The shortage of qualified professionals in cybersecurity, compliance, finance, legal, and IT operations is structural and deepening. Human-in-the-loop models will fail not from unwillingness to provide oversight but because insufficient qualified people exist to provide it at the scale modern programs now demand.
  • Accountability and insurance pressure: IDC is seeing regulators, auditors, and cyberinsurers start to scrutinize whether organizations with available AI automation capabilities are exercising reasonable due care by deploying them. Across financial controls, healthcare compliance, and supply chain risk, failure to automate a well-understood, AI-ready activity may itself become a due diligence problem.

The universal principle: Autonomy is earned

The path from supervised AI assistance to trusted autonomous operation requires one thing above all others, no matter the function: a deliberate, measurable, evidence-based progression. Autonomy is earned through demonstrated performance in your environment, on your data, with consequences that match what’s at stake. It can’t be granted on the basis of vendor benchmarks, aggregate customer data, or demonstration environments.

Six conditions must be satisfied simultaneously before an AI system should be authorized to operate autonomously on any activity:

Universal Automation-Readiness Trigger Criteria (All Six Required)

  1. Sustained performance above accuracy thresholds across all applicable metric categories for the specific activity
  2. Statistically significant transaction volume from actual operations, sufficient to eliminate performance variance as a confounding factor
  3. Zero critical override events, meaning no human corrections involving high or critical severity outcomes, during the measurement window
  4. Full audit trail integrity confirmed for all measured activities
  5. Explainability standards met: every output includes rationale and confidence indicators human reviewers can evaluate
  6. Scope-bounded proposal: the automation covers the precise activity demonstrated, not a broader expansion of AI authority

These six conditions are domain-agnostic. T hey apply equally to a vendor risk tiering model, a fraud detection engine, a contract review system, an HR screening tool, and an IT incident classifier. The accuracy thresholds, transaction volumes, and severity definitions will differ by domain and by organization, but the six conditions above don’t change with them.

The framework applied: What earned trust looks like across functions

Table 1 applies the IDC earned-autonomy framework to seven business domains, mapping the AI activities in each, the metrics that build the performance record, and the signal that justifies reducing human-in-the-loop requirements. GRC and TPRM are included as the anchor domain from which this framework was developed, but the pattern is consistent across all seven.

DomainAI ActivityTrust-Earning MetricsHuman-in-Loop Exit Signal
GRC / TPRMVendor risk tiering, control assessment, audit finding classification, regulatory mappingRisk-scoring delta, concurrence rate, override trend, mapping fidelity98%+ concurrence across statistically significant volume; zero high-severity overrides
Finance & AccountingInvoice processing, expense approval, fraud detection, financial close reconciliationException rate, false positive/negative on fraud flags, reconciliation accuracy, override frequencySustained low exception rate with no material errors over defined period
Legal & ContractsContract clause extraction, obligation tracking, NDA review, regulatory change mappingClause extraction accuracy vs. legal review, missed obligation rate, attorney modification rateAttorney modification rate below defined threshold; zero missed material obligations
Customer Service & CXTicket routing, response drafting, sentiment classification, escalation decisionsResolution rate without human transfer, customer satisfaction delta, escalation calibration accuracyResolution rate exceeds human baseline; escalation accuracy within defined tolerance
HR & TalentResume screening, onboarding workflow, policy exception evaluation, performance flaggingRecruiter override rate, candidate outcome alignment, policy accuracy, bias audit resultsOverride rate declining trend; independent bias audit confirming fairness standards
IT OperationsIncident classification, change approval triage, security alert prioritization, patch risk scoringCorrect severity classification rate, false positive alert rate, SLA adherence, change-failure correlationClassification accuracy exceeds human baseline; false positive rate within operational tolerance
Supply Chain & ProcurementSupplier risk scoring, purchase order approval, delivery exception management, contract complianceSupplier tier accuracy, PO exception rate, SLA breach prediction, compliance gap identificationTier accuracy above threshold across statistically significant supplier population

Source: IDC, 2026

Across all seven domains, two metrics are consistently the most informative. The override and correction rate trend is the primary signal: a sustained downward trend across a statistically meaningful sample is the strongest available evidence for an automation-readiness decision, more reliable than any single accuracy snapshot. Time-to-trust progression is the longitudinal complement, converting AI trust from a qualitative assertion into an auditable, time-stamped record that procurement, compliance, and audit functions can independently review.

What earning trust looks like in practice

There are seven design principles for how AI systems should communicate and present autonomy readiness to the humans who govern them, as relevant to an accounts payable AI as to a vendor risk scoring engine:

  • Confidence-based readiness notifications: Replace binary automate/don’t-automate prompts with performance dashboards drawn from the organization’s own transaction history. The AI should be able to say: “Over the past 90 days, I processed 1,240 invoice exceptions. Your team modified 15, a 98.8% concurrence rate. All 15 were low-value adjustments. I am ready to handle routine invoice exceptions independently. Want to review the full report first?” This framing works identically whether the domain is accounts payable or vendor risk management.
  • Scope-bounded proposals: AI should never propose automating an entire function. Narrowly bounded proposals, covering precisely the activity for which performance has been demonstrated, build trust systematically. “I’ve demonstrated consistent accuracy on routine contract clause extraction for standard NDA templates. I’d like to automate this for standard templates only, not for custom agreements or clauses involving liability caps, which I will continue to flag for attorney review.”
  • Graduated autonomy with check-in intervals: Frame automation as a time-bounded trial with built-in review milestones. IT incident classification might use a 60-day supervised period, HR resume screening a 90-day trial, and financial close reconciliation a 30-day window, each with its own review checkpoint built in.
  • What’s ready to run on its own? Risk-stratified automation lanes answer that with a clear visual map: what AI is ready to handle independently, what’s approaching readiness, and what remains a human decision. In supply chain, that looks like: ready (routine delivery confirmations), approaching readiness (standard supplier reassessments), human required (new supplier onboarding and contract terms).
  • Plain-language explainability: Every AI output needs a practitioner-readable narrative. Statistical confidence scores alone aren’t enough. An accounts payable clerk approving an AI recommendation isn’t a data scientist. A compliance analyst reviewing an AI regulatory mapping isn’t an engineer. Match the explanation’s depth to whoever’s reading it — clerk, analyst, or engineer.
  • Reversibility assurance: Every automation proposal must state, without hedging, that the decision isn’t permanent — the human can reclaim control at any time, and every autonomous AI action is logged, reviewable, and reversible. Fear of irreversibility is one of the biggest psychological barriers to AI adoption, and the fix for it lives in the platform’s architecture: audit logs, one-click rollback, a visible control panel.
  • Proactive limitations transparency: Before requesting expanded authority, AI should present the scenarios its performance record doesn’t cover. A fraud detection model should say plainly that it hasn’t been tested on novel payment schemes it hasn’t seen yet. An HR screening model should name the edge cases where its training data leaves coverage gaps. A contract review system should flag the clause types where its accuracy data is thinnest, and keep flagging them until the data catches up.

What buyers must demand across every AI deployment

  • Require native AI performance instrumentation as a universal procurement condition. Vendors must demonstrate continuously measured decision accuracy, concurrence rates, and override-pattern tracking built into the platform architecture from day one. Any vendor that can’t produce auditable performance records from your environment, rather than benchmark data or aggregate customer statistics, isn’t ready for deployment in a consequential business function.
  • Reject feature-toggle automation models. Automation should be narrowly scoped, risk-stratified, and explicitly reversible, with reassessment checkpoints built in from the start. A vendor pitching automation as an all-or-nothing switch, in vendor risk management or invoice processing alike, either doesn’t understand accountability requirements or is prioritizing adoption metrics over program integrity.
  • Audit your own data infrastructure before expanding AI capabilities. AI operating on incomplete, inconsistent, or stale data gets rejected by experienced practitioners fast, and the gaps are rarely subtle: GRC environments run on incomplete control taxonomies, finance carries legacy transaction classifications, HR’s job-description taxonomies are inconsistent from team to team. Data quality is the buyer’s responsibility. AI underperformance rooted in bad data is the buyer’s problem to fix.
  • Require explainability and confidence scoring on every AI output. A compliance analyst, an accounts payable clerk, a recruiter, and an IT operator all need to understand why the AI made the call before they act on it, even though how much technical depth each of them needs is different.
  • Map each AI deployment to a 24-month autonomy horizon. For every AI system you’re running, formally assess which activities will need less human oversight within that window, and check whether the vendor’s architecture can support the transition. A vendor without a credible autonomy road map is a short-term fix, fine for now, but budget for a replatform in year two.
  • Build an enterprise AI trust registry. Organizations deploying AI across multiple functions need a centralized view of where each deployment sits on the earned-autonomy progression. Without this visibility, the board and C-suite cannot govern AI risk across the enterprise, and the organization cannot identify where human-in-the-loop requirements are becoming operational bottlenecks.

What vendors must build, no matter the domain

The vendors who define the next generation of enterprise AI, regardless of domain, will be those who understood that earned autonomy is not a feature to add but an architecture to build from the first line of code. The requirements are universal:

  • Instrument AI performance natively from day one: decision accuracy, concurrence rates, and override patterns, continuously measured and surfaced inside the platform natively. A finance automation tool without override tracking, an HR system without concurrence-rate measurement, and a GRC platform without explainability logging are all making the same architectural mistake. Buyers are already starting to require this as a procurement baseline.
  • Design automation as a graduated, reversible progression: the feature-toggle model is wrong for GRC, and it’s just as wrong for invoice processing, HR screening, IT operations, and supply chain management. Graduated, risk-stratified, reversible automation is the right architecture for any consequential deployment. Vendors who build it into their platforms are winning more evaluations already, and it shows in which vendors keep getting shortlisted.
  • Build role-aware communications: the practitioner who needs to trust an AI vendor risk score isn’t the same person who needs to trust an AI invoice exception flag. Both need explainability, confidence framing, and reversibility assurance pitched to their role — a compliance analyst’s dashboard looks different from an AP clerk’s.
  • Invest in data quality infrastructure as a prerequisite to AI credibility: outputs built on incomplete or stale data get distrusted fast by practitioners who’ve seen it happen before. Vendors who help buyers see and fix their data quality gaps, instead of glossing over them in marketing claims, build the kind of customer relationship that survives a bad quarter.
  • Design for an autonomous operations horizon: information volumes, process velocities, and talent constraints will make human-in-the-loop models operationally untenable within two to three years, not just in GRC but in finance, HR, IT operations, and supply chain. Vendors architecting for supervised assistance only are building toward a ceiling on their own addressable market — a ceiling that shows up in the RFPs they stop getting invited to.
  • Treat the enterprise AI trust registry as a platform opportunity: organizations running AI across multiple functions need one centralized view of earned-autonomy status in place of the scattered, disconnected dashboards most AI programs default to. Vendors who build cross-functional performance dashboards, unified audit trails, and trust-progression tracking into a single pane of glass are positioning for the RFPs where the buyer already has three vendors and needs to compare all three the same way.

None of this requires a new department or a multi-year transformation program. It requires running the same test on every AI deployment already in production: what’s the override rate, is it declining, and has anyone looked at the audit trail in the last 90 days? Start there, on the deployment that’s been live longest, and the rest of the enterprise AI trust registry follows from what you find.

Philip D. Harris, CISSP, CCSK

Philip D. Harris, CISSP, CCSK - Research Director, Governance, Risk, and Compliance (GRC) Solutions

Phil Harris is Research Director for GRC Solutions at IDC, where he develops and promotes IDC's point of view on risk, advisory, privacy, and compliance services and software. He conducts research on business strategies and the impact of relevant offerings…

EMEA enterprises have stopped debating whether AI matters. The harder question – can they run it at scale, on budget, with trust intact – is where the next 12 months will be decided.

Ambition is no longer the constraint

Ask a CEO in EMEA whether AI will reshape their business model and you get near-unanimity: 99% of EMEA CEOs told us AI gives them a chance to reinvent how their organization makes money over the next three to five years. AI strategy now sits alongside security as one of the two topics boards want to hear about beyond the numbers.

So the interesting story isn’t appetite. It’s what happens after the mandate lands. Agents are already in production across cybersecurity, IT, HR, and customer service – not in a lab, in the business. And 95% of EMEA enterprises say they’re running agents in production today – which tells you about reach, not readiness.

Which raises the question every CIO and CFO in the region is now asking each other: what does this actually cost, and can we control it?

The execution gap is the real story

Our maturity benchmarking tells a blunter story than the boardroom optimism suggests. Roughly two-thirds of EMEA organizations are still in the early stages of AI maturity. EMEA matches the rest of the world on ambition – but not on maturity. The gap isn’t interest. It’s capability.

And it shows up in money. Enterprises are running over budget on agent spend, then increasing it anyway because standing still costs more. The pressure is showing up in four places at once: nobody can trace AI cost back to a specific workflow, nobody has staff for AI FinOps, pricing models are opaque, and agent usage across functions is outrunning governance.

Capping spend is not the same as controlling it. That distinction is where the next wave of value – and the next wave of disappointment – will be decided.

Funded ambition plus lagging capability equals stalled deals. Deals shrink, cycles stretch, and the organizations that close the gap win the cycle.

What separates the organizations pulling ahead

The pattern among AI-fueled enterprises is remarkably consistent, and it’s less about models than most people expect. Value-driven AI rather than bolt-on features. A funded roadmap with defined outcomes rather than a portfolio of pilots. Governance built in, not retrofitted. A modular platform with shared, connected data. And a continuous learning loop that adapts as evidence arrives.

There’s one more, and it’s the one that surprises people: the human premium lasts. Trust and human judgment don’t get automated away – they get more valuable. When we asked what agents are actually judged on before scale-up, reliability came first, and accuracy a close second. Raw execution speed ranked below both.

Agentic ROI, in other words, is a discipline – not a calculation.

Where we go deeper

In our upcoming webinar, we’ll open up the full data set behind this picture: the EMEA agent adoption curve out to 2030. What agents actually cost enterprises per month today. Where the extra AI budget is being pulled from. The use cases already widely deployed by function. And the capability gaps customers most want closed.

If you’re building the business case, pricing the workflow or writing the governance framework this planning cycle, this is the evidence base to bring with you.

Navigate your next move with confidence. Join us – and bring your hardest questions.

Source: IDC Worldwide CEO Survey, March 2026; IDC Future Enterprise Resiliency & Spending Survey, Wave 4, August 2026; IDC MaturityScape Benchmark: The AI-Fueled Organization 2.0, May 2026; IDC Early Adopter Agentic AI Use Case Study, March 2026.

Lapo Fioretti

Lapo Fioretti - Senior Research Analyst, AI-Fueled Business Strategies

Lapo Fioretti is a Senior Research analyst for IDC's AI-Fueled Business Strategies team. In his role, he is the lead for Europe, Middle East and Africa AI-Fueled Business Strategies research, examining organizations' digital and AI maturity, key priorities and use…

Techtember is upon us, and we’ve already seen new phones and smartwatches launch from multiple brands. I’ve spent the last few weeks trying out Google’s latest and walked away impressed yet measured in my enthusiasm. Google has never really competed on hardware specs. The pitch with Pixel has always been a clean software experience, long update support, and the best version of Google’s own AI. Competitors like Apple and Samsung offer versions of the same thing, but their scale forces a different approach. They’re serving tens of millions of buyers with a wide range of needs, so their software has to work broadly. Google doesn’t have that constraint. Pixel can stay narrow and lean all the way into AI without worrying about covering every use case.

That tradeoff shows up clearly on the latest Pixel smartphones. Consumers don’t get the best speeds and feeds, but what they do get is a well-rounded package that does a handful of things really well. And with hardware innovation maturing on the smartwatch front, Google’s software has to carry even more of the weight to keep users delighted.

What the shipment numbers show

The numbers back this up. Pixel held about 1.1% of global smartphone shipments in Q2 2026, roughly where it’s been for the past year (it ranged between 1.0% and 1.3% over the last five quarters). The Pixel 11 lineup isn’t going to move that. Pixel’s smartwatch business tells a similar story: Google’s watch brand held 0.6% of smartwatch shipments in Q2, down from a holiday-quarter spike of 1.4% in Q4 2025, and it’s been under 1% in four of the last five quarters. Apple and Huawei dominate that market instead, with a combined share of roughly 36% of smartwatch shipments in the latest quarter, and Pixel isn’t close to changing that on either device heading into a rougher stretch for both markets.

IDC’s forecast has both smartphone and smartwatch shipments declining, driven by rising component costs and tighter availability, memory in particular. This is where Google’s scale matters: it can access memory that smaller brands can’t get at any price, because suppliers prioritize volume buyers. Google will likely pay more for it, but paying more and not being able to get it at all are very different problems. In this environment, that’s the advantage carrying Google’s hardware business, even though it won’t show up in the shipment numbers.

I don’t think Google spends aggressively to chase phone or watch share even with that advantage. Doing so would put it in more direct competition with Samsung and the rest of the Android OEM base, the same partners Google depends on to keep Android’s ecosystem healthy. Pixel’s role is closer to a halo product: it shows the rest of the industry, and Google’s own partners, what good software and AI implementation looks like, without trying to out-ship them.

Hands-on with the Pixel 11 and Watch 5

I’ve spent real time with both devices, and there are standout features on each, along with a few that need another pass. On the Pixel 11, Magic Capture is a legitimately good feature. It shoots continuously and picks the best frame afterward. As the father of a one-and-a-half-year-old who’s constantly moving around, this has been game-changing, and worth the upgrade on its own for anyone coming from an older Pixel. But while Google’s camera-based features are top notch, some other AI features fall short. Smart Reply on the keyboard is the one I’d flag as not working well yet. The suggestions are often generic enough that anyone who knows you can tell they’re AI-generated, and off-target often enough to be more annoying than helpful.

Pixel Watch 5 kept the same design as its predecessor, which means bands and chargers carry over, and shifted the entire upgrade case to software: Health Guardian’s insulin resistance and blood pressure trend tracking, better GPS, and more proactive Gemini coaching are all meaningful upgrades. The catch is that Health Guardian, despite being right on trend with insulin resistance and blood pressure trends, needs about a month of data before it’s genuinely useful, so the watch doesn’t feel profoundly different out of the box from previous generations.

The most interesting feature Google showed off, one that hasn’t shipped yet, is the watch’s ability to detect that you’ve fallen asleep and stop music playback on Pixel Buds. It’s a small thing, but it’s the same instinct as Magic Capture: removing a task the user would otherwise handle manually. The obvious extension is the smart home. If Gemini already knows you’ve fallen asleep, that’s a natural trigger for a routine: locking the door, arming the security system, dimming the lights, all without extra setup. Google already has the pieces (Nest, Home routines, Gemini across devices), and this is the kind of feature that could make the ecosystem case for Pixel stronger than any single device spec, and make Google’s AI implementation something competitors will envy.

None of this changes Pixel’s position in the market. It’s not trying to be a share leader, and the forecast headwinds hitting the rest of the industry will hit Pixel too. What Pixel is doing is setting a bar for what AI-driven software should feel like on a phone or a watch. Samsung and Apple will have to answer to it eventually. So will the rest of Android, once the ecosystem catches up to where Gemini already is.

Jitesh Ubrani

Jitesh Ubrani - Director, Consumer Devices Research

Jitesh Ubrani is a Director at IDC leading a team of analysts within the Worldwide Consumer Device Trackers group, covering wearables, augmented reality (AR), virtual reality (VR), tablets, phones, PCs, gaming, and smart home devices, with a focus on market…

OpenAI’s decision to pull its models from Cursor marks an inflection point in the battle for agentic coding. OpenAI will end Cursor’s direct access to its models on November 12, 2026, following SpaceX’s acquisition of Cursor. The decision will remove OpenAI models from Cursor’s managed model-selection experience, although developers can continue using supported models through their own API keys. Cursor will also lose contractual access to future OpenAI models such as Astra.

The withdrawal turns model access into a competitive instrument and pushes the agentic coding market toward tighter integration between models and harnesses. OpenAI strengthens Codex by removing a leading alternative harness for its models. SpaceX gains a stronger incentive to combine Cursor’s outstanding harness with Grok and establish Grok as a direct competitor to the leading coding models. Anthropic’s continued support for Cursor preserves Claude’s distribution through the platform and deepens an alliance shaped by compute, distribution, and the companies’ respective competitive interests. OpenAI, SpaceX, and Anthropic now enter the next phase of the competition with different combinations of models, harnesses, infrastructure, and developer adoption.

IDC’s Point of View

Model distillation has become a first-order competitive risk for technology suppliers

OpenAI’s dispute with Cursor shows that model distillation has become a first-order competitive risk for technology suppliers. OpenAI cited a prior contractual violation by Twitter, and Elon Musk’s acknowledgment under oath that xAI used OpenAI outputs to train Grok in violation of its terms. SpaceX now controls both Cursor and Grok. This ownership structure gives OpenAI grounds to assess whether Cursor-managed access could generate outputs for developing a competing model. Cursor itself has not been accused of misusing OpenAI models.

Model distillation uses responses from a capable model as training data for another model. The process can transfer aspects of the original model’s performance without access to its weights or original training data. Cursor can generate a large and concentrated stream of OpenAI outputs across code generation, debugging, code review, tool use, and complex software-development tasks. Those outputs could provide valuable training data for Grok, particularly if Cursor received access to future models such as Astra.

Allegations that Chinese model developers used outputs from U.S. models to improve their own systems first drew broad attention to this risk. The Cursor dispute brings the same issue into a commercial relationship between U.S.-based technology companies. Commercial integrations can magnify the exposure because they generate model outputs at scale and within structured workflows. The risk becomes particularly significant when the customer also owns a competing model.

OpenAI’s decision illustrates why technology suppliers increasingly treat control over model outputs as part of their competitive strategy. Developer-supplied API keys will establish a direct contractual relationship between OpenAI and each API customer. That relationship could improve attribution and enforcement relative to a Cursor-managed integration. Technology suppliers will increasingly need to evaluate customer ownership, the volume and structure of expected outputs, and the potential value of those outputs to a competitor.

Ending direct model access strengthens Codex’s competitive position

OpenAI’s withdrawal will strengthen Codex by removing Cursor as a leading agentic coding harness with native, managed access to OpenAI’s models. Codex is designed to optimize GPT-5.6 Sol and future models across context management, task planning, tool use, repository interaction, and code execution. Cursor currently gives developers another outstanding harness for applying OpenAI models to software-development tasks. Removing that option will make Codex a more important destination for developers who want OpenAI’s strongest models combined with a harness optimized specifically for them.

Native, managed access to OpenAI’s strongest models will give Codex a clearer source of differentiation in agentic coding. This advantage helps explain why OpenAI is willing to sacrifice revenue from Cursor-managed model usage. Some usage could shift to developer-funded API access or Codex, but the decision shows that OpenAI assigns strategic value to controlling how its strongest models reach developers.

The withdrawal will weaken Cursor’s competitive position by narrowing its native access to frontier models. Developer-supplied API keys will preserve access to supported OpenAI models but will not replicate Cursor-managed model selection, billing, routing, and integration. Cursor will become more dependent on Anthropic, while pressure grows on SpaceX to advance Grok 4.6 and its successors as coding models that can compete with GPT-5.6 Sol, Astra, and Claude Opus 5.

Grok 4.6 is underestimated in agentic coding

Grok 4.6 is underestimated as a competitor to OpenAI and Anthropic for agentic coding. The model has gained meaningful adoption in Cursor since its release, which suggests that developers increasingly consider it viable for demanding software-development tasks. Its use across code generation, debugging, repository analysis, tool use, and long-running agentic tasks indicates that its practical standing among Cursor users exceeds its broader industry reputation.

SpaceX has an opportunity to convert this adoption into a more durable competitive position. Grok 4.6 benefits from direct integration with Cursor, which lets SpaceX optimize the model and harness as a combined system. The model has not established the developer mindshare or production track record of GPT-5.6 Sol and Claude Opus 5. OpenAI’s withdrawal nevertheless gives SpaceX a stronger incentive to advance Grok into a direct competitor to the leading coding models. A more capable Grok will give SpaceX greater control over model availability, cost, optimization, and integration with Cursor’s harness.

Anthropic’s support cushions Cursor and may reflect the value of SpaceX compute

Anthropic’s decision to preserve Claude access cushions Cursor from the effects of OpenAI’s withdrawal. Cursor will retain an important model family for software development after OpenAI models leave its managed model-selection experience. That continuity gives Cursor flexibility as SpaceX improves Grok and evaluates its broader model strategy. Anthropic preserves distribution through a leading coding platform, while SpaceX avoids the immediate loss of another major model provider.

Anthropic’s willingness to preserve this relationship may also reflect the strategic value of its broader relationship with SpaceX, including access to compute. Anthropic restricted Windsurf’s access to Claude when OpenAI moved to acquire the company, which demonstrated its willingness to limit model access after a competitor gained control of a coding platform. Its different treatment of Cursor suggests that the SpaceX relationship materially influences its decision. Access to SpaceX’s compute resources provides a plausible reason for Anthropic to preserve that relationship. The value of that access may outweigh concerns about competition from Cursor and Grok.

The Musk-Altman conflict now shapes enterprise agentic coding

The conflict between Elon Musk and Sam Altman now shapes the competitive landscape for enterprise agentic coding. SpaceX’s acquisition of Cursor gives Musk control of a leading coding harness and places it within the same corporate group as Grok. OpenAI’s withdrawal strengthens Codex, reduces Cursor’s direct access to OpenAI models, and increases the importance of SpaceX’s relationships with other model providers. The dispute now affects model distribution, product integration, and competitive alignment across the market. Musk’s statement that he “couldn’t care less” about OpenAI’s decision understates its significance.

What this means for the market

OpenAI’s withdrawal shows that the battle for agentic coding remains wide open because competition increasingly occurs between combinations of models and harnesses. OpenAI can tightly couple Codex with GPT-5.6 Sol and future models such as Astra. SpaceX can deepen the coupling between Cursor and Grok, while Anthropic can optimize Claude for Claude Code. Each company can align model behavior with context management, task planning, repository interaction, tool use, code execution, and validation. None of these positions establishes a decisive market leader.

Tight coupling gives providers greater control over model access, optimization, cost, and product development. OpenAI can develop future models with Codex workflows in mind, while SpaceX can optimize Grok for Cursor. Anthropic can coordinate the development of Claude and Claude Code as a combined system. These relationships can produce performance and product advantages that are more difficult to achieve when the model and harness are developed independently.

Loose or semi-loose coupling creates a different source of value. Cursor can give developers access to Claude, Grok, and supported open models through a common environment, which allows them to select different models for particular tasks. This flexibility also exposes the platform to changes in model access, pricing, and competitive alignment. The same questions about model-harness coupling will shape GitHub Copilot, Google Antigravity, Cognition’s Devin, and other agentic coding platforms. The market will therefore test how different degrees of model-harness coupling affect performance, flexibility, cost, and control. OpenAI’s withdrawal brings that architectural question to the center of agentic coding competition and leaves its answer wide open.

Arnal Dayaratna

Arnal Dayaratna - Research Vice President, Software Development

Dr. Arnal Dayaratna is Research Vice President, Software Development at IDC. His research focuses on agentic AI, generative AI, foundation models, agentic coding technologies, and low-code and no-code developer technologies. He also examines the broader technology stack around foundation models,…

The security services market in Asia/Pacific (excluding Japan and China) is on track to grow from $10.8 billion in 2024 to $16.6 billion by 2029, a 9.1% CAGR, according to IDC’s 2026–2029 forecast. The market is changing internally as AI takes over routine tasks, a shift that used to increase staffing and spending in managed security services. Now the focus is moving toward advisory, integration, and governance work instead.

What’s Driving the Shift from Managed to Advisory Services?

AI-powered threats, tightening data governance rules, and a persistent skills gap are turning security services into a critical business requirement rather than a technology cost center organizations can cut when budgets tighten. Growth is concentrating in advisory and integration work in countries like India and South Korea, where digital transformation is accelerating alongside demand for AI applications. That’s pulling security services growth away from more mature technology hubs like Singapore and Hong Kong.

As AI reduces labor needs in managed security services, IDC suggests cybersecurity service providers can succeed by implementing outcome-driven pricing models, developing advisory and governance capabilities, and getting established early in the region’s emerging market segment.

The region’s security services market is shifting from traditional operations to advisory. Every buyer needs security services, but fewer are willing to pay for headcount when AI can do the routine work. The goal is to move toward outcome-based delivery, integration, and governance — and the providers who can reprice around outcomes while leading with compliance and sovereignty readiness are the ones who will win this cycle.

Segment Landscape: Where Is the Growth?

Asia/Pacific* Security Services Spending by Segment, 2024–2029 (US$M)
Segment2025 Spending2029 Spending (Forecast)CAGR 2025–2029
Managed security services$4,879$6,4067.0%
Project-oriented services$5,011$7,49210.6%
Support services$1,838$2,72410.3%
Total$11,727$16,6229.1%
*Excludes Japan and China.  Source: IDC’s Asia/Pacific (excluding Japan and China) security services forecast, July 2026

IDC Outlook: What’s Next?

Growth is shifting toward the region’s emerging-tier economies. By 2029, India, Korea, and other emerging markets are expected to surpass the broader region, rising from about a third to over 40% of revenue. Growth in Singapore and Hong Kong will stabilize in the meantime. Australia remains the largest market, accounting for nearly a third of regional revenue, but its growth rate will lag the overall growth rate. IDC forecasts that security services providers will prioritize deepening existing accounts over winning new customers.

From an industry perspective, financial services and the public sector together account for roughly half of regional revenue, driven by ongoing regulations and threat exposures that keep both industries investing steadily in security. Manufacturing and resources are expanding rapidly as industrial and operational environments evolve. Healthcare remains the smallest and slowest-growing sector, held back by limited budgets.

What Could Accelerate This Shift?

  • Agentic AI is moving the SOC from human-run to machine-assisted. Autonomous AI agents are transforming purchasing and delivery models. Short-term security services spending is focused on governance, trust frameworks, and integration, while the labor intensity of managed services keeps falling over the medium term.
  • Digital sovereignty is becoming a persistent regional requirement. Government policies on data governance and localization are making compliance a continuous expense that spans budget periods, which benefits cybersecurity providers with local presence, expertise, and sovereignty capabilities.
  • Pricing is shifting from headcount resources toward automation and outcomes. With AI now handling tasks L1 analysts in a SOC used to perform, headcount-based pricing no longer makes sense — cybersecurity providers can keep expanding despite the persistent talent shortage.

What Could Slow It Down?

  • A reactive security posture hinders strategic security investments. If security is still treated as an incident-response function rather than a strategic pillar of business resilience, security budgets stay tactical and reactive.
  • Fragmented security environments within an organization slow adoption. Fragmented and isolated security solutions erode buyer trust and lengthen evaluation periods, delaying investment commitments even as integration demands grow.
  • A persistent talent shortage constrains delivery and absorption alike. A shortage of qualified security and automation talent limits how quickly cybersecurity providers can staff projects and how rapidly buyers can adopt new solutions.

Key Indicators to Watch

Three things will shape how far and how fast this shift goes: how quickly organizations trust autonomous AI actions in the SOC, how much national data-sovereignty rules diverge from country to country, and how quickly the security talent pool grows.

See the full 2026–2029 market sizing, segment breakdowns, and growth forecasts behind this analysis. Download the IDC Market Forecast. Talk to IDC about what’s next for security services in your market. Contact Us.


Yih Khai Wong - Senior Research Manager - IDC

Yih Khai Wong is a senior research manager for IDC Asia/Pacific's Cybersecurity practice, supporting cybersecurity research and client engagements through the Asia/Pacific Security Opportunities: Trust and Resilience program. Yih Khai's area of focus is on security technologies, including cloud-native application protection, identity, endpoint and network security. He works closely with technology vendors and buyers, delivering actionable market insights and advice within the cybersecurity ecosystem. Before rejoining IDC, Yih Khai was a principal analyst covering the cloud, datacenter, and edge computing market with ABI Research. Prior to that, Yih Khai was in EY, in his capacity as an assistant director at EY's research and insights group. Yih Khai started his analyst career with IDC Malaysia as an analyst covering the enterprise applications market.

很多人聊保险业的生成式 AI,第一反应都是 “省人力、提效率、降成本”,把它当成存量周期里的运营优化工具。但 IDC 的核心判断是:这是对技术价值的严重低估。生成式 AI 真正重塑的,从来不是单点运营效率,而是保险业整条价值链的价值边界 —— 它正在推动行业从被动赔付的“风险兜底者”,向主动干预风险的“价值创造者”跃迁。

2026 年作为规模化落地的关键拐点,最终比拼的不是大模型的技术能力,而是找对场景、走对节奏的判断力。本文我们就从市场逻辑、价值穿透、落地误区与建议三个维度,拆解这场正在发生的产业范式变革。

  1. 存量周期下,生成式 AI 是保险业少数能算清 ROI 的技术投入

很多人觉得当下保险业数字化投入在全面收缩,但 IDC 看到的真相是:预算不是在降,而是在精准分化。

2025 年中国保险业站在深度转型的关键路口,利率持续下行、赔付支出高企、人力成本上涨的三重压力并未消解,行业经营逻辑已从规模扩张转向精细化运营。这一阶段最鲜明的特征是:数字化投入全面 “有保有压”—— 能降本控险、满足监管要求的项目投入保持稳定,无法量化收益的项目被严格管控,行业从“被动收缩” 转向“主动取舍”,投入产出比成为筛选 IT 项目的核心标准。

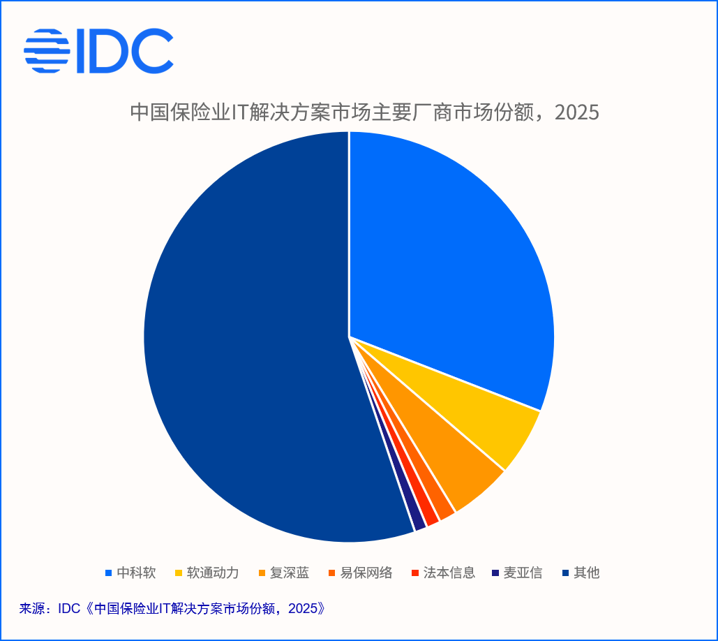
从市场基本面看,国际数据公司(IDC)近日发布的《中国保险业IT解决方案市场份额,2025》报告显示,2025 年中国保险行业 IT 解决方案市场规模达 100.6 亿元,降幅已明显收窄,正式进入企稳分化与存量竞争新阶段。市场呈现“一超 + 长尾”格局:一方面头部集中度持续提升,龙头厂商的客户、产品与服务壁垒不断加厚;另一方面长尾市场体量依然庞大,垂直细分场景与技术创新应用仍存在大量生存空间。

在这样的周期下,生成式 AI 成为少数既能契合监管 “防风险、促合规、降成本、提质量”主线,又能量化产出价值的技术方向。当保费增速放缓、人力规模收缩,通过 AI 提升人均产能、优化运营成本、创新服务模式,已经成为险企穿越周期的核心战略,而非可选项。

2、7.5 倍增速绝非概念泡沫,生成式 AI 已从“试点品”变为 “硬刚需”

市场上至今还有声音认为生成式 AI 仍是噱头、投入多产出少,但 IDC 报告显示:2025 年中国保险业 IT 投资规模达 517.3 亿元,其中硬件板块增幅显著,核心驱动力来自自主创新与 AI 基础设施建设。长期来看,2030 年中国保险行业 IT 投资规模将达 805.5 亿元,年复合增长率为 9.3%。

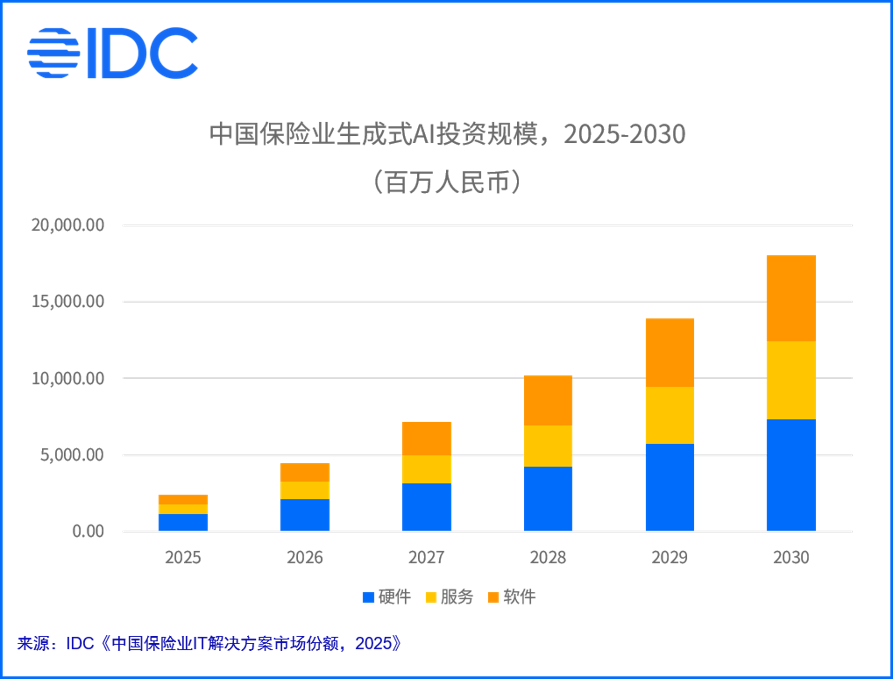
而生成式 AI 领域的增长远超整体大盘:投资规模从 2025 年 24.22 亿元升至 2030 年 180.05 亿元,五年增长近 7.5 倍,年复合增长率超 49%。这意味着生成式 AI 已彻底走出概念验证阶段,正式进入规模化投资周期,是当前保险科技领域最具确定性的增长引擎。

3、AI 穿透全价值链,改写的是每个环节的价值定义

很多人对 AI 在保险业的价值认知还停留在 “客服机器人”“自动核保省工时”,但 IDC 认为,生成式 AI 的改造是深入骨髓的 —— 它正在改写定价、核保、理赔、服务、风控的每一个底层逻辑,从辅助工具进化为核心生产系统,在每个环节都在拓展行业的价值边界。2026 年将是保险行业生成式 AI 从“试点” 走向 “规模化”的关键之年,保险 IT 系统内置 AI 能力将成为行业标配。

产品定价:从静态精算走向个体实时风控

传统定价依赖历史数据与静态模型,本质是群体层面的风险均摊,难以反映个体风险动态变化。生成式 AI 正在把定价变成随个体行为实时波动的变量:车险 UBI 模式通过车联网数据实现驾驶行为定价,健康险通过可穿戴设备将保费与健康管理挂钩。未来的核心竞争力将是基于客户实时行为与外部风险信号的动态定价能力,推动行业从 “群体定价” 向 “个体定价” 演进。

核保理赔:智能决策重构效率与信任双重底座

生成式AI对于核保理赔的真正改变是把依赖人工经验的风险判断,变成了标准化、可追溯的智能决策。智能核保系统自动解析病历、体检报告,将数小时人工核保压缩至分钟级;图像识别自动定损车辆,OCR 快速提取医疗票据,大模型辅助责任判定。这不仅大幅缩短理赔周期、降低查勘成本,更从根源上压缩了人为操作空间与欺诈风险,重构了投保人与理赔端的信任机制 。

客服营销:对话式 AI 把渠道系统变成产能放大器

IDC预测,到 2026 年险企与投保人超 60% 的交互将通过数字自助服务实时完成。智能客服已升级为具备多轮对话、意图识别、情感分析能力的对话式 AI,大幅提升服务体验与响应效率。营销端的改变在于重塑作业模式:生成式 AI 基于客户画像生成个性化保障方案,智能问数让业务人员通过自然语言即可查询业务数据。渠道 IT 系统的价值从 “支持运转” 变为 “产能放大器”。

风险减量:推动行业从被动赔付转向主动价值创造

传统保险业的价值终点是出险赔付,本质是“风险兜底者”。但生成式 AI 正在把行业的价值边界往前移。农业领域用气象大数据与卫星遥感指导防灾减损,财险领域用物联网监控安全生产,健康险领域用平台引导健康管理。大模型在其中扮演核心角色 —— 海量数据实时分析、风险模型动态迭代、预警信号精准推送,均依赖生成式 AI 的能力支撑,推动行业从“事后赔付” 向 “事前预防”延伸,真正成为“价值创造者”。

4、转型的真正瓶颈不是技术,而是三个被高估的难题

生成式 AI 的规模化落地并非坦途,数据治理、组织能力、合规风控是公认的三大挑战。但在 IDC 看来,挑战并非都是长期壁垒,其中有短期可突破的关口,有被过度放大的伪命题,更有被忽视的增量机会。

第一,数据治理:“先治理后落地” 是最大的转型伪命题。数据治理不是 AI 落地的前置条件,而是与 AI 场景落地相互驱动的长期工程。IDC建议,短期优先补齐数据质量、数据血缘、元数据管理能力,优先保障核心场景 AI 输出的一致性和可信度,用小切口场景快速验证价值;中长期通过战略合作推进数据架构重构。而IFRS17 全面实施与生成式 AI 场景落地,本身就是倒逼数据治理加速的强大动力。

  • 组织转型:组织重构与“ROI闭环”才是真挑战。技术与组织的错位是主要矛盾——多数银行在组织重构、流程再设计建设方面明显滞后于技术演进速度。真正的组织挑战是如何建立组织信任、设计人机分工模式、培养全员人机协作能力。IDC 判断,到 2029 年 40% 的保险从业者需要掌握人机协作技能。此外,存量竞争下,生成式 AI 是少数能清晰量化 ROI 的技术方向,险企需要把 AI 当作“直接绑定业务成果的能力”,而不仅仅是工具的使用。
  • 合规风控:监管不是绊脚石,是差异化壁垒与全新赛道。很多人把强监管当成 AI 落地的最大阻碍。但我们认为,合规正是筛选玩家的竞争壁垒,甚至是全新的增量赛道。IDC建议,短期从数据、模型、流程、人才四个层面推进负责任 AI(RAI)建设,把合规要求嵌入 AI 全流程,筑牢落地底线;中长期全面改革治理、风险与合规框架,适配 AI 规模化应用的管理需求。

IDC总结与展望

生成式AI之于保险业,不是工具升级,是价值重塑。2026年是规模化落地的分水岭——技术能力已不是门槛,真正的较量在于:谁能率先找准场景、跑通ROI闭环、完成组织适配。

IDC判断,未来三年行业将呈现明显分化:头部险企通过AI重构定价、核保、风控全链路,把“风险经营”变为核心竞争力;观望者将困在降本增效的浅层,错失价值跃迁的窗口期。这场转型,比的不是算力与模型,而是价值边界拓展的速度与决心。

IDC更多相关研究:

进一步交流

如您希望深入了解保险业生成式AI的落地路径、场景优先级、ROI测算框架或组织转型实践,欢迎随时与我们联系。IDC金融研究团队可提供定制化数据研判、厂商对标与策略建议,助力您在关键拐点精准布局。期待与您深度对话。请点击此处联系我们。

Siri Si

Siri Si - Research Manager

Siri Si is a Research Manager for IDC Financial Insights. His core research scope includes the latest development models and trends in the financial industry, and the development and application status of various technologies in the financial technology field, focusing…

Somewhere in the last twelve months, a lot of B2B marketing leaders noticed the same unsettling thing: website traffic quietly dropped. As one tech CMO put it in a recent conversation, “Overnight our website traffic tanked. Buyers have shifted to AEO and engage with us much later in the decision journey.”

That single sentence captures a shift IDC has been tracking closely.  Buyers haven’t stopped researching. They’ve stopped researching on your website.

The vendor website is no longer the front door

For years, marketing built its funnel around a predictable first move: a prospect lands on your homepage, browses a few pages, and eventually fills out a contact us form. That assumption no longer holds.

IDC’s research on B2B tech buying describes AI answer engines as becoming the new front door to a brand. Buyers are increasingly turning to AI tools to discover and research complex purchase decisions, often ahead of, or entirely instead of, a visit to a vendor’s website. This isn’t a niche behavior confined to one function or region. AI-mediated discovery is becoming a core practice in how tech buyers navigate the buyer journey.

AI is redefining the early stages of engagement.  Buyers enter vendor conversations more informed, and often further along, than ever before. By the time a prospect might have clicked “Contact Us,” they’ve frequently already formed an opinion, shaped by an AI agent that never visited your homepage.

Conversational AI is disrupting the interface itself

The bigger shift isn’t only where research happens.

Matthieu Houle, CIO at ALDO Group, described this well:

“

Consumers now rely on assistants that feel almost human, know their preferences, and offer neutral, best-for-me advice that reshapes how they validate and decide what to buy.

— Matthieu Houle, CIO at ALDO Group

That’s not a fringe behavior anymore, and it isn’t limited to consumer categories. In B2B, buyers are beginning to delegate real portions of the research and shortlisting process to AI agents, sometimes even early sourcing and comparison work, before a human on either side gets involved. The traditional search bar or browse-and-click interface many of us have designed our entire digital experience around is quietly being displaced by conversation. Buyers ask an assistant a question and get a synthesized, cited answer, often without ever seeing a vendor’s homepage, navigation, or carefully crafted hero message.

Discovery no longer behaves like a single moment; it’s becoming a continuous feedback loop. And discovery does not simply equal SEO. Visibility inside an AI-generated answer is only one output of a much larger shift. Buyer research has been diversifying for years, spreading across social platforms, communities, and industry expert content well before AI entered the picture. AI accelerated that fragmentation and gave it a new interface.

It’s worth being honest about where the shift stops, too. IDC’s research is clear that human engagement still matters most at the moments of highest stake: negotiating price and contract terms, finalizing complex purchases, and building trust during evaluation. AI is disintermediating discovery and early-stage research. The human relationships that close deals haven’t gone anywhere, at least not yet.

Marketing’s response: becoming the conductor, not just the funnel owner

The old model had marketing owning a channel mix that fed a linear funnel ending in a form fill.  That model no longer describes what’s happening. Marketing’s evolving role is closer to conducting in real-time, agent-mediated, orchestrated journey, where content, channels, intelligence, and automation work in concert. The buyer, and increasingly the buyer’s AI agent, moves fluidly across all of them at once, not following a single predictable path.

One global CMO I spoke with put it simply:

“

Our primary objective is to move beyond using AI as a set of discrete tools and instead build integrated, AI-enabled systems that can orchestrate end-to-end marketing workflows.

It’s not about bolting an AI chatbot onto an existing website. It’s about rebuilding the underlying systems so that whoever, or whatever, is doing the research finds a consistent, structured, trustworthy story no matter which door they come through.

That same CMO also pointed to a shift in how marketing and sales work together. Marketing used to generate a lead and hand it to sales in sequence. Now the two functions share an AI-orchestrated approach to revenue execution. AI agents coordinate targeting, timing, and messaging in real time based on buyer behavior, while humans concentrate on strategy and the relationship-building moments that still require a person in the room.

Marketing’s own operating model has to evolve alongside this. The organizations furthest ahead have stopped managing channels and started engineering the systems that shape discovery, interpret buyer intent, and influence decisions before a brand enters the conversation. Some describe this as a shift toward a more autonomous, adaptive, and agentic marketing function.

What this means for marketing leaders

None of this means your website is irrelevant, or that buyers have vanished. The moment of first contact has moved upstream, into AI-mediated research that most marketing teams cannot yet see, measure, or influence directly. Marketing’s job has expanded from managing a channel mix to orchestrating a machine-and-human journey.

A few implications worth sitting with:

  • Content needs to be built for machines to cite, not just for humans to browse. Structured, specific, and authoritative content is more likely to surface inside an AI-generated answer than a beautifully designed but ungated PDF.
  • Marketing is becoming the conductor of a real-time, agent-mediated journey. That requires connected data and intelligence underneath every touchpoint, from chat to video to community, tied to the same underlying data set.
  • The org chart may need to catch up. Most tech marketing organizations still don’t have an enterprise AI roadmap that transforms how the business operates, rather than simply layering AI tools on top of existing workflows.
  • Sales resources should concentrate where humans still win. Pull early qualification effort back. Reinvest it in negotiation and complex deal-closing, where buyers still consistently prefer a person.

The prospects who matter most to your pipeline are still out there, researching and comparing. The organizations that earn visibility and trust inside that AI-mediated research phase get a shot at the deal long before “Contact Us” is ever pressed.

Laurie Buczek

Laurie Buczek - Group Vice President, Market & Business Intelligence

Laurie Buczek is Group Vice President of Market & Business Intelligence at IDC, leading global team of researchers and executive advisory on AI-fueled business transformation, market dynamics, channel, ecosystem and go-to-market strategy. She oversees the analysis of external forces—economic, regulatory,…