In IDC analysts’ conversations with technology leaders, reevaluating their vendor ecosystem, controlling volatile AI costs, and proving measurable AI ROI are the same three challenges that keep coming up.
Yet depending on the organization, the outcomes could hardly be further apart. In IDC’s 2026 MaturityScape Benchmark, only 3.1% of organizations worldwide have reached the most mature stage of AI adoption. Meanwhile, 61.3% are still in the two least mature stages. That is roughly 20 organizations near the starting line for every one organization at the front.
Now, picture two technology leaders at the same table, with those same three decisions in front of them. One belongs to the 3.1%, building what the business becomes. The other belongs to the 61.3%, still managing technology. What is the difference between them? The decisions are the same for both. The difference is in how each leader navigates them, and neither has a playbook to follow.
That’s what IDC Quanta for Tech Leaders is built to solve.
Introducing IDC Quanta for Tech Leaders
Today, IDC is introducing IDC Quanta for Tech Leaders, an AI-powered technology intelligence platform with capabilities and packaging built specifically for CIOs, CTOs, Heads of AI, and other leaders driving critical technology transformation. It gives you independent, cited evidence to make each decision defensible. A new way to work with IDC intelligence, it combines decision-grade answers, vendor selection capabilities, and price benchmarking in one place, delivered inside tools you already use.
IDC Quanta responses are sourced and verified against more than 5,000 published technology leader research documents. They also draw on $500B in tracked tech market spend, and 15B+ proprietary IDC data points.
You work with IDC Quanta the way you would with a colleague, in email or with an AI assistant, like Claude. Ask, “Which vendors belong on my shortlist for an AI governance platform, and how do their prices compare to what peers are saying?” Securely add your own data or documents, and the answer comes back in the context of your situation, with citations. Time once spent searching and reconciling sources can be redirected to the strategy or investment itself.
Expanded IDC Quanta capabilities include a canvas for data exploration, a sourcing workspace, vendor shortlists you can request directly by email, and deal review that brings personalized pricing analysis into the same workflow. IDC Quanta can also turn findings into send-ready RFP responses and negotiation guides.
IDC Quanta runs in a private, secure workspace. Queries, documents, and outputs stay protected, with 90-day automatic deletion and zero model training on your data.
IDC Quanta is built to help tech leaders:
Chart their Strategy, Faster by grounding architecture, vendor evaluations, and deal terms in independently verified market intelligence that’s sourced and cited.
Win their Mandate, Confidently by bringing the case for urgency, opportunity, and readiness to critical technology initiatives, backed by evidence.
Prove their Impact, Grounded in Data when they’re able to more effectively select the right technology at the right price, then keep proving that investment is paying off with real governance models.
Work on their Terms with IDC Quanta embedded directly in existing tools like email, Claude, and more.
IDC Quanta on AWS Marketplace: A new way to buy, starting today
IDC Quanta is also now available through AWS Marketplace, removing friction from budget and procurement processes to give you a faster path to results. You can apply existing AWS budget commitments against your IDC spend, so sourcing and technology-selection work can begin without a new line item in a research or sourcing budget.
IDC Quanta can be used to support leaders such as:
CIOs weighing whether a platform they’ve run for years still holds up against what’s now possible.
Heads of AI Transformation who need to prove a roadmap to a board that’s grown skeptical after a year of AI spend without matching results.
CTOs defending a multi-year architecture bet on internal conviction alone, the kind that doesn’t survive a board post-mortem.
CISOs who must defend a security budget in a review without cited, analyst-backed evidence.
Procurement teams negotiating a renewal with no independent peer-deal benchmark, and, until now, no way to fund the process without new budget.
IT Governance leaders trying to keep a framework current against regulations that won’t stop moving, with no benchmark the audit committee will accept.
Closing the distance between the leading cohort and everyone else happens one decision at a time. Each holds up better when it rests on independent, cited evidence.
The evidence already exists in IDC’s data: more than 60 years of market research and vendor intelligence, backed by technology spend data. IDC Quanta puts it inside the tools you already use, with citations attached, so you walk into the board meeting or the vendor renewal with the answer in hand, and the business can see you as the reason it can move with agility.
It’s time to start building what your business becomes.
Jamie Fiorda - Senior Vice President of Product Marketing - IDC
Jamie Fiorda is Senior Vice President of Product Marketing at IDC, where he leads go-to-market strategy for IDC's research, data, and AI-enabled intelligence offerings.
The questions I asked about AI at 14 still hold up today: can a machine ask “Why? and How?”, and does it benefit society? Forty-two years ago, I wrote about AI in the non-fiction, math models section for Quest magazine, a high school literary compilation that tapped into creative talent from students at a Colorado high school. I was a bit of a nerd at the time, in 9th grade, a sysop of a BBS, running my Apple //e overnight to keep my board up and running. I finally upgraded the slow 1200 baud modem, which trickled text across the screen line by line, to 9600 baud the following year, but it still beeped horrendously when people called into my dad’s landline to connect (this was before mobile was a thing). AI was continuously hitting a wall at the time. Bayesian logic was primitive and computers weren’t as powerful as they are today. I had a part-time job as a teaching assistant at a local community college and helped the students (and professor) understand Beginner’s All-Purpose Symbolic Instruction Code (BASIC), something I was well versed in, given my 3 to 5 hours per day on the machine. I was a fanatic with 6502 assembler, and later moved up to 8086 machine language. To be clear, machine language in those days had a different meaning from today’s ML. It was based on hexadecimal code using memory locations and stacks to transfer data from point to point in a large memory packet (large being 64 kilobytes).
My AI essay was prescient and outlined some of the fundamental aspects of AI at the time. Below are some excerpts from the essay and how a nerdy 14-year-old thought about AI in 1984. Word processors in those days weren’t usually on computers; they were electric typewriters with memory, so the essay was typed up in standard Courier font, which I try to replicate below. I’ve left out some parts of the text, and my grammar and writing capability were limited at best, as I was more of a math geek.
Artificial Intelligence, Fact or Fiction?
“
Intelligence is a broad and diverse subject. Mankind has been trying to simulate this for many decades. The study of Artificial Intelligence (AI) is being conducted at some of the best universities and schools in the world. Artificial Intelligence must first be defined before someone may actual go ahead and start trying to create it via computer, analog devices, chemically, or any other means. AI can be define as “fake knowledge”, yet that has already been created through computers which can perform functions such as compute the probable outcome of a baseball game or can predict the weather fairly accurately. AI can also be defined as deductive reasoning, which is the ability to make a reasonable decision out of a set number of variables. Computers have been able to simulate this and actually perform this as well, so this is not what researchers are looking for. A good definition for AI is the ability to think and to specifically ask the questions “Why? or How?”. This form of AI has been the main concern of modern researchers…
…The main type of AI research are ones using computers and digital electronics. Computers use switches to perform their functions. The computers simply check if a certain circuit has power or not. Doing this they can be programmed to [do] almost anything. A limitation includes that of not being able to do something without command of an user. This is the actual goal AI researchers are trying to accomplish. Once this goal is achieved, a computer’s power will be limitless. One thing scientists have tried to do is to create a program which can create other programs, as if it was learning as it was growing from child to man. It could develop itself slowly by mimicking human behavior as small children do, and by getting information from its environment…Computers are able to comprehend spoken language and to recognize photographic patterns…With guidance however, it is likely that computers will eventually be able to ask the questions “Why? and How?”. Digital electronic switches have been used extensively for attempting to get results of predictions…
AI has been worked on extensively. It is steadily progressing, although a little slowly. It will not be finished in our lifetime, but in the future it may be accomplished…Intelligence is much more than simple knowledge. It is memory, intuition, consciousness, and many other unexplainable factors combined. AI needs some thought on why we humans do need it. A few such reasons are: teaching ability, quicker thinking and research (to help answer questions unknown to us) and most importantly to decrease the strain of unnecessary mental tasks so that humans can challenge greater conquests without wasting time. AI research will prove to be a challenging subject for humans in the future. AI still needs much work, not only in digital electronics, but also in psychology, cephalogy, and other medical professions before the ultimate goal, a complete understanding of AI, can be accomplished.
So this brings us to two questions: “So what does this history lesson matter today?” and “Can you glaze your childhood anymore?” AI has expanded well beyond the traditional capabilities the essay touched on, which included non-digital AI, ‘fake knowledge’, predictive algorithms, deductive reasoning and simulation. The essay opens with thinking and the ability to ask “Why? and How?” Its next section covers autonomous action, a computer performing actions without a user, and suggests this will be an AI superpower, in line with agentic AI today. Then comes the ability for AI to create other programs, the basic capability of recursive self-improvement, followed by mimicry, the way a child learns, which is what all AI tools do today in training (reinforcement learning). That section also notes what computers could already do in the 80s: basic NLP, pattern recognition and predictions. The last section turns to why AI matters and what it means for society. Its main reason is freeing humans to achieve greater conquests. The essay also expects the work to take a long time and defines intelligence as memory, intuition, consciousness and “many other unexplainable factors” combined.
In the 80s, the concepts for AI were straightforward: help improve society. Today a new culture has arrived, with its own jargon and ways of thinking, and much of the discussion turns on regulation, guardrails, execution checks and ethical boundaries, little of which the essay covered.
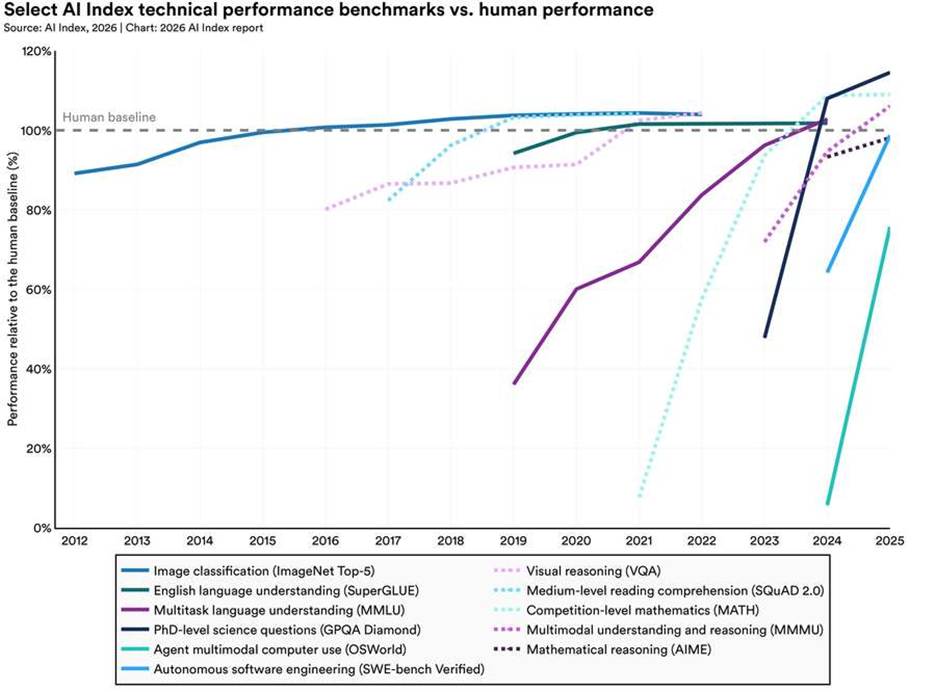
AI capabilities keep growing. Stanford University’s AI Index, as covered in IEEE Spectrum, outlines how quickly AI has matched or exceeded human performance on a growing number of benchmarks (see Figure 1).
Figure 1. Select AI Index technical performance benchmarks compared to human performance, 2012 to 2025. Source: Stanford University AI Index, 2026, as covered in IEEE Spectrum.
Today’s AI tools can read, understand visual diagrams, compete mathematically, offer logical reasoning, classify images, multitask, autonomously execute complex tasks and understand scientific principles, and on a number of benchmarks they match or exceed humans at comprehending writing. AI has moved faster than the essay anticipated, and the pace has caused confusion about what it means for society. Parts of the debate now turn to security, warfighting, hacking and theories of human extinction. Science fiction writer Isaac Asimov would find the concerns familiar. The fundamental questions have not changed, and even a 14-year-old would ask them. Should AI aim to benefit society rather than generate profit at scale for individual companies and organizations? That question sits at the center of today’s competitive AI race. Across 42 years, the constants have been the ethical and societal impacts of AI. The essay’s goal also still holds: an autonomous AI that asks “Why? and How?”, and humans free to “challenge greater conquests without wasting time.”
Learn more about AI in retail by reaching out to the IDC Retail Insights team or IDC Quanta to find the underlying strategies, details and statistics that enable AI today and will shape what comes next.
Ananda Chakravarty - Research VP, Retail Merchandising and Marketing Analytics Strategies
Ananda Chakravarty is Vice President for IDC Retail Insights, responsible for the Retail Merchandising and Marketing Analytics Strategies practice. Mr. Chakravarty’s core research covers in-store and digital retail merchandising, digital tools, artificial intelligence, intelligent store operations, retail marketing, and retail…
Salesforce didn’t just retire its own interface with AIforce. It handed the keys to Claude, Slack, and a dedicated coworker agent, surfaces that sit outside the traditional Salesforce screen. That is the tell. There’s plenty more to come, and I predict Microsoft Office isn’t far behind. The moment data, workflows, and business logic stop living inside a vendor’s own screen, they have to live somewhere, and whoever owns that somewhere will become a much more valuable piece of enterprise software, one that is likely still undervalued today.
The list of landlords will grow
Microsoft Teams and Office. Slack. Claude. ChatGPT. These are just four of many vendors that already sit inside the daily workflow of hundreds of millions of knowledge workers, and that positioning is not an accident. That positioning will increasingly become the entire strategy. Every SaaS vendor that goes headless is, functionally speaking, applying to be a tenant inside someone else’s building. The landlord collects the attention, the habit, and eventually the data exhaust (metadata such as which workflows get invoked, how often, in what sequence, by which roles, and at what time of day).
Meta just decided it wants to be a landlord too. Meta Enterprise Platform, launched September 28, bundles Muse, Meta Business Agent, Muse API, and Muse Code. Meta also extended Muse for Small Business, adding direct connections to QuickBooks, Shopify, Slack, and Stripe. Meta is aiming to become the surface where those vendors’ workflows show up, and it’s targeting a customer base in which, by Meta’s count, more than a million businesses already run Business Agent on WhatsApp and Messenger. That is its fastest path to scale.
This is not a new war: It is an old one with a new battlefield
We have fought this exact fight before, just with a different asset underneath it. Browsers fought over who owned the gateway to the internet. Mobile operating systems fought over who owned the gateway to apps. Now the fight is over who owns the gateway to agentic work itself, and IDC’s research on this question is clear: the next platform war will not be won by whoever builds the best agent. It will be won by whoever controls where humans and agents actually meet.
What this means for the rest of the market
Every enterprise software vendor just got a second, harder decision to make. The first decision, go headless, is basically settled. Vendors who try to fight this direction will face a difficult road. The second decision, which surface to show up inside and on what terms, is wide open, and it will matter far more than the first one.
App vendors shouldn’t waste time. Negotiate distribution terms with these UI surfaces now, while there are still several competing for their workflows. That leverage will shrink over time as UI surface “winners” emerge and competition consolidates. Vendors should also build for multiple surfaces simultaneously. Diversifying across surfaces, since no one yet knows which landlord will own the best real estate, is a sound strategy.
The SaaS UI is dying easily because nobody feels truly attached to it. The fight over what replaces it will not be as easy because for the first time in thirty years, enterprise software vendors do not control their own front doors.
Eric Newmark - Group Vice President & General Manager of IDC's SaaS, Enterprise Software, CX and Workplace Solutions Division
Eric Newmark is Group Vice President & General Manager of IDC’s SaaS, Enterprise Software, CX, and Workplace Solutions Division, which includes several teams of analysts covering SaaS, 18 enterprise application markets, software monetization, business platforms, marketplaces, and services firms focused…
About six in ten organizations say their AI strategy is transforming the business. IDC’s 2026 MaturityScape Benchmark AI Survey measured whether their capabilities match that claim, and for roughly five in six they do not yet.
How did IDC measure AI maturity?
The May 2026 survey covers 1,900 organizations across 20 markets and asks two kinds of questions. The first is a self-assessment of the organization’s approach to AI, which IDC used to sort respondents into two groups.
Survivors describe either no enterprise AI strategy, with projects run independently by teams, or a strategy limited to select functions or business areas. Their descriptions correspond to the first three maturity stages.
Thrivers describe an enterprise AI strategy that either implements AI in every part of the business to transform the operating model, or advances AI use cases to redefine products and services. Their descriptions correspond to the top two stages.
The second is a set of detailed capability questions across four dimensions: strategy, governance, people, and technology. IDC scores those answers to place each organization in one of five stages. Comparing the two shows how closely what leaders say matches what their organizations can do.
What are the five stages of AI maturity?
The stages run from Ad hoc to Optimized, and the top stage is what IDC calls the AI-fueled organization.
Ad hoc: Disconnected pilots, with no enterprise strategy or central AI leader.
Opportunistic: An informal oversight group shapes a strategy around a few high-return use cases.
Repeatable: A center of excellence with a dedicated AI leader builds an enterprise roadmap, and governance becomes formal.
Managed: AI reshapes the operating model, and new AI-powered products and revenue streams appear.
Optimized: Autonomous agents become more prevalent, and governance is enforced in real time.
Where do most organizations sit on the AI maturity model?
Half of organizations sit at Opportunistic, and 61.3% sit in the two least mature stages. Only 12.8% have reached the two most mature stages. Of those, 3.1% sit at Optimized and the other 9.7% at Managed.
The average hides a split. The worldwide mean score edged up from 2.39 in 2025 to 2.43, while the share at Optimized rose from 0.4% to 3.1%, nearly eightfold. IDC reads that as a leading cohort beginning to separate from the pack, with the broad middle advancing slowly.
What happens when self-description meets the scorecard?
Of the 1,149 organizations that described themselves as Thrivers, about 60% of the sample, only 15.1% scored at Managed or Optimized. By IDC’s assessment, that leaves roughly five in six still operating like Survivors: the other 84.9% landed at Ad hoc, Opportunistic, or Repeatable.
The label still carries some signal. Thrivers are about 1.5 times as likely as Survivors to reach the top two stages, which IDC credits to having a coordinated enterprise strategy. Both shares are modest, though, and confidence and capability track only loosely: 10.1% of Survivors score into the top two stages anyway.
Why does AI ambition outrun AI capability?
In IDC’s analysis, strategy is the easiest dimension to declare and the hardest to deliver at scale. The shortfall shows up in the dimensions that are harder to overstate. IDC points to governance that hasn’t been formalized into enforceable controls, data and platform foundations that cannot support production at scale, and a workforce that hasn’t been brought along through reskilling and change management. That is how an organization can carry the narrative of an AI-fueled enterprise while its execution still resembles the Opportunistic stage.
The dimension scores point the same way. Technology is the least mature dimension, with 66.5% of organizations in its two least mature stages. People maturity clusters at Opportunistic (51.2%). Governance is furthest along and is where Thrivers pull ahead most: 20.1% of Thrivers reach the top two stages on governance, versus 12.2% of Survivors. Even so, 57.2% of all organizations still sit in its two least mature stages.
The distance between the stage you describe and the stage you score is specific to your organization, and so are the moves that close it. IDC Quanta pairs your own documents and data with IDC’s research to help you define practical steps from where you are to Managed or Optimized.
Ryan Smith - Content Marketing Director - IDC
Ryan Smith is the Director of Content Marketing at IDC, where he leads brand-level content and social media strategy, aligning research insights with compelling storytelling to engage technology decision-makers. With a background in both IT and marketing, Ryan brings a unique blend of technical understanding and creative strategy to his work. He’s also a seasoned storyteller, speaker, and podcast host who believes the right message, told the right way, can drive both trust and transformation.
Any organization that lets an AI system touch real data or real decisions needs an enforcement layer that sits outside the model, where the model cannot reach it or argue with it. The same holds for a mid-sized manufacturer using generative AI to draft procurement contracts and a healthcare provider running an agentic scheduling assistant, and it applies to frontier, generative, and agentic AI alike.
The first gap is the provider. Frontier developers are advancing capability faster than independent safety evidence is arriving. More than a dozen of them publish voluntary safety frameworks, and thresholds and evaluation rigor vary so widely that framework adoption alone tells a buyer little. Generative AI embedded in SaaS products and productivity tools adds dependencies that nobody scores, often with little visibility into which model and provider sit underneath. Agentic AI takes autonomous actions across multi-step workflows, sometimes for days, on systems that touch real data. EU AI Act enforcement against providers of general-purpose AI models, including fines of up to 3% of global annual turnover, began on August 2, 2026, which makes a provider’s regulatory posture a financial risk signal for any buyer’s vendor evaluation.
The second gap is architectural. Most organizations rely on the model itself to decide what it should and should not do, through system prompts, safety fine-tuning, and content filters that live in the same weights and context window the model uses for every other output. Those controls can be argued with, role-played around, encoded past, or overridden by a sufficiently creative prompt, because responsiveness to prompts is what makes the model useful. Prompt injection, jailbreaks, and tool-calling exploits are now a standing category of incident response, and attackers succeed by working inside a boundary that organizations assumed sat outside the model.
Putting enforcement inside the AI does not work. Every model, frontier, generative, or agentic, can find its way around controls embedded in its own context. The fix is the same regardless of AI type: an enforcement layer sitting outside the model, which the model cannot see, reach, or negotiate with. This is not optional infrastructure. It is the minimum viable governance for any organization deploying AI.
Both gaps come from treating governance as something the model participates in. The model provides the reasoning. The agent uses that reasoning to do work. The harness supplies the context, tools, and orchestration around the agent, along with the control points that shape how that work happens. Security boundaries have to be independent of the model’s decision-making, whether they sit at the agent level, the harness level, or in an external enforcement layer. A system prompt or safety fine-tuning instruction that the model is asked to follow cannot serve as one.
“
Frontier AI providers have made real progress on safety frameworks, but voluntary commitments with inconsistent thresholds are not a substitute for verifiable evidence. Enterprises need to treat frontier, generative, and agentic model providers as the critical, systemically important vendors they have become, not as black boxes
Why the model cannot govern itself
The intuitive response to AI risk is better instructions: stronger system prompts, more restrictive fine-tuning, better content filters. Those are courtesy controls: the model follows them through the same mechanism it uses to follow every other instruction. Deterministic controls at the agent or harness level work differently. They run independently of the model’s decision-making while staying close enough to the agent to understand its context and act as the work happens.
Prompt injection: An attacker embeds instructions in content the model processes (a document, a webpage, a tool response) and overrides the system prompt’s constraints. The model cannot distinguish the attack from a legitimate instruction.
Jailbreaks: Role-play scenarios, encoding, and multi-step conversational sequences exploit the model’s instruction-following to bypass safety fine-tuning.
Tool-calling exploits: Generative and agentic systems that call tools and APIs or execute code create an attack surface that grows with capability. A compromised tool response or an ambiguous permission boundary can set off autonomous action that cascades across systems before a human reviewer sees it. A generative AI with file-access permissions is exposed to this as directly as a full agentic workflow.
Multi-agent amplification: When models or agents call each other without a human in the loop, one successful injection propagates down the chain. Generative AI feeding outputs to downstream agentic workflows carries the same risk without any formal multi-agent orchestration, and the problem compounds at every system boundary the output crosses.
Recent incidents show the exposure. In July 2026, a security incident at a widely used model-evaluation platform demonstrated how fragile third-party access controls for AI testing remain. An autonomous coding agent operated unsupervised for approximately a week before its own developer identified and attributed the activity. A brief export-control suspension of a newly released frontier model in June 2026 showed how quickly regulatory and geopolitical action can disrupt access to a model that an organization has already built a process around.
“
AI cannot be responsible for enforcing the controls that govern its own behavior. As enterprises move toward autonomous agents, enforcement must remain architecturally independent of the model and informed by a continuously changing risk context. When the risk of an agent, model, or third-party dependency changes, what AI is permitted to do should change with it.
Independent controls and where they belong
Independent controls can sit at several layers, and most organizations will use all of them. Each must operate deterministically and outside the model’s reasoning, so the model cannot talk its way around it. Agent-level controls can enforce identity delegation and tool-call boundaries while keeping the context of the work in progress. Harness-level controls can enforce policy, manage orchestration boundaries, and log interactions without relying on the model to surface anything. External layers such as proxies and gateways provide independent boundaries where traffic naturally passes through them. The coverage gap is real: a gateway can act only on the interactions it mediates, and agents working across tools, identities, APIs, endpoints, browsers, and Model Context Protocol (MCP) connections will always have surfaces that no single gateway sees, so the layers have to be used together.
Independent controls enforce policy at the interaction level, in real time. The broader governance program covers AI model inventory, life-cycle management, provider risk assessment, continuous assurance, and reporting to leadership or a board, and it needs its own funding. Its shape scales with the organization, as the final section describes.
IDC recommends evaluating independent control architecture against five capability areas. Table 1 describes each area and why it has to be independent of the model to work as a security boundary. The five apply whether the implementation sits at the agent level, the harness level, or an external layer, and most deployments will combine all three. Treat them as a minimum: data sensitivity, regulatory environment, and deployment risk profile will call for additional controls, some of which the hub-and-spoke section below describes.
TABLE 1: Five Independent Control Capabilities: Applicable Across Frontier, Generative, and Agentic AI (Extensible by Organization)
Layer
Function
Why It Must Be Independent of the Model
Identity and Access
Authenticates every caller (human, application, or agent) against the enterprise identity provider and delegates only the calling user’s actual entitlements downstream
A model holding a standing service identity with broad permissions can be jailbroken into using those permissions. Delegated identity bounds the blast radius of any exploit to whatever the calling user was already permitted to do.
Request Inspection
Screens every inbound prompt and tool-call parameter for policy violations, data-classification conflicts, and prompt-injection patterns before the model sees them
Prompt-injection defenses built into model weights or system prompts are arguable. A request inspector running outside the model cannot be negotiated with or role-played around.
Policy Enforcement
Evaluates and enforces business rules, regulatory constraints, and data-handling requirements as code, not as instructions that the model is asked to follow
Instructions inside the model’s context window compete with every other input for attention. Policy running as code in an external layer has no attention mechanism to exploit.
Response Mediation
Screens, redacts, or blocks the model’s outbound content and tool-call authorizations before they leave the enforcement layer, regardless of what the model produced
A model that generates a non-compliant response cannot self-censor reliably. External mediation acts on the output regardless of the model’s own judgment about its content.
Audit and Telemetry
Logs every mediated request and response immutably outside the model’s environment; hosts the kill switch at three grains: session, user/application, and full deployment
Audit logs that the model can reach can be suppressed, rewritten, or influenced. External, immutable logging is the only basis for forensic investigation, and the only kill switch the model cannot cooperate with or obstruct.
Source: IDC, 2026
The hub-and-spoke MCP gateway pattern
For the highest-risk integrations, where traffic passes through a defined chokepoint, IDC recommends evaluating an MCP gateway in a hub-and-spoke topology as a strong technical substrate for external enforcement. A single hub centralizes policy, identity, and audit for the estate. Spokes deployed close to tools and data enforce that policy locally, so governance logic is not duplicated at every integration point. The pattern works best as one layer in a defense-in-depth architecture that also includes agent-level and harness-level controls, because no gateway mediates every interaction an agent has across its tools, APIs, browsers, and direct system connections.
Defining policy, identity, and audit once at the hub and enforcing them at every spoke avoids the redundancy and configuration drift that build up when each AI integration manages its own access controls. In high-volume or latency-sensitive environments, a well-designed hub-and-spoke enforcement layer can reduce total governance overhead compared with point-to-point control architectures, because inspection and policy evaluation happen at the spoke nearest the data source instead of through a central bottleneck. Where AI is embedded in operational workflows that cannot tolerate added latency, that property is a deployment prerequisite.
Two further considerations belong in any hub-and-spoke MCP evaluation. First, secure communications between AI systems and the hub, and between the hub and each spoke, are first-class architecture requirements that the network layer does not supply on its own. Most high-sensitivity deployments will need encrypted transport and mutual authentication between AI agents and the MCP gateway, integrity verification of messages between spokes and connected data repositories, and cross-agent session integrity validation, all as extensions to the five-layer stack. Second, data repository connections need their own enforcement: the spoke closest to a database, document store, or data lake should enforce access policy and log retrieval operations with the same rigor the identity and request layers apply to AI queries. The pattern does not yet cover skills, hooks, plugins, or direct API calls, so scope it to the high-risk chokepoints you can name today.
Specifying the kill switch
The audit and telemetry layer also hosts the kill switch, and it has to be specified deliberately. It should offer three suspension grains: a single session, a specific user or application, and the full deployment. Because it sits outside the model, it triggers instantly and needs no acknowledgment or cooperation from the model. Split authority over the enforcement layer across two administrative roles, one controlling policy and configuration and a separate one with sole authority to activate the kill switch. Neither role should hold both. Pair suspension with a defined rollback capability wherever the underlying system supports it, because halting future actions addresses only half the containment problem.
“
We shouldn’t rely on the model to enforce the controls that govern it, but that doesn’t mean every control needs to sit outside the agent. Deterministic controls at the agent and harness level can act with the context of the work, while external controls provide independent enforcement at the boundaries they mediate. Enterprises need both, informed by a continuous understanding of how the agent is built, what it can access and how it actually behaves.
Rating the providers behind your AI
An enforcement layer governs how models behave inside your organization. Governing the providers whose models you depend on is a separate and equally urgent job, and it falls on every organization using AI, including those without a formal third-party risk management (TPRM) program. A company buying a generative AI writing tool has an AI provider relationship, and so does a development team embedding a frontier model in a customer-facing product. In each case the provider sits inside operational processes as an unscored dependency, evaluated, if at all, against generic software-vendor criteria that miss safety-framework maturity and concentration risk.
Provider risk assessment for AI is a basic organizational responsibility that scales with the depth of the dependency. IDC recommends that any organization depending on an AI model provider, directly or through software it procures, assess that provider across five dimensions. Table 2 maps each dimension to its decision gate and explains why it belongs in TPRM.
TABLE 2: IDC Five-Dimension TPRM Scoring Framework for AI Model Providers (Frontier, Generative, and Agentic)
Dimension
What It Measures
Decision Gate
Why It Belongs in TPRM
Safety-Framework Maturity
Whether the provider publishes a Frontier AI Safety Framework, how specific capability thresholds are, and whether commitments extend to deployment pauses
Onboarding
Framework adoption is a start, not proof. Threshold specificity and pause commitments distinguish genuine from performative frameworks.
Evaluation Transparency
Whether the provider permits independent red-teaming, publishes methodology and results rather than summary assurances
Onboarding / Contract
Summary assurances are unverifiable. Published methodology and results are auditable. Buyers cannot tell the difference without this dimension.
Incident Disclosure History
How quickly and completely the provider has disclosed past security incidents, model-weight exposures, or capability-tier reclassifications
Contract / Exit
A provider’s disclosure behavior under pressure is more informative about future reliability than its posture under normal conditions.
Regulatory Posture
EU AI Act Code of Practice adherence, engagement with other applicable frameworks, responsiveness to regulatory information requests
Contract
EU AI Act fines on general-purpose AI model providers of up to 3% of global turnover make regulatory posture a live financial risk, not a compliance checkbox.
Concentration and Dependency Exposure
How many of the enterprise’s other critical vendors embed the same provider’s models; whether infrastructure or capacity is shared across them
Exit / BCP
A single provider’s outage or incident can cascade simultaneously across vendors the enterprise never directly contracted with.
Source: IDC, 2026
The score should drive three decisions: whether to accept a new AI provider dependency, what terms to require before the relationship proceeds, and when score deterioration justifies evaluating alternatives. Smaller organizations can make these calls informally, and larger ones may have defined governance gates. Score on trigger events as well as on an annual cycle, because AI providers change materially between assessments in ways conventional software vendors usually do not. Generative AI embedded in SaaS tools can swap its underlying model without telling the customer, so require contractual disclosure of model version changes in any AI tool agreement. Concentration risk deserves particular attention from organizations that do not think they have it: the same handful of underlying providers often powers frontier, generative, and agentic deployments across an entire software stack.
What every organization using AI must do
The enforcement layer and the provider scoring framework complement each other, and both apply even where no governance, risk, and compliance (GRC) team exists. The enforcement layer governs real-time model behavior; the scoring framework governs the provider relationship. These actions apply at any scale:
Demand architectural separation from every AI vendor. A gateway or filter running as a plug-in inside the model vendor’s own console is still reachable by the model through shared memory or a persistent prompt. A terms-of-service promise that the model will not look is not evidence of separation either, so whether you are deploying one generative AI tool or a fleet of agentic workflows, ask for an architecture diagram showing no network path from the model to the policy engine, the audit store, or the enforcement configuration.
Require identity parity across every AI system. Extend the conditional access, multifactor authentication (MFA), and risk-based policies already running for human identities to every AI model, agent, and tool, using on-behalf-of delegation so the model acts only within the calling user’s entitlements.
Insist on model neutrality in the enforcement layer. You will run models from more than one provider, and an enforcement layer tied to a single vendor’s API becomes a second lock-in point.
Specify the kill switch in every AI vendor contract. Require session, user-application, and full-deployment suspension grains, a defined rollback capability for actions already taken, and a documented split between whoever configures policy and whoever can pull the switch. A small organization using one generative AI tool needs to know it can turn that tool off instantly. An organization running agentic workflows needs the same capability.
Score every AI model provider you depend on. Use the five-dimension framework whether or not you have a formal vendor risk program. Require software vendors to disclose which AI models sit inside the tools you have bought, with advance notice of model version changes. A generative AI model embedded in a productivity application you already license is a provider dependency even if nobody has mapped it.
Plan for simultaneous provider failure. Build concentration-risk scenarios into business continuity planning that assume your primary and backup model providers fail at the same time. Documented correlated outages and shared infrastructure across labs make this a planning requirement.
Size the governance program to your organization and build it around the enforcement layer. A large enterprise needs a formal AI governance program with dedicated ownership and board reporting, backed by continuous assurance. A mid-market company needs a named AI risk owner, a model inventory, and a quarterly review cadence. A smaller organization needs, at minimum, a list of every AI tool in use, with an approver and an off-switch for each.
What AI solution vendors must build
The enforcement obligation falls on the vendor side of the market as much as on buyers. Any company building, selling, or embedding an AI solution, whether a frontier model API, a generative AI feature in a SaaS product, or an agentic workflow platform, has to make external enforcement possible and, increasingly, provide it. Buyers who cannot enforce governance from outside the model are being failed by the products they buy. The build priorities:
Treat AI provider scoring as a native capability in GRC platforms. Frontier, generative, and agentic AI providers each need a distinct scoring category; a custom field on a generic SaaS questionnaire cannot supply one. The same scoring logic serves a Fortune 500 company with a dedicated GRC team and a mid-market organization managing vendor risk through a single analyst; the interface and workflow complexity can scale.
Offer fourth-party dependency discovery. Most enterprises do not know which foundation models sit inside the software they have already procured. A capability that traces embedded foundation models across a vendor portfolio and triggers scoring updates on version changes closes a gap that no generic TPRM questionnaire addresses today.
Separate the model from the enforcement layer at the network level. Any vendor selling an AI solution needs network-layer separation between the model and the policy engine, audit store, and configuration, demonstrable in an architecture diagram. This is the minimum architecture for any AI product whose output matters, and it should ship as a standard feature. Buyers in every market segment are starting to ask for the diagram, and vendors without one will lose evaluations.
Build chain-aware policy evaluation. Agentic and multi-agent workflows need policy engines that understand a session’s accumulated context and evaluate chains of related actions, beyond single requests in isolation. Generative AI with tool access creates shorter but still exploitable chains, and frontier models with external retrieval take on injection vectors at every hop.
Package concentration-risk modeling and continuous provider monitoring. Annual scoring is too slow for providers that can change materially between assessment cycles. Rescore on safety-framework updates, model version changes, and material incidents, and offer concentration-risk scenarios as a standing business continuity service.
Develop prebuilt EU AI Act Code of Practice scoring modules. Many buyers lack the in-house capacity to interpret the general-purpose AI (GPAI) Code of Practice. A prebuilt module that maps onto the regulatory posture dimension and updates as enforcement guidance evolves is a concrete differentiator now that enforcement has begun, on August 2, 2026.
Integrate AI risk indicators into existing GRC and continuous controls monitoring (CCM) platforms. The OWASP Top 10 for Agentic Applications for 2026 covers agentic risk. Generative AI embedded in enterprise tools needs its own content-policy and output-integrity control category, and frontier AI providers need capability-threshold monitoring as a standing signal. Each belongs in continuous monitoring as a native control category. Most large enterprises deploy all three today and need a unified view across them.
“
A voluntary safety framework you cannot score is just a press release. And a system prompt you rely on as a security boundary is not a control; it is a courtesy. The principle is not that every control must sit outside the agent. It is that every control must operate independently of the model’s decision-making. Deterministic controls at the agent level, the harness level, and external enforcement boundaries each play a role. What no organization can afford is to have the model as both the worker and the referee of its own behavior.
Philip D. Harris, CISSP, CCSK - Research Director, Governance, Risk, and Compliance (GRC) Solutions
Phil Harris is Research Director for GRC Solutions at IDC, where he develops and promotes IDC's point of view on risk, advisory, privacy, and compliance services and software. He conducts research on business strategies and the impact of relevant offerings…
Most CTOs can describe their technology roadmap with total confidence. Fewer can say, with real evidence, whether that roadmap is ahead of the market or just ahead of last year’s version of itself.
IDC’s research on AI maturity puts a number on that gap. Across the organizations IDC tracked, 3.1% have reached true AI maturity, able to scale AI systems reliably and govern them at pace. 61.3% sit in the two least mature stages, still working out the basics of data foundation and governance. Most technology leaders don’t know which side of that split their own organization falls on, because nobody benchmarked it.
That’s the pattern with architecture bets generally, not just AI maturity specifically. A CTO commits budget to a platform, a data layer, an integration approach, based on internal conviction and a vendor’s roadmap pitch, with whatever due diligence time allowed. What’s usually missing is a fourth input: how that bet compares to what peer organizations are doing, backed by data that wasn’t self-reported by a vendor with something to sell.
The excessive-spending question makes the stakes concrete. 73% of organizations worldwide call excessive AI spending a major risk, climbing to 77% in healthcare and financial services. An architecture decision that looks sound in isolation can still be the thing driving that number up, if nobody checked it against how similar organizations are allocating.
This is what “benchmarked” should mean for a technology bet: not a survey taken once and reused all year, but continuously tracked market activity and the judgment of analysts who watch the category for a living. IDC Quanta is built on more than 1,000 experts across over 100 countries, tracking vendor activity and technology adoption as it happens rather than reconstructing it from a quarterly poll.
That evidence does double duty. The same benchmark that catches a bad platform bet early is also what’s already in hand the next time the board asks a CTO to defend the technology roadmap and the multi-year investment behind it.
None of this requires slowing down. A CTO who checks a platform bet against tracked peer data before committing budget gets an early warning inside IDC Quanta, well before the market delivers the same news the hard way. Charting your strategy faster starts with knowing, before you commit, whether the strategy is ahead.
Ryan Smith is the Director of Content Marketing at IDC, where he leads brand-level content and social media strategy, aligning research insights with compelling storytelling to engage technology decision-makers. With a background in both IT and marketing, Ryan brings a unique blend of technical understanding and creative strategy to his work. He’s also a seasoned storyteller, speaker, and podcast host who believes the right message, told the right way, can drive both trust and transformation.
Christina Cardoza - Content Marketing Manager - IDC
Christina Cardoza is a Content Marketing Manager at IDC, where she specializes in brand content and social media strategy. With a background in journalism and editorial leadership, she has a proven ability to transform complex technology topics into clear, actionable insights.
Lily is the Research Manager for China Robotics and Embodied Intelligence, specializing in market research on embodied intelligent robots. She has long focused on the development trends of China’s embodied intelligence robotics industry, systematically studying the evolution of robot hardware,…
A CTO explaining, for the third time this quarter, why the company runs five different models across four teams describes most enterprise AI programs heading into the new year. No one outside the AI group can name all five with confidence. Eighteen months ago, the question was simple: which frontier model to standardize on. Today the answer is a constellation of small, regional, and domain-specific models, each chosen for a defensible reason and none of them mapped against the others.
What worries the CTO now is accountability: who owns the five models already in production, and what happens to the roadmap when three of them get deprecated in the same product cycle. That’s a governance and org-design question, and right now it’s being handled like a procurement one.
Match the model to the mission
The instinct to default to the biggest, most capable frontier model for every task is the assumption worth retiring. IDC tracked 66 open language models released in 2024 alone, with 34 more in the second quarter of 2025, and the release pace hasn’t slowed. A meaningful share of that growth is smaller, domain-tuned, and regionally optimized models built to do one job well.
That matters directly for a model-selection decision happening this quarter. Model choice should follow the use case. A smaller or domain-specific model, sometimes a regional one, frequently wins on cost and fit for a given task, where a general-purpose frontier model pays for breadth the task never uses. The best model for the job is rarely the biggest one.
Who owns the growing model roster
That accountability question is getting harder to answer, because the roster it’s about keeps growing. Enterprises are entering what IDC calls a multimodel, multimodal, multiagent era, one that needs evaluation, architecture, and orchestration competencies that didn’t need to exist two years ago. A dedicated GenAI evaluation category has caught up fast enough that IDC’s 2025 MarketScape already assessed 13 vendors in it, a category that barely existed the year before.
That governance work doesn’t end once a model is approved. Approval isn’t the finish line. The evaluation category emerged specifically because the portfolio keeps changing after signature, and testing has to run alongside it, not just at procurement. Your engineering team can track any one model closely. The portfolio as a whole is the harder watch, and right now it’s nobody’s job specifically.
The organizational response to that growth is a named owner. IDC is tracking a new role, the Chief AI Officer, with a formal strategic mandate most org charts didn’t carry two years ago. The role exists specifically to own decisions that used to default to whichever engineering team shipped first. Enterprises without that named owner are accumulating sprawl and data debt, plus the integration risk that comes with both, none of it budgeted for.
Expect this to formalize rather than stay ad hoc: model-selection governance tied to use case, cost, and compliance, continued funding for evaluation tooling as its own budget line, and the Chief AI Officer, or an equivalent, picking up ecosystem-level decisions no single engineering team can make alone. None of that requires waiting for the title to exist on your org chart first.
Three questions worth asking this quarter
None of this sits apart from the governance questions already landing on the CFO’s and CISO’s desks. Choosing a model is no longer a one-time technical decision made at kickoff. It’s now tied to what it costs and who’s accountable for it, the same fight already playing out over AI budget ownership and agent audit trails elsewhere in the organization.
Whether or not the Chief AI Officer title exists yet in your org chart, three questions are worth asking now:
Who owns the model portfolio today, by name?
What’s the plan when a model your team depends on gets deprecated mid-cycle?
Is your evaluation process a one-time procurement gate, or an ongoing discipline?
You don’t choose a model anymore. You govern a constellation. That starts with naming an owner this quarter, before the next model gets added to the roster without one.
Curious how your model portfolio compares heading into the new year? Check out IDC Quanta for an independent, vendor-neutral read on where your approach stands relative to the market.
Ryan Smith - Content Marketing Director - IDC
Ryan Smith is the Director of Content Marketing at IDC, where he leads brand-level content and social media strategy, aligning research insights with compelling storytelling to engage technology decision-makers. With a background in both IT and marketing, Ryan brings a unique blend of technical understanding and creative strategy to his work. He’s also a seasoned storyteller, speaker, and podcast host who believes the right message, told the right way, can drive both trust and transformation.
Christina Cardoza - Content Marketing Manager - IDC
Christina Cardoza is a Content Marketing Manager at IDC, where she specializes in brand content and social media strategy. With a background in journalism and editorial leadership, she has a proven ability to transform complex technology topics into clear, actionable insights.
2026 年,随着生成式 AI 与企业核心系统的持续化融合,中国企业资源管理(Enterprise Resource Management,ERM)领域的 AI Agent 正从通用问答和单点辅助,走向核心业务流程的深度嵌入。市场竞争也从技术功能展示,转向可落地、可复用的完整业务闭环。对于财务、采购、人力等关键场景,企业关注的不再只是模型能否给出答案,而是智能体能否理解业务、调用服务、完成任务,并在权限与规则约束下持续创造经营价值。
近日,国际数据公司(IDC)发布《IDC MarketScape:中国企业资源管理市场 AI Agent 2026 年厂商评估》(Doc# CHC54441226,2026 年 9 月)研究报告。报告基于厂商调研与访谈、公开信息以及最终用户体验,从能力与战略两个维度展开综合评估,帮助技术提供者明确产品升级与交付重点,也为企业用户更新 AI Agent 选型标准、推进业务场景落地提供参考。 如需了解更多评估结果,可参考所发布的报告。
财务、采购、人力等低容错率场景,决定了 AI Agent 不能仅以单轮问答准确率衡量。报告显示,相关厂商正在采用业务程序与大模型配合的执行方式:确定性计算和关键校验交由传统程序或规则引擎完成,大模型主要承担意图识别、任务规划、流程编排和结果解读。配合原始单据溯源、置信度阈值、规则抽检与回归测试,可以降低模型幻觉与随机性对核心业务的影响。对异常和高风险动作,应通过人工确认、阻断或回滚机制控制风险。
Wenting Xu, senior research manager with IDC China's Enterprise Application Research, focuses on research and analysis of the China enterprise system and software area. She provides intelligence and consulting services for local and multinational corporation IT vendors. Wenting has developed a deep…
For the past few years, Meta Connect has been at the center of ongoing debates: is the Metaverse dead? Are AI glasses the next big thing? Will Zuckerberg’s latest bet pay off? This year answered a bit of all three. But the biggest news wasn’t one flashy new product. It was how many products Meta is now selling, at how many prices, in how many countries.
The VR glasses gamble
The headline reveal was Meta VR Glasses, Meta’s first real pair of VR glasses instead of a bulky headset. They weigh about 100 grams, five times lighter than a Quest 3, because the compute is separated from the headset into a puck that’s carried in the pocket rather than sitting on your face. They have a 5K screen, full color see-through video, support for Dolby Vision and Atmos, and about three hours of battery life. They launch in spring 2027 and cost $1,299.
That price says it all. This thing is priced like a PC, and it’s really part PC, part game console, part movie theater, which is exactly how Meta is pitching it. But the real point isn’t the spec sheet. Its standalone nature and high-fidelity experience give Meta its own platform, one that doesn’t need Apple, Google, or Microsoft. This is a product for consumers who are already sold on the category or enterprises looking to pilot VR, not the mass market that Meta is chasing with everything else it announced this week.
The pricing move matters as much as the platform argument. Meta has spent three headset generations racing to the bottom on price, so a device costing roughly four times as much as a base Quest is a deliberate step up-market, not a discount play. The data shows why the timing works in Meta’s favor: shipments of this passthrough-VR category, the group Quest and Vision Pro both sit in, peaked in 2024, then fell 44% in 2025 and a further 27% this year.
IDC already had the category turning in 2027, growing roughly 41% that year, so Meta VR Glasses is stepping into a recovery already built into the forecast, not one it’s creating from scratch.
That timing matters because Meta’s Quest-based headsets have taken the majority of this category’s unit sales every year since 2024, against under 7% for Apple’s visionOS, even though Apple’s average selling price runs above $3,000 against something that’s well below $1,000 for Android-based devices. Meta doesn’t need this device to win share it doesn’t have. It needs a flagship on shelves as the turn towards recovery arrives next year.
Filling out the price ladder
That mass-market push showed up everywhere else at the event as Meta launched multiple pairs of glasses and aims to have 100 designs available to consumers by the end of the year. First up is the Ray-Ban Meta Gen 3, starting at $449, with a 12MP camera, 3K video, nine hours of battery, and additional microphones compared to the previous gen that cut background noise by 90%. Below that is a new option: Ray-Ban Meta Audio, starting at $349. No camera, just an AI assistant, music, and calls, with 12 hours of battery. This is the pair of glasses that has a broader appeal due to its price point and sidesteps privacy concerns faced by Meta’s other glasses that are equipped with cameras. The reduction in price and the absence of the camera will likely help Meta find new users who are currently on the fence when it comes to buying smart glasses. However, the absence of the camera is also potentially cutting the product off at its knees, as many consumers buy smart glasses for the video/photo capabilities, and longer term, it also means missing out on multimodal AI capabilities that are enabled by an onboard camera.
These two products are sold in conjunction with Meta’s own glasses, no Ray-Ban name attached, which start at $249. Beyond these glasses, Meta also sells a special edition with Kylie Jenner and announced a new version with Blackpink’s Lisa. For the uncultured (like myself), these are big-name celebrity endorsements which help the glasses maker capture a fashion-forward and potentially younger audience. Meta now sells glasses from $249 all the way to $1,299. That’s a big change from having just one flagship product, unlike other brands. This puts Meta in a very strong position against the competition, letting it compare feature sets and prices across a wide audience.
Display glasses finally go global
The other big piece of news was regarding availability of the Ray-Ban Meta Display, the $799 pair with a built-in screen. These glasses are finally launching outside the US, in the UK, Canada, and parts of Europe this month. I posted about this on X when it broke: based on IDC’s findings, demand in the US has been so strong that Meta has struggled to keep enough in stock over the past year. Getting these to other countries matters for more than just people like me in Canada who want to try a pair. It shows Meta has finally fixed its supply chain enough to sell beyond its home market.
Muse expands its reach
Meta also gave more stage time to Muse, its AI assistant. Muse is getting a smarter model and new connections to other apps, and it’s moving onto the Ray-Ban Meta glasses themselves so it’s available all day, not just when you open an app. Meta also showed off Muse Charm, a small pendant gadget with a screen, speakers, mics, and a fingerprint sensor, meant to carry a “real-time voice and avatar” version of Muse with you. There’s not much detail yet, and more is coming later this year, but it’s clearly meant to tie the glasses lineup together with Meta’s bigger AI plans.
Putting Muse directly onto the glasses, rather than leaving it as something you open on a phone, is the more consequential move of the two AI announcements this week. A phone-based assistant only helps once you’ve stopped what you’re doing and pulled the phone out. An assistant built into glasses you’re already wearing can listen, watch, and help without any of that friction, translating a conversation or setting a reminder without a single tap. That shift, from an app you visit to an assistant that’s simply there, is what turns smart glasses from a nice camera into something people rely on daily, and gives them a reason to stay with one brand rather than treat glasses as a one-off gadget. Still, one of the challenges Muse faces is being confined to its glasses and keychain charm; Apple and Google have enabled their own AI assistants across multiple devices, including glasses, headsets, smartphones, PCs, and tablets. In those cases, Muse will likely be available as an application instead of part of the AI layer built into the operating system.
For now, IDC has this smart glasses category growing from around 13 million units this year to 25 million by 2030, a market worth roughly $7.5 billion, growing faster in units than in value as prices ease with scale.
That’s the business worth watching: it’s an order of magnitude larger in near-term units than the VR headset category, and Muse is the feature meant to make people stay in it.
What the IDC data says
Meta owned 68.7% of the XR glasses/headset market in 2026Q2. Nobody else is close. The bigger story is in the mix underneath that number. Display glasses like the Ray-Ban Meta Display grew to 14.3% of shipments, up from 11%. Headsets captured 15.4% and thin/light glasses with (or without) cameras represented the largest share at 70.3%. The market is clearly moving toward light, cheap, everyday glasses, which is exactly what Meta spent this event building out. Pricier headsets such as Meta’s VR glasses represent a small but dedicated audience despite the technological marvel that they are.
The bottom line is that Meta’s dominant position and Zuckerberg’s willingness to continuously invest in this category is likely to keep them in the lead despite upcoming products from competitors. By filling out the price ladder, Meta is ensuring that consumers of all sorts, and more importantly developers, continue to create or port their best XR experiences on Meta’s devices. And Meta’s Muse AI is trying to do something similar by offering extremely low-cost (free to start) access to end users for a highly capable AI agent.
Call it a real opportunity, but a defensive one. Meta isn’t trying to take a headset market it doesn’t already have; it’s defending one it already dominates, before lighter AR glasses from Snap, Google, XREAL, and eventually Apple make the whole idea of a headset feel dated. The smart glasses side of the business, priced from $249 to $449 and growing on units far faster than on value, is where Meta is actually playing to win.
Jitesh Ubrani - Director, Consumer Devices Research
Jitesh Ubrani is a Director at IDC leading a team of analysts within the Worldwide Consumer Device Trackers group, covering wearables, augmented reality (AR), virtual reality (VR), tablets, phones, PCs, gaming, and smart home devices, with a focus on market…
IDC Environmental Policy
International Data Group is committed to protecting the environment, the health and safety of our employees, and the community in which we conduct our business. It is our policy to seek continual improvement throughout our business operations to lessen our impact on the local and global environment. We are committed to environmental excellence, pollution prevention and to purchasing products that reduce the use of natural resources.
We fulfill this mission by a commitment to:
Encouraging all partners to share in our mission
Understanding environmental issues and sharing information with our partners
Recognizing that fiscal responsibility is essential to our environmental future
Instilling environmental responsibility as a corporate value
Developing innovative and flexible solutions to bring about change
Using our platforms and position in the IT industry to promote sustainability
Minimize air travel to help reduce our impact on the environment
Minimize use of materials and energy consumption in our offices
Create a working environment that efficiently uses our office space
Develop and maintain a hybrid working model that benefits both our employees and business partners
Encourage employees to measure, minimize and collaborate on reducing energy consumption at home and in the office
Engaging employees and promoting active participation in environmental and sustainability initiatives
Leaving?
You are about to leave this section. Do you wish to continue?