A few months ago, I sat with a client who had eight weeks until contract renewal. He knew the pricing was wrong and had a rough sense of what he was overpaying, but he did not have the data to prove it, and his supplier knew it.

We got him most of the way there in time, but I would not want to do that again.

Ninety days is not long, especially when you consider that most managed service deals run three to five years. But it is enough, if you start at 90 days rather than eight weeks. This article is a practical framework for how to use that time, and it builds on the previous two in this series: The first on building a cost-enriched CMDB as a foundation for commercial control, and the second on what AI is actually doing to MSP delivery costs at renewal.

The clock is already running

Your MSP has been preparing for this renewal for months. They know the contract end date, the margin they want to protect, and what it would cost you to switch. Their account team has a position. In most cases, yours does not.

Ninety days gives you time to build a real position. Wait until 60 or less, and you’re negotiating on their clock, not yours.

Three years ago, this was a simpler conversation. Now AI is running across your MSP’s delivery operations, automating service desks, monitoring infrastructure, and managing incidents before they escalate. Their costs are falling. Those savings rarely show up in what you pay. Knowing that, and being able to prove it, is worth more than almost anything else you bring to renewal.

Days 1 to 30: Start with what you know

Start internally, before you look at anything external. You cannot compare your contract against the market without first knowing what you are consuming and what you are being charged for it.

A cost-enriched configuration management database, one that is accurate, continuously updated, and linked to actual consumption, lets you cross-reference MSP billing against real usage. Most organizations find the gap is larger than expected. The consumption audit almost always delivers more savings than the price negotiation. The €48,000 I described in my first article came entirely from removing unused infrastructure before any rate conversation had started.

Pull the rate card history, the last 12 months of true-up invoices, and the actual consumption volume reports by tower. These three documents will tell you more about where you actually stand than any conversation with your account manager.

Break the contract into service towers: e.g., Workplace, Service Desk, Server, Storage, Cloud Operations, Network, Security, SIAM (Service Integration and Management). For each one, record the unit pricing. Cost per device, cost per user, cost per ticket. Without this, any external comparison is matching your actual costs against someone else’s estimates.

Days 31 to 60: Find out what the market actually charges

Your finance and procurement teams almost certainly do not have live pricing data across multiple service towers and geographies. Your MSP does. That gap only closes one way.

I’ve seen buyers spend the full 90 days polishing the internal audit and never get to this step. That’s a mistake too. The audit tells you what you’re paying. It doesn’t tell you what you should be paying.

An independent benchmarking advisor like IDC, who works across many similar engagements, has that data. The benchmark needs to be honest and accurate, using peer contract pricing from contracts signed in the last 12-18 months. A large multinational contract prices differently from a regional one, even for identical services. Scale, geography, scope, and contract length all matter. Any comparison that skips those variables is not a benchmark. You have a guess dressed up as one.

Where is AI showing up in the price? Most buyers have not asked. Across Service Desk, incident monitoring, and routine infrastructure management, it is driving down MSP delivery costs. The service desk is almost always the most negotiable tower, and it is also where AI has the greatest impact on delivery costs. Your MSP is not likely to point that overlap out to you.

Days 61 to 90: Build the case

Not every finding is worth pursuing. Focus on the towers where your price is furthest above market and your spend is highest. A 20% gap on a small tower matters far less than a 10% gap on your largest.

Evidence moves suppliers. A vague ask for a better rate does not.

A concise summary of where your pricing sits against the market, supported by independent benchmarking data, opens a different kind of conversation. And while you have that conversation, push on contract structure too.

When AI agents handle the delivery, pricing per input, per ticket, or per device starts to misrepresent both the cost and the value of what you are buying. Outcome-based models price on what the service actually delivers: resolution rates, uptime, incident reduction. Renewal is the right time to push for this on at least one or two towers. But define the outcomes carefully. A poorly written outcome-based clause can end up working in the MSP’s favor just as easily as yours.

Your MSP arrived ready. Did you?

Your MSP has a position, prepared in advance, supported by data, and reviewed by their account team. Most buyers arrive with goodwill and a vague expectation that a long-standing relationship will deliver a fair price, but it often does not. The clients that consistently walk away with fair contracts have two things most buyers don’t: an independent market price benchmark, and a consumption audit that’s actually current. Everything else in this article, the AI economics, the outcome-based pricing, the tower-by-tower comparison, only works once those two are in place.

Ninety days is not a strategy. It is the minimum. Start before your MSP has already decided what you are going to pay.
Tom Collins - Senior Consultant, Global IT Sourcing & Benchmarking Practice - IDC

Tom Collins is a Senior Consultant in IDC's Global IT Sourcing and Benchmarking practice, advising organizations on IT cost management, sourcing strategy, and technology procurement.

生成AIへの投資は、国内市場でも急速に広がっています。IDCの「Worldwide AI and Generative AI Spending Guide 2026V1(2026年2月発行)」によれば、国内の生成AI市場は2025年の約4,745億円から2029年には約3兆2,739億円へと、4年間で約6.9倍、年平均(CAGR)約62%のペースで急拡大する見通しです。そして生成AIが成熟するにつれて、その使われ方も変わっていきます。汎用的なチャット用途にとどまらず、業務の一つひとつの場面に合わせて個別に最適化され、現場に溶け込む形で活用されるようになります。

用途が広がるなかで、生成AIをパブリッククラウドではなく、自社が管理する環境で動かす——いわゆる「プライベートAI」で運用するケースも増加し、生成AIの市場においても無視できない領域となることが強く見込まれます。

なぜプライベートAIなのか? 企業が「コントロール」を選ぶ5つの理由

というのも、プライベートAIには、パブリッククラウド上の生成AIにはない強みがあるからです。すなわち、

  • 機密性:競争力の源泉であるデータを社外に出さずに済むこと
  • データソブリン:データの所在地が自社の管理下にあるためコンプライアンス対応が容易であること
  • カスタマイズ性:自社のデータに深く最適化できること
  • 規制適合性:AIの運用が業種ごとの規制に対応しやすいこと
  • コストコントロール:運用量やトークン量の爆発的増大によって懸念されるコストを自らコントロールしやすいこと

などが挙げられます。本稿では、この「プライベートAI」がなぜいま注目されるのかをIDCのデータを基に解説し、そして国内市場にどのような機会を生むのかを紐解いていきます。

ユーザーのIT支出が向かう先:産業・ユースケース別市場機会

IDCは、生成AIによる価値創出が、汎用的なアシスタント用途から、各業界固有のデータDNAに深く根差した業界特化型ユースケースへとシフトしていくと見ています。共通するテーマは、単なる補助にとどまらず自律的に行動するAIエージェントが、業界固有のデータと密接に統合されることで、単純な効率化を大きく超える価値を生み出すという点です。そこで、産業別のユースケースの今後について展望してみましょう。

製造業:設計図が経営リスクになるとき

製造業は、設計図・製造プロセス・規制対応情報といった膨大な非構造化データの宝庫です。たとえば、3D設計から部品表作成、サプライヤー交渉、発注までを複数のAIエージェントが連携実行する「設計・調達の自律ワークフロー」は3D設計、部品表(BOM)作成、サプライヤーとの交渉、発注を連鎖的に処理することで、リードタイムの劇的な短縮につながります。さらに、競争力の源泉である設計データは、社外のネットワークに乗せること自体がリスクとなり得ます。また、生産工程で得られる各種データも、内容によってはレイテンシの観点からは遠くのAIデータセンターでの処理では間に合わないケースが多く存在し、この点だけでもパブリッククラウドについてマイナスの評価を下さざるを得ない理由となります。

金融・保険:ハルシネーションが許されない領域

金融・保険は、業務の性格上正確性が絶対条件として要求されるうえ、厳格な規制下で正確性が問われるにもかかわらず、汎用AIではハルシネーション等の懸念が払拭しきれない領域です。実際、取引・市場・ニュースを並列監視する複数のエージェント群がリスクを即時に遮断するリアルタイム不正検知、AI投資顧問エージェントによる資産運用の高度化など、ユースケースは多岐にわたります。これらはいずれも「最も外に出せないリアルタイムの取引データ」を扱うものであり、プライベートAIの必然性が高い領域です。監視システムでは高い即応性が求められることや、機微な情報を保護するケースも多いのが特徴です。

医療:あらゆる中で最も機微なデータ

医療・ヘルスケアでは、症状・既往歴を対話形式で収集し、診療科の振り分けと緊急度の判定を自律実行するトリアージエージェント、ウェアラブルデバイス・遺伝子・生活習慣データから個別の医療プランを継続的に生成するパーソナル予防医療などが期待されます。いずれも患者の診療情報や遺伝子情報という極めて機微なデータを扱ううえ、医療情報の取り扱いに関する規制も厳格であることから、データを自社の管理下で完結させられるプライベートAIとの親和性は際立って高いと言えます。

政府・公共機関:義務としての主権

官公庁・パブリックセクターでは、行政文書や規定・ガイドラインをRAGで検索・応答させ、業務効率化と住民対応力の強化を狙う動きが目立ちます。『IDC FutureScape: Worldwide Security and Trust 2026 Predictions — Japan Implications』(IDC #JPJ53026425、2025年12月)での2029年までに政府の3分の1がソブリンAIを求めるという予測とも重なり、国内完結を前提とした案件が積み上がっていくものとみられます。また、市場規模は限定的であるものの、データの秘匿性や実運用時のネットワークからの独立性が最高レベルで求められる防衛領域においても、プライベートAIのユースケース拡大が見込まれます。

その他:あらゆる分野で高まるプライベートAIのユースケース

このほか、以下の業種などでもプライベートAIのユースケースが広がると考えられます。すなわち、

  • 物流・輸送:リアルタイムの交通・荷量・天候を統合した配車エージェントによる完全自律ルート最適化や、需要・コスト・人口動態を自律分析して新たな配送モデルを編成するラストワンマイル新サービス
  • 小売・EC:購買体験のパーソナライズや需要予測と連動した自動発注、価格・プロモーション戦略の自律最適化
  • 教育:AIチューターによる個別学習設計や採点・フィードバックの自動化など

などが挙げられ、いずれも産業特化型のユースケースとして立ち上がりつつあります。

これらは扱うデータの機微性・要求される保護レベルに応じてパブリックとの使い分けが進むと見られますが、企業固有のデータを競争力の源泉とする度合いが高まるほど、プライベートAIを選ぶ合理性も増していきます。

いずれにも共通するのは、これらの分野・ユースケースがIDCの言う「産業ユースケース」、すなわち産業の特性に由来する独自データと深く結び付いているという点です。汎用的な生産性向上タスクならパブリックで十分であるとしても、上記のように産業分野それぞれに最適化されたAIが日常業務の現場に展開されてゆく状況にあっては、自社データの利活用が今後のAI導入の決定的要因となると言っても過言ではないでしょう。そして、これは企業・組織が扱うデータについて主体的な権利と行動をとることの上に成立します。このデータへの主体的権利と行動はデータソブリンの確立と言い換えることができます。だからこそ、データソブリンに基づいて行動することが、AIをより業務に即した場面に導入し、成功と成長を実現するための必要条件となってくるのです。

データ主権は単なるコンプライアンスではなく、それ自体が需要を生み出す

そして、このデータソブリンの領域については、具体的業務へのAIの導入という観点から捉えなおすと、国内でのビジネスに強みと豊富な経験を持ち、素早い対応が可能なベンダーに市場機会が期待されることが展望できるでしょう。というのも、データソブリンを要請する理由は業務上の必然性はもちろんのこと、IT主権・運用主権・規制対応・地政学リスクといった、個別のビジネスとは別の力学で動く要素にも由来しており、この点については国内での顧客との長きにわたる関係が経験知として蓄積されていることが大きな意味を持つからです。

そして、IDCでは、2027年までに日本のトップ1000企業の60%がAI主権の確保を追求し、非パブリックのホスティング、オープン技術、地域パートナーを組み合わせると予測しています。『2026年 国内AIテクノロジー利用動向調査』(IDC #JPJ53497126、2026年4月)でも、(データソブリンに立脚する)ソブリンAIを重要課題/検討課題とする企業においては、最大の関心事は「データ所有権の担保」であることが分かっています。また、前述の通り、2029年までに政府の3分の1が機密分野でソブリンAIを求めるとも見ています。このようなことから、ソブリンAIを前提とし、国内完結が要件になる業種・ユースケースという観点からも、業種ごとの知識や規制動向に関して現場に由来する知識とノウハウを多く有する、すなわち国内市場に強みを持つベンダーに市場機会があると言えます。

自社の強みを認識した上でのスコープ設定を

その意味では、自社の強みと弱みを整理し、強みの分野で収益性を高める判断も必要です。しかしながら、不都合な現実から目を背けるわけにはいきません。生成AIのモデルそのものの開発力あるいは性能やGPUの調達力では、現在世界で高いシェアを有しているハイパースケーラーやプラットフォーマーとの正面からの競争は、「規模の戦い」に陥るため、好ましい結果をもたらすとは言えないでしょう。

だからこそ、戦い方を変え、オープンウェイトモデルを土台に据えることも視野に入れ、日本語処理という自国の強みを乗せ、パートナーと共にデータソブリンが最大の価値を発揮する領域を固めることが求められます。また、RAGの構築、日本語特化モデルの実装、国内のビジネスに即したガバナンスやオブザーバビリティの運用、液冷対応のマネージドサービス——これらはいずれも、プライベートAIならではの市場機会であり、ユーザーの個別の現実に沿った価値提供が可能な領域であると言えるでしょう。

当然ながら、ハイパースケーラーやOEMのエコシステムに乗るほど、ベンダーロックインのリスクも高まるという事実=落とし穴もあります。自らの強みを認識して、どのレイヤーを自社で握り、どこは割り切って組むのか。その線引きの巧拙が、そのまま競争優位に直結し、勝者とその他のグループを分ける分岐点となることは言うまでもないでしょう。

規模のパブリッククラウド、鋭さのプライベートAI

プライベートAIは確かに魅力的な市場です。ただし、それは広大なAI市場の一部でしかないことを意識する必要があり、この市場の成長性とユースケースの拡大のみを見ていると理解を誤りかねません。すなわち、当面の間はパブリックAIが主流であることをわすれてはならないのです。

ここで、生成AI市場の支出が実際にどこで発生しているのか、IDCのWorldwide AI and Generative AI Spending Guideに基づき、その構図を整理しておきましょう。

国内の生成AI支出について、ソフトウェア関連の支出をデプロイ先で分けると、プライベートAIのインフラとして重要なオンプレミス(専有環境を含む)が占める比率は2024年でおよそ27%、残りの約73%はパブリッククラウドです。しかも予測期間の終盤(2029年)に向けて、オンプレミスの比率はむしろ22%へと微減し、パブリッククラウドは78%まで高まります。

もちろん、シェアがすべてではありませんし、オンプレミスの伸びが鈍いわけではありません。推定支出額自体は5年で約27倍という猛烈な成長です。これは成熟化が進むIT市場の中でも桁外れの成長性を持つ分野です。言い換えれば、プライベートAIはパブリッククラウドを追い抜く必要はなく、この成長率で複利的に拡大を続けさえすれば、それ自体で非常に大きく、収益性の期待できる市場となることが見込まれるのです。そして、この高成長を後押しする要因――ソブリンAIの必須要件化、データ所有権要件、規制圧力――は、循環的でも選択的でもなく、構造的なものである。だからこそ、プライベートAIはベンダーがそのシェアのゆえに退けるべきではない重要なセグメントであると言えます

追い風の中、逆風を理解してこその戦略

AIユースケースの適用範囲が拡大し、それに加えて政府や規制産業全体でソブリンAIの必須要件が進みつつあることが、プライベートAIを本格的な規模の市場へと押し上げる真の原動力となっています。そして、この追い風は強く、かつ構造的なものでもあります。しかし同時に、逆風も直視しておく必要もあります。『IDC FutureScape: Worldwide AI-Fueled Business Strategies 2026 Predictions — Japan Implications』(IDC #JPJ53025425、2025年12月)では、2028年までに国内多国籍企業の70%が地域ごとにAIスタックを分割し、統合コストが3倍に膨らむと予測しています。また、メモリの国際的な需給逼迫や、AI対応データセンターのキャパシティ不足も足かせになります。

では、この機会を掴むベンダーと掴めないベンダーを分けるものは何か。それは、次の4つの要素が揃っているかどうかであると考えられます。すなわち、

  • 実戦で鍛えられたソブリンAIの専門知識と運用ノウハウ
  • 包括的なポートフォリオ
  • 新たなパートナーエコシステム
  • AIをパイロットから本番運用へと導く、実効性のある本番実装を支える変革支援力

この4つをプライベートAIの市場で兼ね備えたベンダーが、次の成長局面でも成長の果実を手にすることができるでしょう。

これまで見てきたように、プライベートAIの市場では、国内市場に強みを持つベンダーが確信を持って次の一手を打てる立場にあります。残るは、市場全体を展望したうえでどれだけ速く動けるか。特に技術の進化が速いAIの領域において、勝負を決する最大の要素の一つは、この速度であることも忘れてはならないでしょう。

関連する調査やご相談について

より詳細なインサイトや市場動向については、当社アナリストへお気軽にご相談ください。

出典(すべてIDC)

  • 『2026年 国内AIテクノロジー利用動向調査』(IDC #JPJ53497126、2026年4月)
  • 『2026年 国内AIインフラおよびAI向けITインフラサービス市場動向分析:推論が主導する競争軸の転換』(IDC #JPJ54233926、2026年3月)
  • 『2025年 国内クラウド市場 テクノロジー動向分析:エージェンティックAI時代のテクノロジースタック』(IDC #JPJ53018625、2025年10月)
  • 『IDC FutureScape: Worldwide AI and Automation 2026 Predictions — Japan Implications』(IDC #JPJ53019825、2025年12月)
  • 『IDC FutureScape: Worldwide AI-Fueled Business Strategies 2026 Predictions — Japan Implications』(IDC #JPJ53025425、2025年12月)
  • 『IDC FutureScape: Worldwide Security and Trust 2026 Predictions — Japan Implications』(IDC #JPJ53026425、2025年12月)
  • 『2025年 国内ユーザー企業調査:産業分野別デジタルビジネス展開動向と課題』(IDC #JPJ53025825、2025年7月)
  • 『2025年 国内金融IT市場動向調査:「モダナイゼーション」後の金融IT市場の展望』(IDC #JPJ53860825、2025年12月)
  • 『国内AI市場予測、2026年~2030年』(IDC #JPJ53498426、2026年6月)

参考データ(IDC)

  • Worldwide AI and Generative AI Spending Guide(IDC #IDC_P33198)
  • Worldwide Quarterly AI Infrastructure Tracker(IDC #IDC_P37251)

菅原 啓 (Akira Sugawara) - Research Manager, AI and Automation - IDC Japan

一貫してテック系リサーチ業界を歩み、20年以上にわたり技術動向からブランド分析まで幅広い領域をカバー。実務と調査の両面に基づく知見を強みとする。 2016年から2021年までIDC Japanに在籍し、スマートフォンやAR/VRなどのクライアントデバイス分野を担当。業界内におけるIDCのプレゼンス向上に貢献するとともに、新聞や雑誌など外部メディアへ市場データを提供。2021年から2025年にかけては日系大手ITベンダーにてマーケットインテリジェンス業務を主導し、AIや量子コンピューティングといった先進分野を中心に、ITサービス市場データの整備、新規プロダクトの市場性予測、競争・市場分析を行った。 2025年からは再びIDC JapanにてAI(生成AIを含む)および関連技術、およびそれらを活用したソリューションの市場動向を、ベンダーとユーザー双方の視点から分析を担当している。 【専門の分野/テーマ】 AI全般 ITサービス DX

2026年7月16日,2026世界人工智能大会暨人工智能全球治理高级别会议开幕前夕,来自29个国家的代表在上海签署《关于成立世界人工智能合作组织的协定》,成为该组织的创始成员国。协定明确,世界人工智能合作组织是独立的政府间国际组织,总部设在上海。

7月17日,大会发布了《2026世界人工智能大会暨人工智能全球治理高级别会议主席声明》《人工智能合作发展行动计划》和《国际人工智能伦理治理行动计划》。

距离2025年WAIC发布《人工智能全球治理行动计划》并倡议成立世界人工智能合作组织,仅短短一年时间,人工智能全球治理便已落地到组织建设、能力合作、标准协调和运行机制等具体层面。

Agent治理决定企业能够开放多少业务权限

Agent治理已经进入企业风险和投资决策。IDC在2025年10月发布的全球预测中提到,到2030年,多达20%的G1000组织可能因AI Agent控制与治理不足引发高影响力业务事故或中断,面临诉讼、巨额罚款和CIO被解职。IDC最新全球调研数据也显示,全球企业计划中的AI投资平均有16.7%用于AI及Agent安全与治理,投入比例已经接近AI技术栈中的其他主要部分(Future Enterprise Resiliency and Spending Survey, Wave 10)。

这些治理要求并非是对Agent的限制,而是真正决定Agent是否能够深入的业务流程的前提。

  • 身份与授权不清晰,企业就难以将核心系统开放给Agent;
  • 缺少链路观测和行为日志,企业就无法还原Agent的判断与执行过程;
  • 缺少流程暂停、任务回退和人工接管机制,企业也难以在Agent出现异常时控制其连锁影响。

只有当Agent的身份、权限、行动过程和异常处置都处于可验证、可追溯、可控的范围内,企业才可能放心地让它进入核心业务,读取真实数据并执行具体操作。

全球AI经济需要共同的信任基础

Agent开展跨组织、跨平台协作时,企业内部的治理机制还要与外部规则连接。身份标识和协作互认帮助不同主体识别彼此,接口协议负责建立连接,语义与流程兼容支持任务理解和协同,行为验证与追溯则为信任和责任提供依据。

一个Agent要接入另一套系统,需要确认其身份、授权来源、能力范围和风险等级。系统还要判断它能否读取某类数据、调用某个工具、修改某项状态,以及哪些操作必须等待人工确认。

不同的身份体系、协议和评测标准会增加Agent经济的交易成本。如果每个平台都使用独立的身份体系、协议和评测方法,跨平台协作就需要反复进行技术适配、安全验证和风险评估。共同的Agent身份标识、安全基线和互操作协议可以减少重复工作,降低不同组织之间Agent交互的成本。

全球Agent经济要实现规模化运行,各方需要围绕Agent身份认证、安全基线和互操作规则形成基本共识,并建立相对统一的标准。在此基础上,Agent才能跨越平台、组织和市场执行任务,不同组织也才愿意开放数据、工具和业务能力,让Agent之间的协作形成可验证、可复制、可持续的生产与交易关系。

全球AI经济需要共同的信任基础

全球治理提出的身份互认、行为追溯和风险分级,最终会体现在企业Agent的系统建设和任务执行中。

  • 身份互认进入企业,会形成Agent账号、授权主体和凭证管理机制;
  • 行为可追溯进入业务流程,会形成任务日志、工具调用记录和责任归属;
  • 风险分类分级则决定Agent可以访问哪些数据、执行哪些操作,以及哪些节点需要人工确认。

以一份企业报价为例,Agent需要读取客户信息、产品配置、库存情况和折扣规则,还要识别销售人员的权限、判断报价是否超过审批额度,并把结果写回业务系统。如果客户信息涉及敏感数据,系统需要限制读取范围;如果折扣超过阈值,任务需要转入人工审批;如果写回失败,Agent还要保存当前状态,避免重复提交或生成两份相互冲突的报价。

这样的治理需求也会逐渐改变企业评估Agent的方法,未来企业除了关注Agent完成任务的成本和准确率,还需要重点关注Agent能否遵守权限约束,能否在任务执行失败时可控回退,以及能否在关键节点及时转交人工审查。


WAIC 2026全球治理议程关注的一个核心问题,是如何管理能够代表人和组织执行任务的AI。AI 及Agent 应用能进入多深的业务流程,取决于治理能力能否跟上。企业内部的身份、权限和行为记录,平台之间的互操作与验证,国家之间的规则协调与能力建设,共同构成AI经济的信任基础。规则越清楚,企业越有可能向Agent开放真实数据、业务工具和核心流程;共同基线和互认机制越完善,Agent跨组织、跨平台和跨市场协作的成本也会越低。治理既约束风险,也为AI能力的大规模应用提供通行条件。

给企业和技术厂商的行动倡议

1. 为Agent建立独立身份与账号

Agent身份需要明确授权主体、数据范围、工具权限和人工确认节点。不同风险等级的任务需要配置不同的执行边界。低风险操作可以自动完成,涉及敏感数据、资金、合同和生产状态的操作,应保留审批、暂停和人工接管机制。

2. 让Agent的执行过程可观测、可回退、可追溯

企业需要记录Agent的任务输入、数据读取、工具调用、业务状态修改和人工介入,形成完整的行动链路。

出现异常时,系统应能暂停任务、保存当前状态、回退相关操作,并定位异常发生的环节及其影响范围。

3. 用可验证的评测说明Agent的能力边界

技术厂商需要说明Agent在不同权限、异常和跨系统环境中的表现。除了任务成功率,还应提供越权拦截、失败恢复、人工介入逻辑和风险控制机制等评测结果,便于企业判断Agent适合进入哪些业务流程,以及可以获得多大的权限范围。

4. 为Agent跨系统、跨组织协作做好准备

Agent连接外部平台时,应能够提供可验证的身份、授权来源、能力范围和任务目的。企业也需要根据Agent的身份、授权来源和风险等级,明确可以向其开放哪些数据和工具、授权持续多长时间,以及哪些操作需要再次确认。

技术厂商则需要支持身份凭证传递、权限委托与撤销、标准化能力描述和互操作协议,让不同平台上的Agent能够在清楚的授权边界内协作。

进一步交流

如果您希望了解人工智能相关的研究或开展进一步交流,欢迎点击这里与我们联系!

Zhenya Sun - Research Manager - IDC

Zhenya Sun is a research manager for the IDC team focused on exploring the application of technology and industrial development of AI and AI agents. He is also responsible for providing clients with consulting services on technologies, products, and markets related to large language models (LLMs) and AI agents, as well as delivering speeches at industry conferences and internal seminars. Before joining IDC, Zhenya served as a project management officer (PMO), responsible for internal and external strategic consulting, AI application research and advisory services, AI project framework standardization, management system construction, and technical training on AI applications. Prior to that, he also led initiatives in product development process optimization and user market analysis. Zhenya holds a Master's Degree in Engineering Management with a specialization in Information Systems Engineering from the University of the Chinese Academy of Sciences.

This is the final post in Meet IDC Quanta, a short series showing what the product actually does, starting with the portal, then your inbox, and now when you’re already working in Claude.


Imagine you’re the account executive on a procurement software deal, and leadership on the buyer’s side just reached out: they want twenty minutes before the broader vendor review starts. Real conversation. No marketing slide deck, no long product tour. They’ll expect you to know their IT spending trajectory, where the competitive field is moving, and why now is the moment to act.

A fast reply won’t cut it here. You need an actual plan, reports pulled, trackers cross-referenced, findings stitched together. You could do that by hand, or you could open the AI tool sitting in front of you and ask it to build the whole thing.

One tool, every surface you’re already in

Most people assume IDC Quanta is a portal you visit. It’s actually a fabric: the same IDC intelligence, methodology, and research base, running everywhere you work. That’s Claude Chat, Cowork, and Code. It’s Claude for Chrome and the Microsoft Office add-ins, too. The deepest workflow integration lives in Cowork, which is where both scenarios below happen. One connection, live through Claude’s MCP integration (the open standard that lets Claude connect directly to outside data sources), with an IDC skill built in to handle the jobs sellers and buyers actually run.

You don’t switch tools to get IDC data into your work. You just ask.

Ask for the plan

Open Cowork and type it straight to Claude:

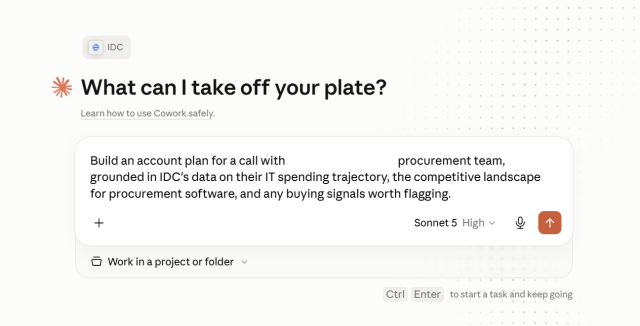
Build an account plan for a call with <your target account’s> procurement team, grounded in IDC’s data on their IT spending trajectory, the competitive landscape for procurement software, and any buying signals worth flagging.

Claude Cowork meets IDC Quanta MCP connector 1

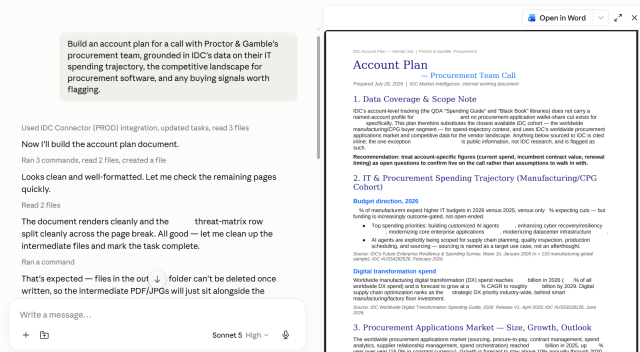
Claude comes back with a couple of quick multiple-choice questions, like which vertical cut or which time horizon. Pick your answers, and it gets to work. A few minutes later, a fully structured account plan is sitting in a Word document. Spending trends are mapped out. Competitive positioning gets a clear read. Buying signals surface where they matter. The kind of document that used to take an analyst half a day now takes the length of your coffee.

Claude Cowork results from IDC Quanta Query

Watch it show its work

Here’s the part that actually matters. Open the document and you’ll notice something most AI tools never bother to do: it tells you which parts came from where. IDC-sourced data sits clearly apart from what Claude reasoned on top of it. Nothing blends together into an unlabeled wall of confident-sounding text.

That distinction is the whole point. When your VP asks where a number came from, you’re not guessing. You can point to the line and say exactly what it is: IDC research, or Claude’s synthesis. The document already told you.

Same intelligence, the other side of the table

Now flip seats. You’re the buyer, evaluating procurement software vendors, and you need an independent shortlist, not a vendor’s pitch deck dressed up as analysis.

Same tool, same Cowork window. Ask Claude:

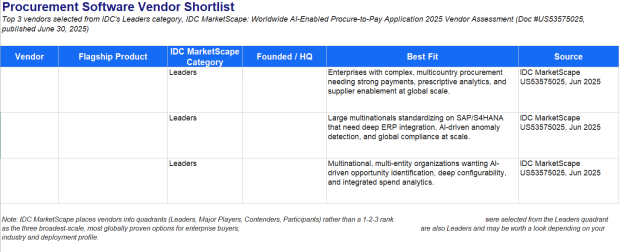
Give me a shortlist of the top three options based on IDC’s worldwide procurement applications research, and generate an Excel evaluation scorecard I can share with my team.

Claude builds the scorecard from the same shortlist of the three vendors actually leading the field, sourced from IDC’s Worldwide Procurement Applications Market Shares, 2025 (IDC #US53723426, June 2026). The IDC-grounded data and Claude’s analysis are labeled separately again. Your team sees exactly what’s evidence and what’s reasoning, no matter which side of the deal they’re sitting on.

Everything You Need, in the Tab You’re Already In

Our first blog showed you a portal built for hard questions with real citations. Our second blog put that same intelligence in your inbox. This closes the series on the biggest move yet: IDC Quanta living inside the tools you use, Claude included, where the work happens. A seller and a buyer can each walk into the same negotiation better prepared, neither one leaving the screen in front of them.

If you’re already using Claude, the IDC Quanta connector is one prompt away. If you’re not yet a customer, book a demo and bring the account you’re working right now.

Ryan Smith - Content Marketing Director - IDC

Ryan Smith is the Director of Content Marketing at IDC, where he leads brand-level content and social media strategy, aligning research insights with compelling storytelling to engage technology decision-makers. With a background in both IT and marketing, Ryan brings a unique blend of technical understanding and creative strategy to his work. He’s also a seasoned storyteller, speaker, and podcast host who believes the right message, told the right way, can drive both trust and transformation.

Governance is no longer an afterthought for agentic AI. According to IDC’s Future Enterprise Resiliency and Spending Survey, Wave 10, enterprises now allocate an average of 16.7% of their total planned AI spending to AI and Agent security and governance, a share on par with investment in other core layers of the AI tech stack. The takeaway for CIOs and vendors: governance has moved from a compliance checkbox to a strategic budget priority.

That institutional shift was visible at WAIC 2026 in Shanghai. On July 16, representatives from 29 countries signed the Agreement on Establishing the World Artificial Intelligence Cooperation Organization and became its founding members. The following day, the conference issued a chair’s statement and two governance action plans, while also proposing a global initiative on trusted Agent connectivity and interoperability. A year after China proposed the creation of WAICO at WAIC 2025, the signing of the agreement represents institutional follow-through worth watching. Its practical impact will depend on how these commitments are translated into common standards, coordination mechanisms and implementation programs.

Why Governance Is the Gatekeeper, Not the Brake

IDC’s October 2025 FutureScape: Worldwide Agentic Artificial Intelligence 2026 Predictions forecasts that by 2030, up to 20% of G1000 organizations will have faced lawsuits, substantial fines, and CIO dismissals due to high-profile disruptions stemming from inadequate controls and governance of AI agents. Far from restricting what Agents can do, governance is what makes deeper integration possible in the first place. Without clear identity and authorization rules, companies won’t grant Agents access to core systems. Without full observability and immutable logs, teams can’t reconstruct what happened after an incident. Without built-in suspension, rollback and human-override controls, businesses can’t contain the damage when an Agent misbehaves. Trust scales with control and not the other way around.

Three Layers of Trust

Enterprise confidence in Agents builds across three interconnected layers:

1. Internal controls — Agent identity, permissions and audit trails

2. Cross-platform interoperability — standardized verification mechanisms

3. Cross-border alignment — regulatory frameworks and capacity-building

As Agents increasingly need to work across organizational and platform boundaries, the second layer matters as much as the first. Shared identity credentials, common connectivity standards, and audit-ready activity trails keep accountability clear even across company lines. Without them, every cross-platform integration means redundant security validation and custom risk assessment — a tax on the whole Agent economy.

Translating Global Governance Rules into Enterprise Agent Design

The three trust layers above aren’t abstract, they dictate real architecture choices. Identity and permissions become credential and account governance. Audit-ready activity trails become tool-invocation logs and accountability records. Risk tiers become access scopes and human-review checkpoints for high-stakes actions — the same logic enterprises already apply to a routine quotation-approval workflow, now extended to Agents.

What This Means for Enterprises and Vendors

This reshapes how enterprises should design and evaluate Agent systems in practice:

  • Assign every Agent a unique identity — with defined authorizing stakeholders and bounded permissions, calibrated to risk. Routine tasks can run autonomously; anything touching sensitive data, capital transactions or production systems needs human-override capability.
  • Build fully observable, rollback-enabled pipelines — with complete audit trails covering every input, tool call and state change.
  • Push vendors for verifiable evaluation results — beyond task completion rates, including how well an Agent respects privilege boundaries, recovers from failure and escalates to humans.
  • Architect for cross-organization collaboration — Agents should present verifiable credentials, and receiving platforms should enforce granular, risk-based access policies.

Need to know how AI governance will impact your business? Explore the latest research, AI Governance: The Trust Layer — Governance Is Not Glamorous, But It Is About AI Trust and 中国智能体开发平台市场份额, 2025 to learn more. Fill out this form to Contact Us.

This blog is an extract of the original blog WAIC2026现场观察| 聚焦可行动AI,探索适配产业的治理规范 by Zhenya Sun, published in WeChat.

Zhenya Sun - Research Manager - IDC

Zhenya Sun is a research manager for the IDC team focused on exploring the application of technology and industrial development of AI and AI agents. He is also responsible for providing clients with consulting services on technologies, products, and markets related to large language models (LLMs) and AI agents, as well as delivering speeches at industry conferences and internal seminars. Before joining IDC, Zhenya served as a project management officer (PMO), responsible for internal and external strategic consulting, AI application research and advisory services, AI project framework standardization, management system construction, and technical training on AI applications. Prior to that, he also led initiatives in product development process optimization and user market analysis. Zhenya holds a Master's Degree in Engineering Management with a specialization in Information Systems Engineering from the University of the Chinese Academy of Sciences.

Moonshot AI’s release of Kimi K3 has intensified the debate over open models and frontier AI regulation, prompting renewed scrutiny of reported requests by OpenAI and Anthropic for the U.S. government to restrict open model releases associated with unauthorized distillation. The possibility that the U.S. government might restrict or ban such models catalyzed a forceful industry response. A coalition that included NVIDIA, Microsoft, Meta, IBM, Dell Technologies, Palantir, Hugging Face, Mistral, Mozilla, and other technology companies signed a letter urging policymakers to avoid premature restrictions on open-weight models and to distinguish legitimate distillation from misappropriation. The decision about whether to ban open models such as Kimi K3 will determine whether advanced AI development remains concentrated within a small number of laboratories or becomes accessible to a broader ecosystem of builders.

The larger opportunity is to create a future in which AI capability becomes bountiful, cheap, multivalent, and heterogeneous. That future depends on broadening participation beyond a small number of frontier laboratories and giving more organizations the means to develop intelligence on their own terms. Open weights provide the foundation, but open post-training infrastructure provides the path from access to invention. Restrictions on open releases would preserve scarcity just as the technical foundations for a broader and more generative ecosystem are beginning to emerge.

Restrictions on open models would protect incumbents from competition

The requests from OpenAI and Anthropic frame distillation as a problem requiring federal intervention to limit the distribution of models developed by other organizations. Distillation is the practice of using the outputs of a stronger model to train or improve a weaker one. An actor who queries a frontier model extensively across many sessions can use those interactions to produce a second model that approximates some of the original system’s capabilities. That second model then operates outside the original provider’s visibility, access controls, and safety infrastructure. OpenAI and Anthropic contend that unauthorized distillation of their systems constitutes intellectual-property theft and that open models built through that process should be restricted.

Closed-model providers, however, already control access to the systems from which the alleged distillation occurs. They determine who can use their models, how much access users receive, which interfaces are available, what contractual terms apply, and what patterns of automated activity trigger enforcement. Providers that consider distillation a material threat can strengthen authentication, impose rate limits, identify unusual query patterns, suspend accounts, restrict automated extraction, and redesign interfaces that expose unusually valuable training signals. They can also enforce contractual rights against users who violate clearly defined terms of service. The question of why these companies seek regulatory protection for a problem they are positioned to address through their own infrastructure deserves scrutiny.

OpenAI and Anthropic are seeking regulatory intervention as the general-purpose model layer begins to commoditize. Capability gaps between frontier and open models appear to be narrowing across a growing range of workloads, and substituting one system for another is becoming easier for enterprises. Open models give enterprises something to host and adapt on their own terms, and eventually to specialize for tasks a closed provider never built for. A closed provider holds greater pricing authority when few other systems can deliver comparable results. That authority declines when enterprises can choose among several proprietary services or adopt an open model that they can modify and operate on their own infrastructure. Even when an organization never deploys one, an open model exerts competitive pressure: its existence alone gives customers an alternative to permanent dependence on a single provider.

An open model should not be presumed to result from unauthorized distillation simply because it is open. A capable open model may reflect public research, independent experimentation, synthetic data, open datasets, improved training efficiency, or the cumulative work of a broader technical community. Similar model behavior does not by itself prove improper extraction. A policy regime that treats capability similarity as evidence of theft would allow incumbent providers to claim a proprietary interest in broad forms of model behavior and general technical progress. The federal government should not convert the private access-control concerns of closed providers into restrictions on open competition.

Open models preserve competition and the ability to build

Open models give organizations direct access to inspect and adapt AI systems, then run them wherever they choose. When an organization holds model weights, it can evaluate model behavior directly rather than rely on access mediated by a small number of private laboratories. That direct access supports customization, local deployment, reproducibility, independent safety validation, and organizational control over data and governance. Participation in AI development expands when more organizations can build and test systems, then improve them according to their own requirements rather than within boundaries defined by a provider.

No managed service can replicate the forms of control open models provide. Governments and regulated enterprises gain the ability to retain control over deployment conditions, data boundaries, and compliance requirements within the infrastructure they operate. Researchers gain the ability to study model behavior, test safety properties, and publish findings without requiring permission from the system’s developer. Independent developers gain room to pursue technical directions that hold substantial value within a specific domain or community, even when those directions hold little commercial interest for a frontier laboratory. These capabilities depend on holding the weights rather than on accessing a provider’s interface.

A frontier API gives an organization access to capability under conditions defined by the provider: the available model, permitted forms of use, pricing, rate limits, retention policies, safety controls, and the timing of future changes. Open weights transfer a different kind of authority. They allow an organization to inspect the model, operate it within the infrastructure it controls, alter its training process, construct its own evaluations, and pursue development directions the original provider did not anticipate. The distinction is between consuming capability and possessing the means to develop it further. Open models convert consumers of intelligence into builders of it.

Open weights alone are not enough: Post-training must be open too

Post-training is where frontier laboratories establish much of their practical advantage. Without open post-training infrastructure, open weights remain static artifacts. An organization that downloads an open model but lacks the tools, environments, evaluations, and reproducible practices required to post-train it can use the model as released, but cannot reshape what the model can do. In practice, OpenAI, Anthropic, and Google appear to maintain their position less through pretraining scale or model weights than through what comes after: reinforcement learning at scale, tool-use conditioning, failure recovery across multistep workflows, reward modeling, and the accumulated judgment required to turn a base model into a system that executes reliably in production. What separates the frontier laboratories is the full development apparatus surrounding those published methods: the quality of training data, the design of task environments, the precision of evaluations, the construction of reward signals, and the decisions of teams that have run thousands of experiments and learned from each failure.

An open model ecosystem should therefore include more than downloadable checkpoints. It should include the tools, environments, evaluations, and reproducible practices required to conduct meaningful post-training. Without these components, the gap between holding a model and developing specialized capability from it remains prohibitively wide for most organizations. This infrastructure is beginning to take shape.

NVIDIA’s open-source NeMo RL provides scalable reinforcement-learning and post-training infrastructure, while NeMo Gym provides environments that combine datasets, agent harnesses, verifiers, and state for training and evaluation. Hugging Face’s TRL supports supervised fine-tuning, reinforcement learning, preference optimization, and reward modeling. OpenEnv provides standardized execution environments for agentic tasks. Open-R1 contributes shared training scripts, datasets, evaluations, synthetic-data pipelines, and development recipes that other teams can reproduce and adapt. Taken together, these projects show that open post-training is no longer merely an aspiration. Many of its constituent layers now exist, although they have yet to cohere into a broadly adopted and reproducible development stack.

The priority now is to expand the availability of complete post-training projects that connect models, datasets, environments, reward functions, evaluations, and experimental records in reproducible form. Such projects allow other teams to study the development process, replicate its results, and adapt its methods to another model or domain. Open-source software became foundational infrastructure through precisely this kind of cumulative contribution. Open post-training will not make advanced model development effortless. Organizations will still require substantial compute, high-quality data, expert evaluators, domain-specific environments, and the technical judgment to diagnose failed training runs. Its significance is that it can break the closed loop that has concentrated the knowledge required to build advanced AI within a small number of laboratories.

An open model ecosystem allows multiple intelligences to flourish

Open models and open post-training expose a larger truth that the current market structure often obscures: intelligence does not have a single frontier. Frontier models from OpenAI, Anthropic, and Google represent a specific and commercially valuable conception of intelligence that emphasizes coding, mathematical and scientific reasoning, wide knowledge coverage, and flexible performance across many domains. That conception occupies an important place within a broader field of intelligence. The capabilities prioritized by a small number of frontier laboratories should not become the universal standard against which all intelligent performance is measured.

Multiple intelligences are distinct configurations of knowledge, perception, judgment, and practical competence that succeed against different standards of excellence. Scientific intelligence reveals patterns in protein structures or identifies promising paths through a complex field of research. Engineering intelligence reconciles physical constraints, safety requirements, efficiency, and manufacturability. Other forms of intelligence place greater weight on aesthetic judgment, care, cultural fluency, pedagogy, taste, or practical wisdom. Design intelligence creates a home that reflects the memories, needs, and daily rhythms of the people who live there. Cultural intelligence organizes a bookstore display that creates unexpected associations and invites discovery. Developmental intelligence helps a family select media appropriate for a particular child. Practical or relational intelligence shapes a family vacation that balances cost, energy, accessibility, competing interests, and the experiences different people will remember.

Each of these intelligences involves a different combination of factual knowledge, perception, empathy, contextual awareness, technical competence, and judgment. Some forms of intelligence privilege mathematical correctness, scientific validity, or engineering precision. Others privilege beauty, coherence, care, fit, trust, delight, or an understanding of what will work for particular people under particular conditions. A system can excel against one set of standards and remain unremarkable against another, even when it performs strongly on broad benchmarks.

Respect for multiple intelligences remains compatible with rigorous standards of truth, evidence, competence, consistency, and excellence. Different perspectives do not erase the distinction between truth and falsehood. Every form of intelligence must prove itself against standards appropriate to its claims and purposes. Valid intelligence can take different forms, serve different ends, and resist reduction to a single hierarchy defined by general-purpose model performance.

A multivalent AI market would therefore contain many scientific, technical, cultural, commercial, and practical frontiers. General-purpose providers would continue to compete on broad reasoning, reliability, and managed-service quality. Specialized developers, institutions, and communities could build capabilities grounded in domain expertise, aesthetic judgment, cultural knowledge, practical experience, and different conceptions of successful performance. An open model ecosystem gives these forms of intelligence room to emerge, get tested, and prove their value — flourishing or not, on their own terms.

Choosing between scarcity and abundance

As the model layer commoditizes and capability gaps narrow, frontier providers will increasingly differentiate on the operational qualities that enterprises require: predictability, latency, uptime, regional availability, security, and compliance — capped by the kind of managed governance only a well-resourced provider can sustain. These characteristics justify enterprise procurement at scale, and they depend on the capital depth, compute access, and infrastructure investments that frontier laboratories are uniquely positioned to sustain. Open models and multivalent forms of intelligence broaden the market by distributing the ability to develop differentiated capability across a wider set of organizations, while frontier providers compete to deliver reliable, managed, general-purpose systems at enterprise scale. The result is an AI economy with more builders, more forms of intelligence, and more competitive pressure at every level.

The debate over open models is larger than a dispute about distillation or a disagreement about access policy. It concerns whether the ability to develop advanced AI stays scarce and concentrated within a small number of providers, or grows more abundant, cheaper, and responsive to the full range of domains and institutions that need it. Restrictions on open releases would preserve scarcity at the moment when the conditions for abundance are beginning to emerge. Open weights preserve the foundation. Open post-training provides the development path. The policy choices being made now will determine which future prevails.

Arnal Dayaratna

Arnal Dayaratna - Research Vice President, Software Development

Dr. Arnal Dayaratna is Research Vice President, Software Development at IDC. His research focuses on agentic AI, generative AI, foundation models, agentic coding technologies, and low-code and no-code developer technologies. He also examines the broader technology stack around foundation models,…

At the IDC Quanta launch webinar, Joe Bradley, CTO at IDC, made the case for why trusting an AI-powered answer shouldn’t require faith; it should require an architecture you can actually inspect. You’ve heard “AI-powered” enough times this year that a healthy dose of skepticism is the right response. Fair. So instead of asking you to trust that IDC Quanta gets its answers right, here’s what Bradley says is actually happening under the hood when it does.

Bradley breaks it down into two layers. The first is an MCP server: essentially a pipe that gives Claude direct access to IDC’s data, the trackers, the forecasts, the market figures. It also carries instructions for how that data is structured and how to use it. The second is IDC’s own Claude plugin, which goes further, Bradley explains. It shapes how the AI reasons about that data, tells it what’s relevant for what purpose, and requires it to surface a source before handing over any answer. Put together, when someone asks a question, Claude isn’t searching a phrase in a database, Bradley says. It’s reasoning with IDC’s own methodology built into the process.

That’s the theory. Here’s what it looks like in practice.

The Moment It Earned Trust

In the product demo, Bradley walked through a fictional scenario: Marcus Chen, a Senior FP&A analyst at Vantix Security, is building a market forecast ahead of a CFO review. He is projecting 16% growth in a segment his company competes in. He asked IDC Quanta to check that number against an external benchmark, right inside Excel.

In under a minute, Quanta surfaced IDC’s actual forecast for that market: 12.1% growth through 2029, with the category decelerating to single digits in the later years. His model hadn’t caught up to where the market was actually headed. That’s the payoff of the architecture above. The answer arrived with its source attached.

Why Even Build an App

Technical buyers reasonably ask why IDC needs its own app when Claude and ChatGPT already exist. IDC isn’t positioning itself as a competitor to the assistants people already use daily. It’s building something with a narrower job.

The case for IDC Quanta comes down to control over how IDC’s own data gets handled and delivered. It exists because of what only a dedicated app can guarantee: a single place that collects everything relevant across an IDC relationship, a direct line to a live analyst when the automated answer isn’t enough, and data handling built on tenant isolation, enforced access controls, and audit logs that capture every user action. Which raises the next question technical buyers ask first.

Provenance You Can Check Yourself

Bradley’s last test for anyone skeptical of AI-generated answers is provenance. Can you verify where it actually came from? In a second demo, he showed IDC Quanta processing a strategy document sent over email, then breaking its answer down into cited data cuts, each one tied explicitly to the filters and definitions behind it.

Nothing here is asserted without a source attached, and nothing requires trusting the AI’s summary over the underlying data itself. That’s the actual answer to “how do you know it’s not confidently wrong”: you don’t have to take Quanta’s word for it. You can check.

See It Yourself

The architecture, the demo, and the sourcing are easier to evaluate firsthand than to take on faith. Request a demo, or talk to your IDC account team if you already have one.

Ryan Smith - Content Marketing Director - IDC

Ryan Smith is the Director of Content Marketing at IDC, where he leads brand-level content and social media strategy, aligning research insights with compelling storytelling to engage technology decision-makers. With a background in both IT and marketing, Ryan brings a unique blend of technical understanding and creative strategy to his work. He’s also a seasoned storyteller, speaker, and podcast host who believes the right message, told the right way, can drive both trust and transformation.

Every industry conversation about AI right now seems to circle the same warning: it will do most of the routine work, services revenue will compress, and headcount-based business models must change to stay competitive. That warning isn’t wrong. It’s just half the story. It only describes what AI may take away from the market as businesses transform. Almost nobody is talking about what AI is creating at the same time: a large, durable, currently unclaimed demand for the specific skill of checking whether AI did the job correctly.

There’s a 40-year-old piece of research that predicts exactly what’s happening now, from a field that has nothing to do with software. In 1983, cognitive psychologist Lisanne Bainbridge published a short paper called “Ironies of Automation,” based on years of studying industrial process control rooms. Her finding was this: the more comprehensively you automate a system, the more demanding, not less, the remaining human role becomes. Why? Because humans are left holding exactly the tasks nobody could figure out how to automate, plus a brand-new job nobody trained them for: supervising a system whose failure modes they no longer see often enough to recognize. Skills that go unpracticed deteriorate. An experienced operator who spends their days watching automation work, instead of doing the work themselves, quietly becomes an inexperienced operator without ever noticing the transition. The automation is usually right, until the day it isn’t.

Aviation gave this idea real stakes. In 1987, a Northwest Airlines flight crashed on takeoff from Detroit, killing 154 of the 155 people on board. The crew had grown accustomed to an automated system that checked whether the flaps and slats were correctly configured for takeoff. That day, the automated check had been silenced by a tripped circuit breaker. The crew, used to the machine catching that error, didn’t manually verify it themselves. The plane took off unconfigured and didn’t make it. Nothing exotic went wrong that day: just a very ordinary, very human failure to keep practicing a check that automation had quietly made feel unnecessary.

That’s the pattern. And it’s showing up again, right now, in every field that has adopted AI assistants at scale, and people are already living through it. Junior lawyers are offloading legal research and first drafts to AI, the exact repetitions that used to build legal judgment, and firms are openly worried their new hires aren’t developing the ability to evaluate AI output at all. Several 2026 industry surveys on software engineering point to a similar problem from a different angle: junior developers who lack grounding in architecture and security can’t reliably judge whether AI-written code is good, and default to trusting the AI over their own instincts, precisely because they never built the instincts to trust instead. It’s been put more bluntly at industry security events: junior engineers raised on AI-assisted coding increasingly lack basic grounding in networking and protocols, to the point where teams struggle to even explain a security risk internally, let alone catch one.

So, the question people are asking but very few are providing an answer: yes, the mundane, repetitive tasks are going to get automated, that part of the story is true and it’s not really in dispute. But who is going to have the skill to validate what AI produced? Who’s going to be able to look at an autonomous system’s output and know, from real hands-on grounding, whether it’s right? And when something goes wrong, when the AI needs to be stopped, corrected, or restarted mid-task, who still has the muscle memory to do that? Everyone is racing to build automation. Who’s building the capacity to check it?

The cybersecurity version of this problem

Cybersecurity is the sharpest version of this problem right now because the automation in cyber security disciplines isn’t coming, it’s already here, running unsupervised, in production.

Every major SOC platform is moving from “copilot” (AI answers questions, a human acts) to “agentic” (AI acts, a human is notified afterward). Autonomous triage agents are now closing low-risk alerts and triggering containment actions on their own, at high self-reported accuracy, measured, naturally, by the vendor who built the system, against that vendor’s own labeled data. There’s no independent party currently checking that number. And practitioners are visibly split on how much to trust it: it’s now common to hear security teams admit they override AI-generated recommendations rather than act on them, because the output sounds confident even when it’s occasionally wrong. Busy teams get complacent, and AI has been trained on academic papers, so there is inherent bias towards confidence.

The same pattern is playing out on the offensive side. Autonomous AI pentesting agents are now finding, and reporting, real vulnerabilities faster than any human team could. That’s a real achievement. But it has already broken the pipeline downstream of discovery: at least one major bug-bounty platform has paused a long-running program and cut payouts after AI-assisted research pushed submission volume far beyond what maintainers could triage, and multiple open-source projects have suspended their bounty programs entirely over a flood of plausible-sounding, low-quality AI-generated reports. The constraint in offensive security has visibly shifted from finding problems to verifying them, and almost nobody is selling the verification.

This is, very precisely, a validation gap, and cybersecurity doesn’t have a name for it yet. So, let’s give it two.

AVaaS: AI Validation-as-a-Service. It borrows the naming convention security buyers already understand from PTaaS (Pentest-as-a-Service) and MDR (Managed Detection and Response), applied to a category that doesn’t have a name yet. An independent party’s entire job is to check what your AI actually decided against what it claims to have decided. That means sampling autonomous SOC actions against ground truth the AI didn’t design. It means reviewing autonomous pentest findings the way a skeptical senior tester reviews a junior’s report: not just whether it hit the target, but whether the path to get there was sound. This is not an eval, and it is not an LLM-as-judge setup wearing a new name. AVaaS is a human, independent, and accountable check — the specific thing a regulator, a board, or a client needs signed off, and the specific thing an eval was never designed to provide.

AJQ: AI Judgment Quotient. The individual-level version of the same idea: a way of naming the specific, trainable skill of knowing when to trust an AI’s output and when to push back on it, separate from knowing how to prompt an AI well, which is the skill everyone’s currently obsessed with. Prompting gets you a better answer, faster, just like it you ask a human a question. AJQ is what tells you whether the answer is right. Nobody is hiring for it by name yet. That won’t last.

The compliance tailwind almost nobody’s pricing in

There’s a regulatory hook here too, and it’s worth being precise about it, because the generic version of this argument overstates it. Most everyday cybersecurity AI, a SOC copilot triaging phishing, a pentesting agent scanning a SaaS app, isn’t automatically caught by the EU AI Act’s high-risk rules. But one category inside the Act lands directly on cybersecurity: AI systems used as a safety component in the management and operation of critical digital infrastructure: the utilities, OT, and ICS environments where a security or anomaly-detection system’s failure could have physical consequences. Those are high-risk by default, and the Act requires genuine, working human oversight: a person who can monitor, understand, override, and halt the system in practice, with that capability demonstrated rather than assumed.

Regulators aren’t going to be satisfied by a policy that says a kill switch exists. They’re going to ask whether anyone has tried to pull it under pressure and confirmed it works. That’s a specific, testable claim, and one that’s easy to sell. The deadline for it just moved later, to December 2027. That later date buys a multi-year runway to become the obvious, credible, evidenced vendor for this before every advisory firm on earth starts pitching the same slide.

That’s the tangible space. A genuine market category, with no incumbent, built where three things come together, all independently, verifiably true right now: AI is already making unsupervised security decisions in production; the people who could historically catch its mistakes are the same people whose foundational skills are quietly eroding from disuse; and a regulator is about to start asking, in writing, whether anyone actually checked. So, let’s see who builds it first.

Shilpi Handa

Shilpi Handa - Associate Research Director (META), IDC

Shilpi Handa is an associate research director at IDC, with responsibility for the Middle East, Turkey, and Africa cybersecurity practice. Her core research coverage revolves around cybersecurity, with a focus on network security, cloud security, application security, and security operations.…
Shari Lava

Shari Lava - Group Vice-President, AI, Data, and Automation

Shari Lava is Group Vice-President, AI, Data, and Automation, where she leads research on the fast-evolving AI software market and the automation and data foundations that underpin enterprise AI adoption. Her work translates market dynamics and adoption trends into practical…

过去几年,大语言模型和生成式AI率先改变知识处理、内容生产和软件流程。随着多模态模型、世界模型、VLA模型和边缘AI持续发展,AI正在进入车辆、机器人、无人机、工业设备和城市设施,能力范围也从生成内容、调用软件,扩展到感知环境、规划任务和控制设备。

物理AI面对持续变化的真实环境,需要处理设备状态、空间关系、环境变化、物理规律和安全要求。系统既要形成“感知—决策—执行—反馈”的实时运行闭环,也要形成“真实运行—数据回流—模型训练—仿真验证—重新部署”的研发迭代闭环。前一类闭环影响任务能否稳定完成,后一类闭环影响产品能否持续改进并扩大应用范围。

IDC 2026年全球CEO调查显示,35.2%的受访CEO将物理AI列为未来12—24个月重点关注的新技术投资方向。资源行业的比例达到50%,制造和零售均为46%,医疗为38%。当前市场已经进入投入和生产验证并行阶段,企业普遍从任务清晰、数据可获得、收益可衡量的场景切入。

IDC认为,硬件决定系统能否稳定进入现场,软件影响学习速度、验证效率和复制能力,数据闭环负责把应用需求、软件工具和硬件执行连接起来。物理AI未来的差距,会越来越多地体现在运行数据能否沉淀为场景资产、验证用例和模型更新。

数据闭环贯穿三层产业架构

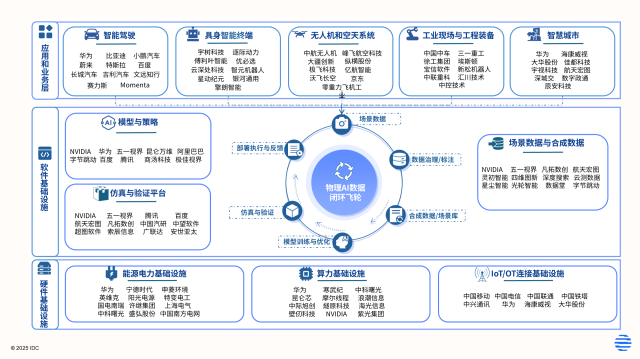
为了更系统地拆解数据闭环如何落地,IDC将中国物理AI产业划分为三层相互咬合的结构。 应用和业务层定义真实任务、运行流程和商业价值;软件基础设施层组织模型与策略、仿真验证和场景数据;硬件基础设施层提供计算、连接、供能、感知和物理执行条件。

三层围绕真实运行形成循环:应用产生任务和现场问题,硬件完成感知与执行,软件把运行数据转化为训练数据、仿真场景和验证用例,更新后的模型再进入设备和业务系统。下面逐层展开,看每一层在闭环中具体承担什么角色、当前进展到哪一步。

应用和业务层:闭环质量影响商业化节奏

任务边界、数据反馈、安全责任和投入产出,是判断场景成熟度的四项重要条件。运行问题能够被记录、复现和验证的场景,更容易进入规模部署。

智能驾驶已经形成较完整的数据采集、场景挖掘、仿真测试和版本回归流程,是当前数据闭环较成熟的物理AI场景。

具身智能终端正在从动作演示进入连续任务执行阶段。任务成功率、人工接管频率、异常恢复能力和跨环境适应能力,将逐步成为主要评价指标。

无人机和空天系统需要把飞行状态、空间环境、通信链路、任务调度、运行监管和异常处置纳入统一的运行与验证体系。

工业现场与工程装备拥有清晰的工艺、安全和成本目标。质量检测、预测维护、物料搬运、巡检、精密操作和无人作业等任务,已经开始产生可量化的效率、质量和安全收益。制造业具备流程明确、数据基础较好和指标体系成熟等条件,将继续成为物理AI的重要验证场。

智慧城市相关应用需要打通感知、分析、调度和执行。AI进入交通、设施、低空和应急等物理系统的实际运行后,才会形成更完整的物理AI能力。

无论哪个场景,应用层产生的海量运行反馈,都需要经由软件层转化为可复用的能力——这正是下一层的核心使命。

软件基础设施层:把运行反馈转化为可复用能力

软件基础设施层包括模型与策略、仿真与验证、场景数据与合成数据。三类能力通过数据闭环持续协同,决定物理AI的进化速度和规模复制能力。

模型与策略方面,世界模型仍处于多条技术路线并行发展阶段,可用于交互环境生成、状态变化预测和行动结果推演;VLA模型连接视觉、语言和动作,为机器人及自主设备生成任务策略。未来系统将更多采用分层架构,由高层模型理解任务与环境,中间层完成预测和规划,底层控制系统负责实时、稳定和安全执行。

仿真与验证方面,数字孪生、空间智能和仿真平台之间的协同正在加强。数字孪生提供设备结构、空间关系、物理参数、工艺规则和实时状态;空间智能帮助模型理解三维环境和对象关系;世界模型扩展场景生成、状态预测和策略探索;仿真平台承担测试、回归和安全验证。虚拟环境由此可以覆盖训练、方案推演、系统测试和运行优化。

场景数据与合成数据方面,物理AI需要的数据已经从单帧图像和单点记录,扩展到包含时间、空间、设备状态、动作过程和执行结果的连续场景数据。真实运行中的故障、接管、任务失败和高风险事件,需要经过筛选、标注和结构化处理,沉淀为可检索、可复现和可重复使用的场景资产。

数据闭环将分散的模型、数据和仿真工具连接成持续研发体系。任务覆盖度、异常覆盖度、问题复现率、回归关闭率和跨版本一致性,将逐渐成为物理AI软件平台的重要评价指标。物理AI软件平台商业模式也会从单次工具采购,延伸到场景资产管理、模型生命周期管理、持续验证和安全证据链服务。

软件层的一切优化最终都要回到物理世界中验证,而硬件层正是这个闭环的起止点。

硬件基础设施层:连接真实数据与物理执行

硬件层包括能源电力、算力和IoT/OT连接基础设施。云端承担模型训练、批量仿真和数据处理,边缘节点负责现场协同与模型管理,设备端完成实时感知、推理和控制。

传感器、摄像头、雷达和设备运行系统提供真实环境数据,控制器和执行器负责把模型判断转化为物理动作。硬件层既是数据闭环的起点,也是系统执行结果的出口。

涉及车辆制动、机器人避碰和工业安全的关键任务,还需要保留本地执行、故障降级、冗余控制和人工接管能力。

中国在设备制造、通信网络、能源系统和工程实施方面具备较好基础,高端AI芯片、工业级传感器、核心零部件和复杂环境可靠性仍需持续提升。

三层架构完整就位之后,真正的挑战不在于单点突破,而在于如何让闭环从技术层面延伸到行业应用层面。

展望:从技术闭环走向行业闭环

未来几年,世界模型仍将保持多条技术路线并行,数字孪生、空间智能、仿真平台、合成数据和真实运行数据之间的连接会继续加强。模型能力的提升将扩大系统可以完成的任务范围,验证体系则负责控制进入真实环境的速度和风险。

中国拥有丰富的制造、城市运行和机器人应用场景。下一阶段需要提高软件平台的产品化水平,推动场景数据跨项目复用,加强设备接口协同,并建立覆盖模型、硬件和运行过程的评测与验证体系。

物理AI的市场差距将更多体现在系统学习效率、验证可信度、长期运行能力和跨场景复制能力。企业能否把现场问题快速转化为场景资产、验证用例和模型更新,将影响其产品迭代速度和规模化能力。

IDC将持续跟踪物理AI技术、市场和生态变化,并通过“物理AI+行业场景”的研究方式,重点关注制造业、城市物理系统和具身智能等方向,进一步分析技术架构、市场机会、厂商格局和产业化路径,为技术供应商和行业用户提供持续参考。

进一步交流

如需了解物理AI架构评估、场景落地路径或数据闭环能力诊断等研究方向,欢迎联系IDC中国物理AI与行业智能化研究团队。我们将安排对应行业分析师与您深入沟通,提供定制化决策参考。

Lily Li

Lily Li - Research Manager

Lily is the Research Manager for China Robotics and Embodied Intelligence, specializing in market research on embodied intelligent robots. She has long focused on the development trends of China’s embodied intelligence robotics industry, systematically studying the evolution of robot hardware,…

The Q1 2026 results confirm that AI infrastructure investment has moved well beyond initial proof-of-concept phases into a sustained, multi-year capital commitment cycle while the competitive battle has shifted from how much compute gets bought to which platform wins it. Enterprise technology buyers, cloud service providers, and national governments are making long term decisions about where to build, how much to spend, and which AI workloads to prioritize.

For vendors, this means a prolonged period of elevated demand across accelerated compute, high-performance storage, and supporting network infrastructure, but also a fast-moving contest for architecture leadership, as ARM rackscale platforms displace x86 in the accelerated server market. For enterprises, the data signals that AI capacity is becoming a structural cost of doing business at scale, that storage refresh deferred during the initial AI buildout can no longer be postponed, and that late movers risk falling behind on both performance and cost efficiency.

Market dynamics

  • Regional performance was mixed. The United States remained dominant at $67.9 billion (75.7% of global spend, +30.3% YoY), though growth continues to moderate. China (PRC) returned to growth at $7.8 billion (8.7% share, +9.3% YoY). The Middle East & Africa remained the fastest-growing region (+233% YoY to $1.1 billion), followed by APeJC (+62% to $5.8 billion) and Western Europe (up to $5.1 billion).
  • Accelerated compute remains the structural backbone, alongside a growing non-GPU AI-centric layer. Server spending represented 97.6% of total AI infrastructure value in Q1 2026, and within that, a growing share of AI-centric demand is landing on infrastructure that isn’t GPU-accelerated at all. AI orchestration tooling, data-pipeline workloads, and CPU-only inference clusters that hyperscalers are running as a cost-mitigation strategy alongside their GPU buildouts.
  • Deferred storage investment is catching up. After redirecting budget toward GPU and AI server spend for the past one to two years and treating storage refresh as postponable, enterprises can no longer put those purchases off. Pent-up storage refresh is now landing on top of genuine AI-driven demand, reinforcing the urgency behind external storage strategy even as AI-centric storage remains a small share (2.4%) of total AI infrastructure value.

Data callout: Q1 2026 key metrics

Total AI Infrastructure Spending (Q1 2026)$89.7 billion
Year-over-Year Growth (Q1 2026 vs. Q1 2025)+33.1%
Full-Year 2025 AI Infrastructure Spending$318 billion
Full-Year 2024 AI Infrastructure Spending$153 billion (YoY +107.6%)
Server Share of Q1 2026 AI Spending$87.6 billion (97.6%)
Storage Share of Q1 2026 AI Spending$2.2 billion (2.4%)
2029 Forecast — AI Infrastructure$1.08 trillion
Accelerated Server Platform Mix (Q1 2026)Non-x86 (ARM) $53.0B vs. x86 $34.6B
2030 Forecast — AI Infrastructure$1.21 trillion

“The Q1 2026 results make clear that AI infrastructure investment has entered a new phase where it’s not just about how much compute gets bought anymore, it’s about which platform wins it. We watched x86 accelerated servers fall from $52 billion to $35 billion in just two quarters while ARM rack-scale platforms nearly doubled, and that’s not demand destruction, that’s an architecture shift that is yet to be definitive as new x86 platforms are on the horizon as well. At the same time, we’re seeing genuine AI-driven demand show up in CPU-only inference clusters, AI orchestration tooling, and a storage refresh with a more AI-related flavor. While global economy and geopolitical tensions seem to slow down other markets, the AI investment pace continues showing an extraordinary resilience to the environment.” — Juan Seminara, Research Director, Worldwide Infrastructure Trackers, IDC

Outlook

IDC projects AI infrastructure spending will reach $497 billion in 2026, representing approximately 56% year-over-year growth; an acceleration, not a moderation, from the roughly 53% pace estimated as recently as last quarter, and still one of the largest absolute-dollar expansions ever recorded in a single IT market segment. The market is now forecast to surpass $1 trillion in 2029, reaching $1.08 trillion, before climbing to $1.21 trillion in 2030, a five-year compound annual growth rate (CAGR) of approximately 30% from 2025.

What could accelerate this trajectory:

  • Faster-than-expected scaling of inference workloads as enterprise AI application deployment broadens
  • Sovereign AI program expansion in the Middle East, Southeast Asia, and Europe, driving incremental greenfield investment
  • New model architectures and AI agent frameworks require deeper, more distributed compute infrastructure
  • Emergence of non-GPU AI-centric demand (AI orchestration tooling, data-pipeline workloads, and physical AI use cases such as robotics and autonomous vehicles) extending the addressable market beyond GPU-based training and inference

What could constrain growth:

  • Power generation and grid capacity constraints, which remain the primary operational bottleneck for new data center commissioning in major markets
  • Memory and storage component scarcity, which can lift server BOMs and slow procurement cycles, now compounded by enterprises simultaneously catching up on deferred storage refresh
  • Expanded export controls and data-sovereignty regulations, which could reshape where AI workloads are deployed and which vendors win enterprise deals
  • Geopolitical instability in the Middle East, where growth is concentrated in a small number of large, government-backed Gulf deals; escalation of regional tensions, including the ongoing conflict involving Iran, could delay procurement decisions, complicate data center siting and security planning, or shift government priorities away from AI infrastructure investment, introducing volatility to what is currently the fastest-growing region

Investors and technology buyers should monitor Q2 2026 capital expenditure guidance from leading hyperscalers and AI platform providers, as these forward signals remain the most reliable leading indicator of near-term infrastructure demand.

Frequently Asked Questions

Why did AI infrastructure growth moderate from earlier 2025 peaks?

Earlier quarters benefited from a step-change in capital deployment as hyperscalers accelerated training infrastructure buildouts, then a second step-change as ARM rack-scale platforms began displacing x86 in Q4 2025. Q1 2026’s 33% year-over-year growth reflects a much higher base, not a slowdown in demand. Sequential spending was essentially flat with Q4 2025’s record quarter. The long-term expansion cycle remains firmly intact, and IDC’s full-year 2026 forecast was revised upward, not downward, this quarter.

Which regions are emerging as new AI infrastructure centers?

The Middle East, particularly Saudi Arabia and the UAE, again posted the strongest year-over-year growth globally in Q1 2026, driven by government-backed sovereign AI initiatives and partnerships with leading hyperscalers, even as sequential spending pulled back from Q4 2025’s record deal flow. China returned to growth after a Q4 2025 decline. Western Europe and Asia/Pacific also grew sharply, supported by national AI strategies and localized cloud service provider expansion.

What risks should buyers and vendors watch in 2026?

Power availability is the single most important operational constraint heading into 2026. Data center commissioning timelines are increasingly driven by utility capacity rather than hardware lead times. In parallel, evolving trade policy, particularly around advanced GPU exports, will continue to reshape competitive dynamics across China, the Middle East, and other emerging markets. The rapid ARM/x86 platform shift also raises execution risk for x86-focused OEMs and ODMs that have not yet diversified their rack-scale roadmaps.

Have ARM servers overtaken x86 in the accelerated server market, and what’s the outlook going forward?

 Yes, Non-x86 (ARM) accelerated server value climbed to $53.0 billion in Q1 2026, up from $47.5 billion in Q4 2025 and $29.8 billion in Q3 2025, while x86 accelerated value fell to $34.6 billion from $42.7 billion and $51.9 billion over the same span. The crossover, which began in Q4 2025, reflects large buyers consolidating around NVL72/GB200-class rack-scale platforms and redistributing volume away from custom x86 rack designs. Projections will depend on how offerings evolve. Which platform ultimately prevails remains to be seen, as supply challenges across the industry persist.

For comprehensive vendor share, forecast data, and taxonomy detail, see: IDC Worldwide Quarterly AI Infrastructure Tracker. For taxonomy and methodology definitions, see: Worldwide Artificial Intelligence Infrastructure Tracker Taxonomy, 2025.

Juan Pablo Seminara

Juan Pablo Seminara - Research Director, Worldwide Enterprise Infrastructure Trackers

Juan Pablo Seminara is the Research Director for IDC's Worldwide Enterprise Infrastructure Trackers within the Data & Analytics organization. Mr. Seminara is responsible for leading a team of analysts in charge of the product concept, roadmap, implementation, execution, and client…